# Artemis Docs
> User documentation for deploying and using Artemis, including Discovery tutorials for driving Artemis through the CLI with a coding agent.
This file contains all documentation content in a single document following the llmstxt.org standard.
## FAQs
## Artemis value-add
### I can get ChatGPT to rewrite my code, why should I use Artemis?
The value-add in Artemis is in the scalability and credibility Artemis adds to the code reworking process.
While you can get ChatGPT to rewrite code, this means copying lines of code or uploading code file-by-file to ChatGPT and ctrl+c/ctrl+v-ing the reworked code back on to your codebase. This is rather cumbersome, and at the same time you have no way to verify if the code you receive is
accurate.
Artemis lets you scan entire codebases, retrieve sub-optimal code, prioritise which parts of the codebase to rework, receive improved code suggestions, and evaluate them for backward compatibility, functional correctness, security, and performance.
We visualised this to make it clearer:

### What's the difference between Artemis and Github Copilot?
See the breakdown below:

## Programming Languages
### Which programming languages does Artemis support?
Python, C++, C, Fortran, Java, JavaScript, TypeScript, Ruby, PHP, C#, Go, Swift, Kotlin, Scala, Rust, Dart, R, Lua, Perl, SQL, Elixir, Plain Text, Q, COBOL, OCaml.
## Working with LLMs
### What does Artemis do to ensure that LLM output is accurate and valid?
Artemis has incorporated a set of scorers, which check the code output of LLMs for selected criteria. See the metrics we use for scoring here: [Evaluate code versions](optimization/code-validation/code-validation-overview.md). Further, we include validation tools to ensure that code will compile. These do a check of accuracy and validity of the code output. However, we also strongly advice users to check LLM output to ensure that the code versions meet the accuracy, quality, and validity standards against their own criteria.
### What does Artemis do to mitigate LLM hallucinations?
We use multiple LLMs to generate responses, which allows us to gauge LLM output against each other. As it is highly unlikely for all LLMs to hallucinate the same way, it is easy to filter out misleading information. We also use scoring and validation techniques to evaluate the quality of the code output generated by LLMs, so that even if invalid code output is produced, they are filtered out before proceeding to next stages of the software development lifecycle.
### What does Artemis do to mitigate any risks of unfairness, bias, toxicity, abuse, or misinformation?
For code output, we include scoring and validations to check on the functional accuracy and security of the code. For the chat components, Artemis often looks at a set of code files and documents provided as sources, so that the LLMs have high-quality material to extract information. However, we do not have control over the training material used during the training process of the LLMs, and as such are unable to completely remove harmful content.
### What does Artemis do to prevent copyrighted material from being generated by LLMs and included in LLM outputs?
Artemis is able to integrate third-party tools into the platform, including tools that can monitor plagiarism in code. Based on user needs, we are able to integrate such tools into specific installations of Artemis. However, we do not have control over the training material used during the training process of the LLMs, and therefore are unable to completely guarantee the prevention of copyrighted material seeping into LLM output.
### Can Artemis change my code without my knowledge?
No, Artemis takes a developer-in-the-loop approach to code optimisation, which means a user has complete control to decide whether or not to incorporate a code change into the codebase. We provide a suite of tools to help users make informed decisions about incorporating code changes into codebases, and further encourage users to make their own accuracy and validation checks.
## Deployment
### How can I get access to Artemis?
See details on our [Deployment options](./deployment/deployment-options.md) page.
### What infrastructure do I need to install Artemis?
This depends on the nature of your deployment. For on-premise deployments, see minimum and recommended requirements on our [On-premise deployment](./deployment/on-prem/index.mdx) page.
### How much time does it take to deploy Artemis?
This will largely depend on your infrastructure and preferred mode of deployment, but roughly,
- Online deployment: 15-40 minutes
- Offline deployment: 45 minutes-1 hour
## Technical details
### How do you ensure data encryption at rest and in transit?
For data in transit, communication between services happens in an isolated network environment, so data transmission is secure. For efficiency, we don't encrypt data by default, but can do so based on client requirements.
### What are the authentication mechanisms used?
The system relies on a custom OAuth2 server flow. The authentication mechanism supports the following grants and features:
- Password Grant: Enables user login using password credentials.
- Refresh Token Grant: Allows users to obtain a new access token through a refresh token.
- Client Credentials Grant: Facilitates machine-to-machine authentication.
- JWT Usage: Enhanced security is achieved through the use of JSON Web Tokens (JWT), incorporating scopes and permissions for controlled access.
- LDAP Integration: Additionally, custom LDAP authentication is supported, providing an additional layer of security within this mechanism.
### How is role-based access control (RBAC) implemented and managed?
Role-Based Access Control is implemented with three distinct user roles, each with specific permissions and responsibilities.
### What is your backup frequency and retention policy?
This depends on each client installation. We allow the flexibility to the client to choose preferred data backup frequency and policies for data retention.
### What are your monitoring tools and practices?
- Sentry for live logs, if enabled on the client side.
- Kubernetes Dashboard that can monitor all services.
### How do customers access performance and usage reports?
Clients can access either Sentry or the Kubernetes dashboard, and they are also able to access all this information in the platform itself.
### What are the security and compliance certifications you hold (e.g ISO/IEC 27001)?
We are in the process of getting ISO/IEC 27001 and SOC2 certifications. We follow industry best practice in securing our platform. We continuously scan all our code, all the external dependencies used in the platform, and all the pre-built images. See more information on security scanning of images here: [Artemis security scanning](../docs/deployment/image-scanning-security.md).
## Security, Privacy & Data Ownership
### How does Artemis keep my code safe?
Artemis is built to keep your code isolated and protected at every step.
- **Isolated Git servers**: Your code is stored in a private, sandboxed Git environment. Nothing touches your local machine unless you explicitly approve it.
- **No training on your code**: Artemis never uses your repository data for fine-tuning or model training.
- **Controlled access**: Tasks run in containerised sandboxes with no external network access, ensuring your code never leaks.
The goal is simple: your code stays yours — isolated, encrypted, and handled with strict safeguards throughout.
### Do I own the code generated on Artemis?
Yes. You fully own the code that Artemis generates or modifies for your project. It's yours to use, edit, licence, or ship however you choose. Artemis does not claim any rights over your outputs.
### Is my code ever used for training?
No. Artemis does not use your code for fine-tuning, dataset creation, or any other form of model training.
### Does Artemis store or retain my repository data?
Artemis does not retain your repository beyond what is required to run your workflows. If you delete your project, the cloned repo and related data are removed in accordance with our data handling policy.
## Customer support
### What are your customer support hours and channels?
Artemis has a built-in customer support portal that allows users to directly send across queries/report bugs. Alternatively, support queries can also be sent to support@turintech.ai. We aim to respond to all queries within 2 business days.
Additionally, we provide a dedicated contact point (available via email/Microsoft Teams/Slack) to enterprise clients. The dedicated support personnel will work with enterprise clients to see how the platform can fit to specific workflows and use cases.
:::info Got more questions?
Write to us at support@turintech.ai. We aim to respond within 2 business days.
:::
---
## Artemis architecture
## High-level overview
This is a high-level overview of the Artemis architecture:
## Detailed Architecture
Here are additional details on the Artemis architecture:
## Glossary
### Components and APIs
#### Artemis Frontend
The Artemis web application — the pages you see in your browser. It is the only part of the platform that can be reached from outside without logging in; everything else requires authentication.
#### API Gateway
The front door for all traffic. Every request from the web app or the CLI passes through the gateway, which forwards it to the right service behind the scenes.
#### Falcon Optimisation API
The heart of the platform. Falcon keeps track of everything about your projects — the code versions Artemis generates, their scores, and their validation results — and powers the Discover module, including experiment runs and the experiment memories behind Agents Memory. It also keeps your project's repository in sync with your git provider (GitHub, GitLab, Bitbucket, or Azure DevOps) and pushes live updates to your browser as work progresses.
#### Users API
Looks after everything to do with people and access: signing up, logging in, roles and permissions, user profiles, and connecting to your company directory via LDAP.
#### Loki Task API
The platform's task coordinator. When something needs to run — a build, a test, a benchmark — Loki decides which worker or runner picks it up, and broadcasts progress updates so the UI can show live status.
#### Agent Management API
Keeps track of every AI agent run on the platform: starting them, monitoring them, and cancelling them when asked. Agents can launch other agents, and their progress is checkpointed along the way — so if a run fails, it can pick up from the last good step instead of starting over.
#### Code Warden API
The service behind the Maintain module. It stores your code-quality rules, runs AI scans of your codebase against them, keeps a record of the issues found, and kicks off AI agents to fix them.
#### Quest API
The service behind planning in the Build module. When the Planning Agent breaks your goal into a structured plan — initiatives, epics, tasks, and subtasks — Quest stores that plan, tracks how tasks depend on each other and how far along each one is, and streams the agent's output to your screen as the plan takes shape.
#### LLM API
The single door to every AI model the platform can use. It natively supports providers such as OpenAI, Anthropic, Google, AWS Bedrock, and OpenRouter, plus custom endpoints — and it's where model provider profiles, credentials, and presets are managed.
### Workers
Workers are the background processes that do the heavy lifting. They pick up tasks from a queue and report progress back to the platform.
#### Agentkit Worker
The engine that actually runs the AI agents. Whenever an agent works on your code — in Build, Maintain, Discover, or Optimise — it is an Agentkit worker doing the work, talking to the platform services and AI models along the way.
#### Celery Worker
Handles Falcon's background chores, such as checking your git provider for new commits and letting Code Warden know when the code has changed.
#### PR Create Worker
Opens pull requests on your git provider with the code changes Artemis generated.
#### Utility Worker
Prepares code suggestions for download.
### Infrastructure
#### Data stores
- **PostgreSQL** — used by most platform services as their main database, including for agent run checkpoints
- **MongoDB** — used by the Users API, the Agent Management API, and the Loki Task API for their internal data
- **Redis** — used for caching and for queueing background jobs
- **MinIO** — used for storing project files and build artefacts (S3-compatible object storage)
#### Messaging
- **Kafka** — used to stream live status updates to the UI
- **RabbitMQ** — used to hand out tasks to workers
#### Git
- **Gitea** — used to keep an internal copy of each project's repository inside the platform
#### Observability
- **Grafana Loki & Alloy** — used to collect logs from every service for monitoring and troubleshooting
### Artemis Runner
The [Artemis Runner](../features/artemis-runner.md) is a small program you run on your own hardware, outside the platform. It talks to the platform over REST: it receives build, test, and benchmark commands from the Loki Task API, executes them against a local copy of your code, and sends results, logs, and performance metrics back to the platform through Falcon.
---
## Embedding models in Artemis
| Model | Description | Cloud Provider |
|------------------------------|----------------------------------------|----------------|
| OpenAI Text Embeddings 3 Small | Small embedding model from OpenAI | OpenAI |
| OpenAI Text Embeddings 3 Large | Large embedding model from OpenAI | OpenAI |
| OpenAI Text Embeddings 3 Ada | Ada embedding model from OpenAI | OpenAI |
| Cohere English V3 | Cohere English V3 Embedding Model | Cohere |
---
## LLMs in Artemis
Artemis supports a set of built-in LLM providers out of the box. You can also bring your own LLM by configuring a custom provider profile — see [Adding a custom LLM](#adding-a-custom-llm) below.
---
## OpenAI
| LLM | Description | Cloud Provider |
|---------------|--------------------------------------------------------------------|----------------|
| GPT-5.6 Sol | High-capability GPT-5.6 variant optimized for reasoning tasks. | OpenAI |
| GPT-5.6 Terra | GPT-5.6 variant with broad knowledge and strong code generation. | OpenAI |
| GPT-5.6 Luna | Lightweight GPT-5.6 variant balancing speed and quality. | OpenAI |
| GPT-5.5 | Flagship GPT-5.5 model with advanced reasoning and creativity. | OpenAI |
| GPT-5.4 Mini | Compact GPT-5.4 variant optimized for speed and cost-efficiency. | OpenAI |
| GPT-5.4 Nano | Ultra-lightweight GPT-5.4 variant for fast, low-cost inference. | OpenAI |
## Anthropic (Claude)
| LLM | Description | Cloud Provider |
|-----------------|--------------------------------------------------------------------|----------------|
| Claude Sonnet 5 | Mid-tier Claude 5 model with balanced speed and intelligence. | Anthropic |
| Claude Opus 4.8 | High-performance Claude model with strong reasoning capabilities. | Anthropic |
## Google (Gemini)
| LLM | Description | Cloud Provider |
|------------------------|--------------------------------------------------------------------|------------------|
| Gemini 3.1 Pro Preview | Google's latest high-end multimodal model, preview release. | Google Vertex AI |
## Z.ai
| LLM | Description | Cloud Provider |
|---------|--------------------------------------------------------------------|----------------|
| GLM 5.2 | High-performance model from Z.ai with strong multilingual support. | Z.ai |
---
## Adding a custom LLM
Artemis supports bringing your own LLM provider. Configuration is done in the Artemis UI under **Settings → Models → Profiles** — no deployment config changes are needed.
**Step 1 — Create a provider profile**
Go to **Settings → Models → Profiles** and create a new profile for your LLM provider. You will need the provider's API endpoint and credentials (API key or equivalent).
**Step 2 — Add models to the profile**
Within the profile, add the specific models you want to make available. Each model entry maps a name to the provider's model identifier.
**Step 3 — Set token costs**
For each model, fill in the input and output token costs. This is required for per-user cost tracking to work correctly — profiles with missing costs will not report accurate usage.
**Step 4 — Select models under Presets**
Go to **Settings → Models → Presets** and select which models from your profile should be active. Presets control which models are available for each task type (chat, coding, scoring, etc.) across the platform.
:::note On-premise deployments
As of v3.0.0, LLM configuration has moved entirely to the UI. It is no longer part of the deployment config file.
:::
---
## Scoring models in Artemis
| Model | Description | Cloud Provider |
|------------------------------|-----------------------------------------------|----------------|
| Cohere English V3 | Cohere English V3 Reranker | Cohere |
| Mixedbread AI Embed Large V1 | The crispy sentence embedding family from Mixedbread AI. | Self-hosted |
---
## Windows Local Installation Wizard
> **Note:** This guide is specifically designed for Intel AI machines running Windows OS.
## Overview
The Artemis Windows Local Installation Wizard (`ArtemisWizard.exe`) automates the installation and configuration of Artemis on Windows systems with Intel AI hardware. The wizard performs system verification, handles Docker image management, configures OpenVINO, and sets up the Artemis platform.
## Prerequisites
### System Requirements
- **Operating System:** Windows 10 or Windows 11
- **WSL 2:** Windows Subsystem for Linux 2 enabled and configured
- **Docker Desktop:** Latest version installed and running
- **WSL Distribution:** Ubuntu Linux (latest version, see [Issue #5](#issue-5-ubuntu-version-incompatibility) for installation instructions)
- **Administrator Access:** Required for installation
### Software Dependencies
- Docker Desktop with Docker Compose
- Docker Hub account with registry access
- Intel GPU drivers (for OpenVINO)
## Installation Package
**Download:** [ArtemisWizard.exe](https://files.artemis.turintech.ai/deployment/ArtemisWizard.exe)
> **Note:** Credentials are required to access the download. Contact TurinTech for access credentials.
**Installation:** Execute `ArtemisWizard.exe` to launch the installation wizard.
## Installation Procedure
Follow the installation steps below to complete the Artemis installation.
### Step 1: System Verification
The wizard performs automated system verification to ensure the environment meets installation requirements.
**Verification Checks:**
1. **Container Environment:**
- Docker Desktop service status
- Docker Compose availability
2. **System Resources:**
- CPU core availability
- Memory capacity
- Storage space
**Default Configuration:**
- Docker Compose is included with Docker Desktop
- Docker Desktop allocates 8 CPU cores by default
- Adjust resource allocation in Docker Desktop settings if additional cores are available
**Procedure:**
1. Review verification results
2. Click **Next** to proceed
:::note
**WSL 2 Configuration:** Ensure WSL 2 is installed and enabled in Docker Desktop. Docker Desktop will prompt for WSL 2 installation if not detected.
:::
### Step 2: Authentication
The wizard authenticates with the Docker registry using preconfigured credentials.
**Prerequisites:**
- Docker Hub account with registry access
- WSL 2 installed and configured (required for Docker on Windows)
**Procedure:**
1. Verify Docker Hub registry access
2. Click **Next** to initiate Docker authentication
:::note
**Expected Behavior:** Docker Desktop may launch automatically and display a login window. Complete the authentication process before proceeding.
:::
### Step 3: Requirements
The wizard downloads all required Docker images for Artemis deployment.
**Procedure:**
1. Click **Pull Images & Continue** to download or update Docker images
2. Wait for image download to complete. All successfully downloaded images are marked with a checkmark
3. Click **Next** to proceed
### Step 4: Configuration
Configure Artemis service ports and OpenVINO deployment method.
**Port Configuration:**
| Service | Default Port | Description |
|---------|--------------|-------------|
| HTTP | 81 | HTTP service port |
| HTTPS | 443 | HTTPS service port |
> **Note:** Modify ports if conflicts exist with other applications.
**OpenVINO Deployment Method:**
**Option A: Container Runtime (Docker) — Recommended**
- **Requirements:**
- Ubuntu WSL2 Linux distribution 24.04 or later (see [Issue #5](#issue-5-ubuntu-version-incompatibility))
- Latest Intel GPU drivers
- **Procedure:** Click **Next** to proceed with containerized deployment
**Option B: Native Deployment**
- **Requirements:**
- Python 3.9–3.12
- Git installed
- Latest Intel GPU drivers
- **Procedure:**
1. Click **Run Setup** for immediate installation, or
2. Click **Create Shortcut** to create a desktop shortcut for later installation
3. Monitor installation logs for completion status
**Procedure:**
1. Configure ports and OpenVINO deployment method
2. Click **Save & Continue**
### Step 5: OpenVINO Verification
The wizard verifies OpenVINO deployment prerequisites.
**Verification Checks:**
| Component | Description |
|-----------|-------------|
| Intel GPU Driver | Validates latest Intel GPU driver installation |
| WSL Version | Verifies WSL 2 configuration |
| Linux Distribution | Checks Ubuntu distribution compatibility |
| GPU Passthrough | Validates GPU passthrough configuration |
**Procedure:**
1. Review verification results
2. Resolve any failed checks before proceeding
3. Click **Next** to continue
:::note
**OpenVINO Connection Endpoints:** Reference these endpoints when configuring OpenVINO:
- `http://host.docker.internal:8000/v3`
- `http://ovms:8000/v3`
:::
### Step 6: Installation
The wizard deploys Artemis services and creates the default administrator account.
**Deployment Procedure:**
1. Click **Start Deployment** to initiate installation
2. Wait for all services to deploy (process is automated)
**Administrator Account Setup:**
1. Enter administrator credentials:
- Username
- Password
2. Click **Create Admin User**
3. Click **Next** to continue
### Step 7: Completion
Installation is complete.
**OpenVINO Model Verification:**
The wizard performs a test query against the OpenVINO model deployment to verify functionality.
**Post-Installation:**
1. **Desktop Shortcuts:** The following shortcuts are created automatically:
- **Artemis Platform:** Launch Artemis web interface (ArtemisWizard.exe icon)
- **OpenVINO:** Launch OpenVINO (created if native deployment was selected in Step 4)
2. **Access Artemis Platform:**
- Click **Open Artemis** to launch the web interface in your default browser
- Authenticate using the administrator credentials created in Step 6
## Post-Installation Configuration
### Initial Platform Setup
Complete the following one-time configuration after first login:
1. Navigate to **Settings** (⚙️ icon, top-right)
2. Select **Users** from the sidebar
3. Locate the **System Admin Balance** column
4. Click **Edit**
5. Enter an initial balance (e.g., 50)
6. Click **Apply**
> **Note:** This configuration is required to unlock full platform functionality.
### OpenVINO Connection Verification
Verify OpenVINO model connectivity:
1. Ensure Artemis services are running
2. Log into the Artemis platform
3. Navigate to **Chat** (top-right)
4. Submit a test query
5. Verify model response to confirm successful connection
## Troubleshooting
### System Requirements
**General Requirements:**
- Docker Desktop requires WSL 2 on Windows
- Artemis supports multiple platform configurations
**OpenVINO Requirements:**
- Ubuntu 20.04 or higher (required for GPU passthrough via DXG)
- Python 3.9–3.12
- More restrictive platform requirements than Artemis core
### Common Issues
#### Issue 1: Python Version Compatibility
**Symptoms:** OpenVINO setup fails with incompatible Python version error.
**Resolution:**
1. Download Python 3.12.10 (64-bit): [Python 3.12.10](https://www.python.org/downloads/release/python-31210/)
2. Install Python and verify version (3.9–3.12)
3. Ensure Python is added to system PATH during installation
4. Restart the installation wizard
#### Issue 2: Docker Service Not Running
**Symptoms:** Installation fails with Docker-related errors.
**Resolution:**
1. Verify Docker Desktop service status
2. If issues persist, perform a full restart:
- Open Task Manager (`Ctrl + Shift + Esc`)
- Terminate all Docker-related processes
- Restart Docker Desktop
#### Issue 3: VPN Connectivity Issues
**Symptoms:** Docker or OpenVINO connectivity failures during installation.
**Resolution:**
1. Disconnect from VPN temporarily
2. Complete installation
3. Reconnect to VPN after installation
4. Configure VPN exceptions for Docker if required
#### Issue 4: Missing GPU Drivers
**Symptoms:** OpenVINO operates in CPU-only mode or fails to detect GPU.
**Resolution:**
1. In the wizard, click **Intel GPU (Required)**
2. Download the latest Intel GPU driver from the opened page
3. Install the driver
4. Return to the wizard and verify GPU detection
#### Issue 5: Ubuntu Version Incompatibility
**Symptoms:** OpenVINO fails due to unsupported Ubuntu version.
**Resolution:**
Upgrade WSL 2 Ubuntu distribution to 20.04 or later:
```bash
wsl --status
wsl --list --online
wsl --install -d Ubuntu-24.04
wsl --set-default Ubuntu-24.04
```
> **Note:** OpenVINO requires Ubuntu 20.04 or higher for GPU passthrough. Ensure GPU drivers are installed after upgrading.
## Reference
### System Requirements Summary
| Component | Requirement |
|-----------|-------------|
| Operating System | Windows 10/11 with WSL 2 |
| Docker Desktop | Latest version, running |
| WSL Distribution | Ubuntu 20.04 or later |
| Access Level | Administrator privileges |
### Registry Access
- Docker Hub account with registry access required
- WSL 2 must be installed (required for Docker on Windows)
- If WSL 2 was not installed during Docker Desktop setup, install manually before proceeding
### OpenVINO Endpoints
When configuring OpenVINO, reference these connection endpoints:
- `http://host.docker.internal:8000/v3`
- `http://ovms:8000/v3`
---
## Overview
Artemis on AI PC enables you to run Artemis entirely on your local machine using Intel AI hardware. All AI processing, including large language models (LLMs), runs locally on your device, ensuring complete privacy and data security. This section provides comprehensive guides for installing and using Artemis on Intel AI-powered Windows machines.
## What is Artemis on AI PC?
Artemis on AI PC is a local deployment solution designed specifically for Intel AI machines running Windows OS. It leverages local GPU acceleration and on-device AI models (such as Qwen 3 4B) to provide powerful code analysis, optimization, and development assistance without sending your code to external servers.
### Key Benefits
- **Complete Privacy**: All code and AI interactions remain on your local machine
- **Offline Capability**: Internet access is optional; all processing runs directly on your hardware
- **High Performance**: Leverages Intel GPU acceleration for fast AI processing
- **Full Control**: Complete control over your development environment and data
## Getting Started
### Installation
Start by installing Artemis on your Intel AI machine using the Windows Local Installation Wizard:
- **[Windows Local Installation Wizard](./local-installation-wizard.md)**: Step-by-step guide to install Artemis on Windows with WSL 2, Docker Desktop, and OpenVINO support. This wizard automates the entire setup process, from checking system requirements to deploying Artemis and creating your admin account.
## Workflows
Once Artemis is installed, you can use the following workflows to enhance your development process:
### Code Optimization
- **[Standalone Optimisation](../use-cases/local-deployment/optimisation.md)**: Improve code performance and reduce resource usage using local AI models. This workflow guides you through:
- Importing projects and creating optimization targets
- Scoring code blocks to identify optimization opportunities
- Generating optimized code versions using one-shot updates or multi-version optimization with Artemis Intelligence
- Validating and integrating optimizations into your codebase
### Code Audit
- **[Code Audit](../use-cases/local-deployment/audit.md)**: Perform comprehensive code analysis to identify security vulnerabilities, bugs, and code quality issues. This workflow covers:
- Configuring audit rules and customizing rule importance levels
- Running scans to identify code issues
- Reviewing findings and prioritizing fixes
- Automatically fixing issues using local AI assistance
- Creating pull requests to integrate fixes
### Code Exploration
- **[Agentic Chat](../use-cases/local-deployment/agentic-chat.md)**: Explore your codebase using RAG (Retrieval-Augmented Generation) powered by local embeddings and the Qwen 3 4B model. This workflow enables you to:
- Index your project for semantic code search
- Ask questions about your codebase and receive answers with file references
- Search for similar code patterns using embeddings
- Understand code relationships and dependencies
### Strategic Planning
- **[Agentic Planning](../use-cases/local-deployment/planning.md)**: Build strategic development plans using AI assistance. This workflow helps you:
- Create structured development plans from high-level prompts
- Break down features into actionable sub-plans
- Track progress and validate plan items
- Generate code and integrate plans into your Git repository
## Prerequisites
All workflows in this section require:
- **Hardware**: High-performance Intel® laptop with local GPU acceleration
- **Operating System**: Windows 10 or Windows 11 with WSL 2 enabled
- **Software**: Docker Desktop, latest Ubuntu Linux WSL distribution
- **AI Models**: Local LLM (Qwen 3 4B model recommended)
- **Internet**: Optional; all processing runs offline
## Next Steps
1. **Install Artemis**: Follow the [Windows Local Installation Wizard](./local-installation-wizard.md) to set up Artemis on your machine
2. **Choose a Workflow**: Select the workflow that matches your needs:
- Optimize existing code → [Standalone Optimisation](../use-cases/local-deployment/optimisation.md)
- Audit code for issues → [Code Audit](../use-cases/local-deployment/audit.md)
- Explore and understand code → [Agentic Chat](../use-cases/local-deployment/agentic-chat.md)
- Plan new features → [Agentic Planning](../use-cases/local-deployment/planning.md)
3. **Import Your Project**: Import your codebase into Artemis to start using these workflows
## Additional Resources
- For deployment options and configurations, see [Deployment Options](../deployment/deployment-options.md)
- For project setup and Git configuration, see [Project Setup](../project-setup/import-codebase.md)
- For troubleshooting installation issues, refer to the troubleshooting section in the [Windows Local Installation Wizard](./local-installation-wizard.md)
---
## Make a Plan
## 1. Start a new plan
In the **Build** section, switch the agent to **Plan** mode. Describe what you want to build in your own words, or pick one of the ready-made templates (Generate Benchmarks, Improve Security, Refactor the codebase, …). Choose a model, then send to start planning.

## 2. Answer the planning questions
Artemis asks targeted questions to gather the context it needs. For each one you can pick a suggested option, write your own answer, or **Skip**.

## 3. Review the plan
Artemis then proposes a plan — a summary of the approach on the right, and a **dashboard** in the middle with a progress bar and the tasks grouped by phase, each assigned to **you** or the **Agent**. Confirm the plan or ask for changes in chat.
Click **Build Plan** to run the whole plan, or run tasks individually — see [Build and validate the plan](./build-and-validate-plan.md).

Each task also has its own detail — a clear name, a description, and an AI-ready, repository-aware **prompt** you can copy or edit.
## 4. Export the plan
Export the whole plan — phases, tasks, descriptions and assignments — as **Markdown**, **CSV** or **ZIP**, or turn it straight into a **Changeset**. Handy for documentation, sharing, or reviewing.

## 5. Update the plan
Plans stay flexible. Ask the agent in chat to add, reorder, or refine tasks at any time — it asks a quick clarification, then applies the change to the plan.

---
## Next step
Once your plan is ready, continue with **[Build and validate the plan](./build-and-validate-plan.md)** to execute the tasks.
---
## Build and Validate the Plan
## 1. Run the plan
From the plan dashboard, execute the Agent-assigned tasks:
- **Run one task** — click **Open Task** (or **Start Task**) on any task; independent tasks can run in parallel.
- **Run the whole plan** — click **Build Plan** to work through every task automatically.
While it runs, each task shows its status (**Draft Ready**, **Running**, **Queued**), and you can **Stop build** at any time.

## 2. Review the changes
Open a drafted task and switch to **File changes** to see the full diff of every file it touched — review everything before you publish.

## 3. Validate the changes
Under **Validations → Run new validation**, pick your **runner** and the **commands** to run (they default to your project's build, test, and benchmark scripts — add or remove any), then click **Run validation**. If you haven't set up a runner or commands yet, see [Artemis Runner](../../features/artemis-runner.md) and [Runner and Scripts](../../project-setup/settings/runner-and-scripts.md).

Each command reports **Passed** or **Failed** — expand any check to read its full logs.

## 4. Restart if needed
If a task fails, or you simply want to redo the work, click **Restart** — it re-runs the plan and re-implements the tasks from a clean state.

---
Once you've reviewed and validated the changes, continue to **[publish them](./git-actions.md)**.
---
## Publish the Plan
After reviewing and validating your changes, open a pull request straight from Artemis.
## Create a pull request
From a task's **Create PR**, fill in the **branch name**, the branch you're **merging into**, a **title**, and a **description** — or click **Generate with AI** to have the agent write the title and description from the diff. Review the changed files below, then click **Create PR**.
*(Prefer to push without opening a PR? Use **Publish** to send the change straight to a branch.)*

Once published, the pull request appears in your Git provider as usual — review, comment, or merge it there. Artemis keeps the task's status in sync automatically as the PR is merged or closed.
---
Once all tasks are published and merged, your plan is complete. **Congratulations! 🎉**
---
## Plan Overview
**Plan Mode** in Artemis helps you turn high-level ideas into complete, structured development roadmaps. Instead of working with isolated tasks, a plan lets you break down complex goals into organized, manageable steps — perfect for shipping new features, performing major refactors, or resolving multi-step issues.
The **Artemis Web Planner** brings interactive, AI-driven planning directly to your browser. It asks focused questions to understand your intent, generates a well-structured plan without endless prompt refinement, and groups tasks into clear, logical phases. Everything is saved in **Artemis Cloud**, so your plans persist across devices, continue running even if your machine shuts down, and never interfere with your local development branches.
Whether you’re drafting a new project, preparing a multi-feature roadmap, or coordinating across teams, Plan Mode gives you a structured space to design, build, and execute your development workflow.
## **Key Features**
* **Interactive Planning** – Artemis gathers project context through targeted questions, ensuring the generated plan accurately reflects your goals.
* **Automated Task Breakdown** – High-level objectives are converted into structured subtasks that build progressively toward your final deliverable.
* **Agent & User Tasks** – Plans mix AI-driven actions with human tasks, giving you full control over where intervention, review, or domain expertise is required.
* **Built-in Workflows** – Start from prebuilt templates for common scenarios, or create your own fully customized workflows.
* **Phase-Based Task Hierarchy** – Tasks are grouped into phases with clear subtask hierarchies, making scope, dependencies, and execution order easy to understand.
* **Git Integration** – Review, validate, and publish completed tasks as pull requests with seamless Git status tracking.
* **Progress Tracking** – Visual indicators show the status of individual tasks and your plan’s overall completion.
## **Where to go next**
The planning process in Artemis is split into three clear stages:
1. **[Make a Plan](./Make-plan.md)** – Create a new plan, answer project-scoping questions, and review the generated roadmap.
2. **[Execute & Validate the Plan](./build-and-validate-plan.md)** – Execute subtasks with the agent in sandbox environment, review code changes, and validate them using your runner.
3. **[Publish the Plan](./git-actions.md)** – Publish changes to Git, create pull requests, and track sync status.
Each chapter builds on the previous one, guiding you from **planning → execution → delivery**.
---
## Chats
**Chat** mode is an interactive, conversational way to work with Artemis. Choose a model, ask anything about your project, and get real-time help — the agent has full context of your codebase (see [indexing](../features/code-indexing.md)).
## 1. Start a chat
Switch the agent to **Chat** mode, then ask a question in your own words, or pick one of the suggested prompts (Find Optimisation Targets, Project Issues Summary, Caching Opportunities, …).

## 2. Get grounded answers
Artemis replies with answers grounded in your actual code — citing the files and line ranges it's referring to — so you can explore, decide, and plan your next step.

### Use Chat to:
- **Clarify doubts** — ask about specific parts of your project, coding practices, or strategy.
- **Get continuous support** — instant answers and advice without leaving the interface.
- **Decide next steps** — suggestions for fixing bugs, adding features, or refactoring.
## Next Steps
- [Plan a bigger task](./Plan/plan-overview.md)
- [Give Artemis a coding task](./standalone)
---
## Build Overview
The **Build** section of Artemis helps you improve and extend your project with the help of agents. It has three modes — **Chat**, **Plan**, and **Code** — and in each you can pick your preferred model.
Open it by selecting your project and clicking **Build**:

### **[Chat Mode](chats.md)**
A conversational interface, powered by an LLM with full context of your project (see [indexing](../features/code-indexing.md)). Ask questions, explore your codebase, and get grounded answers — from quick questions to complex decisions.
### **[Plan Mode](plans.md)**
Turn a goal into a detailed, structured plan. Artemis asks clarifying questions, proposes tasks grouped by phase (some for you, some for the agent), then runs, validates, and publishes them.
### **[Code Mode](standalone.md)**
Hand Artemis a self-contained coding task — fix a bug, add tests, harden a security issue — and get back a reviewable diff you can validate and turn into a pull request. Issues found in the [Scan](../scan/issues.md) section can be sent straight here.
## Next Steps
- [Chat with Artemis](chats.md)
- [Make a plan](plans.md)
- [Give Artemis a coding task](standalone.md)
---
## Plans
**Plan Mode** in Artemis enables you to create comprehensive development roadmaps by working interactively with AI agents. Unlike standalone tasks that focus on immediate code changes, plans help you break down complex objectives into structured, manageable steps — perfect for implementing new features, refactoring initiatives, or bug fixes that require careful planning.
## Key Features
* **Interactive Planning** – Artemis gathers requirements by asking targeted questions about your project, ensuring a thorough understanding before generating the plan.
* **Automated Task Breakdown** – Complex objectives are automatically divided into well-defined subtasks that build incrementally toward your goal.
* **Agent & User Tasks** – Plans include both agent-automated tasks and user tasks, giving you control over which steps require human oversight.
* **Built-in Workflows** – Choose from ready-to-go plan templates for common development scenarios, or create custom plans from scratch.
* **Task hierarchy grouped by phase** - Tasks are structured into phases. Inside each phase, subtasks are presented in a clear hierarchy which gives you an organized view of scope, dependencies, and logical execution flow.
* **Git Integration** – Each completed task can be reviewed, validated, and published as a pull request with automatic Git status tracking.
* **Progress Tracking** – Monitor task completion with visual progress indicators and status updates throughout the plan execution.
## Step 1: Access the Plans Panel
Navigate to the **Build** section and click on **Plans** in the sidebar, then click **New Plan** to begin.

## Step 2: Initialize Your Plan
Enter your prompt describing what you want to build, or select from the ready-to-go plan templates. Choose your preferred model, then click the **Plan** button to start the planning process.

## Step 3: Answer Planning Questions
Artemis will ask a series of questions to gather context and requirements for your plan. You can:
* Select from suggested options
* Write custom responses
* Skip questioning by choosing "Stop questioning me and proceed with the Plan"

## Step 4: Review the Generated Plan
After gathering requirements, Artemis creates a detailed plan summary that includes:
* Project assessment and scope analysis
* Complete list of subtasks with clear descriptions
* Technical approach and reasoning
* Incremental delivery strategy
Review the plan carefully. You can:
* **Yes, proceed** – Accept the plan and move to the Plan Dashboard
* **No, let me adjust** – Request modifications to the plan
* Continue asking questions for further refinement

## Step 5: Build or download the plan
The **Plan Dashboard** displays all tasks in your plan with their current status. Each task shows:
* **Step number** and **Task Status** (completed/in progress/not started)
* **Task description**
* **Agent Status** (Not Started, Running, Draft Ready, Agent Done)
* **Git Status** (tracks PR status when tasks are published)
* **Actions** (Start Task, View Task)

### Managing Tasks
Click the **three-dot menu** next to any task to:
* **Delete Task** – Remove tasks that are no longer needed
* **Add Task Below** – Insert new tasks into the plan

### Adding Custom Tasks
When adding a task, specify:
* **Task Type** – Choose between **Agent** (automated) or **User** (manual) tasks
* **Task Name** – A clear, descriptive name that appears in the dashboard
* **Task Description** – Detailed instructions for completing the task
* **Prompt** (for Agent tasks) – The specific instructions the agent will execute

### Monitor Execution
Click **Start Task** to begin execution. The Agent Status will change to **Running**, and the button changes to **View Task**.

## Step 6: Review and validate Changes
When a task completes, the Agent Status changes to **Draft Ready**. Click **View Task** to:
* Review the generated code changes
* Validate the implementation
* Click **Publish Changes** to create a branch and pull request
Alternatively, use the three-dot menu to publish changes directly from the dashboard.

## Step 7: Git Actions
After publishing, the Git Status updates automatically to show:
* **PR Open** – Pull request has been created
* **PR Merged** – Changes have been merged into your codebase
* **Agent Done** – Task completed successfully
The progress bar at the top tracks overall plan completion.

### Viewing Pull Requests
When you publish changes, Artemis creates a detailed pull request on GitHub with:
* Clear description of changes made
* Impact analysis
* Technical implementation details

### Automatic Git Synchronization
Once you merge the pull request, the Git Status in the Plan Dashboard automatically updates to **PR Merged**, keeping your plan status in sync with your repository.

## Managing Task Status
You can manually change the status of any task by clicking on the **Task Status** icon. This allows you to mark tasks as:
* **Skipped** – For tasks that are no longer needed or relevant
* **Complete** – To manually mark tasks as completed
This is useful for managing user tasks or adjusting the plan as your project evolves.

## Plan History
All plans created for your project are saved and accessible from the Plans section. You can view:
* Active plans in progress
* Completed plans with full task history
* Search and sort through past plans

## Next Steps
- [Configure standalone builds](./standalone.md)
- [Explore chat integration](./chats.md)
- [Monitor plan performance](./overview.md)
---
## Code
Use **Code** mode in the Build section to hand Artemis a self-contained coding task — fix a bug, add tests, harden a security issue — and get back a reviewable set of changes you can validate and turn into a pull request.
## 1. Describe the task
Switch the agent to **Code** mode, describe the change you want in your own words (or pick a ready-made template such as *Fix a bug*, *Add Unit Tests for Coverage Gaps*, or *Harden Selected Security Issue*), choose a model, and send.

## 2. Review the changes
Artemis works the task and shows the result. **File changes** is a full diff of every file it touched; switch to **Validations** to run your build, test and benchmark checks. Use the **Chat** panel on the right to ask about the work.

## 3. Publish
When you're happy with it, **Create PR** to open a pull request, or **Publish** to push the change to a branch. See [Changesets](../features/changeset.md) for the full validate-and-publish flow.
## Next Steps
* [Plan a bigger task](./Plan/plan-overview.md)
* [Chat with Artemis](./chats.md)
---
## Deployment options
Currently there are five options for you to access Artemis. See details below:
### Option 1: On artemis.turintech.ai
You can access Artemis via the the web platform available at: (https://artemis.turintech.ai/). This page will prompt you to sign up for an Artemis account. Please note that to start using Artemis via the web platform, a TurinTech administrator has to verify your account.
Additional material to help you set up:
- Information regarding creating an Artemis account: [Signing up and logging in](../getting-started/signup-login.md)
- Information regarding the Artemis configuration most suitable for you: [Onboarding questionnaire](./pre-deployment-qs-saas.md)
- LLMs currently available within Artemis: [LLMs in Artemis](../architecture/llm-usage.md)
- Clarifications about Artemis value-add, working with LLMs, and other technical details: [FAQs](../FAQs.md)
- For additional queries, write to us at: support@turintech.ai
### Option 2: Deploy on premise
This is where we deploy Artemis on-premise in your organisation.
Here is additional information about on-premise deployments:
- On-premise deployment support material: [On-premise deployment guide](../deployment/on-prem/index.mdx)
- Pre-deployment questionnaire to understand your organisational needs: [Pre-deployment questionnaire](pre-deployment-qs-on-prem.md)
- Architecture diagrams: [Artemis architecture](../architecture/architecture-diagram.md)
- List of third-party services, libraries, and tools used by Artemis, with relevant licenses: [Third-party services and licenses](licenses.mdx)
- LLMs currently available within Artemis: [LLMs in Artemis](../architecture/llm-usage.md)
- Security scanning of Artemis images: [Artemis security scanning](./image-scanning-security.md)
- Clarifications about Artemis value-add, working with LLMs, and other technical details: [FAQs](../FAQs.md)
- For additional queries, write to us at: support@turintech.ai
### Option 3: Deploy on a dedicated environment on the TurinTech cloud
We are able host a temporary, secure, and dedicated Artemis environment for you on our cloud. You will be able to access the platform with a unique URL.
:::warning[In case you didn't know:]
Associated costs apply. Contact our team via your dedicated TurinTech representative or at support@turintech.ai for more information on costs.
:::
### Option 4: Deploy on your cloud
We are able to deploy Artemis on your cloud.
### Option 5: Pre-deployed on a laptop
We are able to provide you a laptop with an installation of Artemis. Contact our team via your dedicated TurinTech representative or at support@turintech.ai for details.
---
## Artemis security scanning
Artemis private images are hosted on Dockerhub, available at: https://hub.docker.com/.
We conduct continuous security scanning of all images using the following tools:
1. [Aquasecurity trivy](https://github.com/aquasecurity/trivy)
2. [Docker scout](https://docs.docker.com/scout/)
However, if you use alternative security tools, additional security vulnerability warnings might be triggered.
For more clarifications regarding our security processes, get in touch via support@turintech.ai.
---
## Third-party services and licenses
Artemis depends on the following open-source packages.
All of these libraries and tools are licensed with open source licenses.
## Packages shipped in the release images
The inventory below lists every third-party library and OS package shipped in the Artemis on-premise release images, together with its declared license. It is generated from the software bill of materials (SBOM) of the latest release, so it always reflects the version currently published.
:::tip
Package versions are intentionally omitted; the full SBOM is available to customers on request.
:::
---
## Windows Local Installation Wizard(Deployment)
> **Note:** This guide is specifically designed for Intel AI machines running Windows OS.
## Prerequisites
### Operating System
- Windows 10 or Windows 11 with WSL 2 (Windows Subsystem for Linux) enabled.
### Software
- Docker Desktop (latest version, installed and running).
- Latest Ubuntu Linux WSL distribution installed (see [issue #5](#issue-5-ubuntu-version-too-old) for installation instructions).
## Before You Begin
Download the installation wizard executable: **[ArtemisWizard.exe](https://files.artemis.turintech.ai/deployment/ArtemisWizard.exe)**
🔐 You will be provided credentials by TurinTech to access this download.
Once downloaded, run the `ArtemisWizard.exe` file to begin the setup process.
## Installation Steps
### Step 1 — Runtime and Compose
This step checks:
- Whether Docker Desktop is running.
- Whether Docker Compose is available.
Docker Compose is included by default in Docker Desktop. Once all checks are completed successfully, click **Next** to proceed.
:::note
**Important:** Double-check that WSL 2 is installed and enabled in Docker Desktop. If not already configured, Docker Desktop will prompt you to enable it.
:::
### Step 2 — System Resources
The wizard evaluates your system's available resources to ensure sufficient capacity for running Artemis.
**Requirements:**
- Adequate CPU cores
- Sufficient memory
- Available storage space
**Configuration Notes:**
- Docker Desktop typically allocates 8 CPU cores by default
- If additional cores are available, adjust Docker Desktop settings manually to allocate more resources
**Action:** Click **Next** after reviewing your system specifications.
### Step 3 — Configure Registry Access
The wizard includes preconfigured credentials for accessing the local image registry.
**Prerequisites:**
- You must be logged in to Docker Hub
- Verify registry access in Docker Hub before proceeding
- WSL 2 must be installed (required for Docker on Windows)
**WSL 2 Installation:** If you weren't prompted to install WSL 2 during Docker Desktop installation, install it manually before continuing.
**Action:** Click **Next** to sign in to Docker.
:::note
**Expected Behavior:** Docker Desktop may open automatically during this step. You should see a login window similar to the example below. You can minimize it if needed, but ensure the login completes successfully.
:::
### Step 4 — OpenVINO Requirement Check
Before proceeding, ensure your system meets the OpenVINO requirements for your chosen installation method:
- **Option A: Container Runtime (Docker) — Recommended**
- Requirements: Latest ubuntu wsl2 linux distribution ([24.04](#issue-5-ubuntu-version-too-old)) and latest intel drivers.
- If requirements are met, click **Next** to continue with the containerized OpenVINO setup.
- **Option B: Native Installation**
- Requirements: Compatible Python version (3.9–3.12), git installed and latest intel drivers.
- If requirements are met, you can either:
- Click **Run Setup** to immediately install OpenVINO natively, or
- Click **Create Shortcut** and then double-click the shortcut on your desktop to simplify launching the native installer in the future (this may take several minutes).
Monitor the installation logs for progress and confirmation of a successful setup.
#### Verify Installation in Native installation
Monitor the installation logs in the wizard for progress.
:::note
The installation process may take some time (10-15 minutes depending on your internet speed), as all required packages and dependencies are installed. The end goal is to have everything set up and ready to run.
:::
Monitor the installation logs for the following critical line:
#### Create and Test the Shortcut
1. Click **Desktop Shortcut** to create a desktop shortcut for OpenVINO
2. The OpenVINO shortcut will be created on your desktop
3. Double-click the shortcut to launch OpenVINO and wait for package installation to complete (this may take several minutes)
### Step 5 — Image Check
This step ensures you have the latest Artemis Docker images locally. Click **Pull Images** to download or update them, then **Next** to proceed.
### Step 6 — Configuration
This step allows you to customize key Artemis settings.
**Default ports:**
- HTTP: 81
- HTTPS: 443
You can change these if other applications already use them.
Choose how OpenVINO will be deployed:
- ✅ **Container Runtime checked**: Artemis will deploy OpenVINO in a container.
- ☐ **Unchecked**: Artemis expects a native OpenVINO installation running locally.
:::note
**OpenVINO Connection Endpoints:** When using OpenVINO, you may need to reference these endpoints:
- `http://host.docker.internal:8000/v3`
- `http://ovms:8000/v3`
:::
Click **Save Configuration**, then **Next** to continue.
### Step 7 — Deploy Artemis
Click **Start Deployment** to begin or update your Artemis installation. The wizard will deploy all required services automatically.
### Step 8 — Admin Setup
This step creates the default Admin User that you'll use to log into the Artemis platform.
**Action:**
1. Enter admin user credentials
2. Click **Create Admin User**
Once created, click **Next**.
### Step 9 — Complete
Deployment is complete!
A desktop shortcut to Artemis is automatically created. You can now use the provided credentials to log into the platform.
**Launch Artemis** by clicking **Open Artemis**. This will launch Artemis in your browser!
**Desktop Shortcuts Created:**
The installation wizard has created the following desktop shortcuts for easy access:
- **Artemis Platform:** Use this shortcut to launch the Artemis web interface
- **OpenVINO:** Use this shortcut to launch OpenVINO (created in Step 4)
## Platform Stability & Configuration
After first login:
1. Click the **Settings** ⚙️ icon (top-right).
2. Select **Users** from the sidebar.
3. Under the **System Admin Balance** column, click **Edit**.
4. Add an initial balance (e.g. 50) and click **Apply**.
This one-time setup step is needed to unlock the full platform functionality.
## Verifying OpenVINO Model Connection
1. Ensure Artemis is running.
2. Log into the platform.
3. Click the **Chat** icon (top-right).
4. Type a short test phrase. If OpenVINO is correctly connected, the model will respond successfully.
## Troubleshooting
### Package and Platform Requirements
#### General Requirements
- Docker Desktop on Windows requires WSL2
- Artemis can run on any platform or flavor
#### OpenVINO-Specific Requirements
- Ubuntu 20.04 or higher (for GPU passthrough via DXG). OpenVINO also has specific requirements: it will not work with Ubuntu versions lower than 20.
- Python 3.9 through 3.12
- Stricter platform requirements compared to Artemis
### Common Issues and Solutions
#### Issue 1: Python Version Compatibility
**Symptoms:** OpenVINO setup fails or reports incompatible Python version.
**Solution:**
1. Download and install Python 3.12.10 (64-bit) from the official Python website: [Python 3.12.10 (64-bit)](https://www.python.org/downloads/release/python-31210/)
2. Verify the installed version is between 3.9 and 3.12
3. Ensure Python is added to your system PATH during installation
4. Restart the wizard and try again
#### Issue 2: Docker Not Running
**Solution:**
1. Verify Docker Desktop is running
2. If issues persist, perform a complete restart:
- Open Task Manager (Ctrl + Shift + Esc)
- End all Docker-related processes
- Restart Docker Desktop
#### Issue 3: VPN Connectivity Problems
**Issue:** Docker or OpenVINO may experience connectivity issues when connected to a VPN.
**Solution:**
- Temporarily disconnect from VPN during installation
- Reconnect after installation is complete
- Configure VPN exceptions for Docker if necessary
#### Issue 4: Missing GPU Drivers
**Symptoms:** OpenVINO fails to detect GPU or shows CPU-only mode.
**Solution:**
1. In the wizard, click **Intel GPU (Required)**
2. Your browser will open to the Intel GPU driver download page
3. Download and install the latest Intel GPU driver
4. Return to the wizard and verify GPU detection
#### Issue 5: Ubuntu Version Too Old
**Issue:** OpenVINO requires Ubuntu 20.04 or higher for GPU passthrough.
**Solution:**
- Upgrade your WSL 2 Ubuntu distribution to version 20.04 or later
- Verify version and update with the following commands
```bash
wsl --status
wsl --list --online
wsl --install -d Ubuntu-24.04
wsl --set-default Ubuntu-24.04
```
For example, if the machine does not have the necessary GPU drivers installed, OpenVINO may not function correctly.
## Additional Configuration Notes
### System Requirements
- **Operating System**: Windows with WSL 2 (Windows Subsystem for Linux)
- **Docker Desktop**: Latest version installed and running
- **Administrator access** to your machine
### Registry Access
- You must be logged in to Docker Hub
- Verify registry access in Docker Hub before proceeding
- WSL 2 must be installed (required for Docker on Windows)
**WSL 2 Installation:** If you weren't prompted to install WSL 2 during Docker Desktop installation, install it manually before continuing.
### OpenVINO Connection Endpoints
When configuring OpenVINO, you may need to reference these endpoints:
- `http://host.docker.internal:8000/v3`
- `http://ovms:8000/v3`
---
## On-premise deployment guide
ReleaseBadge,
DockerComposeRelease,
KubernetesRelease,
} from "@site/src/components/ReleaseInfo";
# On-premise deployment guide
Deploy Artemis on your own infrastructure, either as a single Docker/Podman host or on a Kubernetes cluster. This page covers prerequisites and links to the latest release artifacts for both methods. For step-by-step installation, configuration, and update instructions, head to the dedicated guide for your chosen setup.
:::tip
Download URLs and image lists below are pulled live from the [release manifest](https://turintech.github.io/artemis-deployment/release.json). They always reflect the latest published version.
:::
## 1. Choose a deployment method
| Method | Best for |
| ----------------------------------------------- | ---------------------------------------------- |
| **[Single Machine / VM](./single-machine.mdx)** | Evaluation, single-host production, simple ops |
| **[Kubernetes cluster](./kubernetes.mdx)** | Multi-node production, HA, autoscaling |
## 2. Prerequisites
### Network access
The host must be able to reach:
- Your **LLM provider** API (OpenAI, Anthropic, Azure Foundry, Bedrock, Vertex, Cohere, Deepseek).
- The Artemis **file server** at `https://files.artemis.turintech.ai` to fetch the deployment package and CLI. _(Optional if artifacts are transferred manually.)_
### Hardware
| Profile | CPU | Memory | Storage |
| --------------- | -------- | ------ | -------------- |
| Minimum | 16 cores | 32 GB | 300 GB SSD/HDD |
| Recommended | 32 cores | 64 GB | 300 GB SSD/HDD |
| Self-hosted LLM | 64 cores | 128 GB | 1 TB SSD/HDD |
Self-hosted LLMs additionally require an Nvidia CUDA GPU, Intel Data Center GPU Max 1550, or Gaudi 2. See [LLM VRAM specs](https://llm.extractum.io/list/) for sizing.
If your environment cannot meet these requirements, contact support@turintech.ai for alternatives.
### Operating system
- **Single Machine / VM:** a Linux-based distribution, including Red Hat Enterprise Linux 9.0 or later, or macOS/Windows with a container runtime such as Docker or Podman.
- **Kubernetes:** any conformant cluster (cloud or on-prem), including OpenShift 4.12 or later.
### GPU drivers (optional)
Install on each GPU node:
- [NVIDIA CUDA Drivers](https://www.nvidia.com/download/index.aspx)
- [NVIDIA Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html)
### Air-gapped registries
Air-gapped deployments need a private container registry. Sonatype Nexus, JFrog Artifactory, or self-hosted Docker Registry all work. Credentials for pulling Artemis images are provided by TurinTech.
## 3. Latest artifacts
All deployment artifacts for the current release are listed below. Pick the bundle that matches your chosen method.
### Single Machine / VM
Credentials for the file server and image registry are provided separately by TurinTech.
For installation steps, see [Single Machine / VM](./single-machine.mdx).
### Kubernetes
Pick the binary matching your control machine. Save it as `cli` (or `cli.exe` on Windows) and `chmod +x` on Linux/macOS.
For installation steps, see [Kubernetes cluster](./kubernetes.mdx).
## 4. Browser support
Artemis is tested against the latest versions of **Chrome**, **Firefox**, and **Edge**. Chrome is recommended for the best experience. Older browser versions may misbehave, so keep your browser up to date.
---
## Kubernetes cluster
ReleaseBadge,
KubernetesRelease,
} from "@site/src/components/ReleaseInfo";
# Kubernetes cluster
Artemis combines public Helm charts (mostly Bitnami) with proprietary charts. A cross-platform CLI (Node.js, bundling `kubectl`, `helm`, and `skopeo`) handles configuration and deployment.
Review the [prerequisites](./index.mdx#2-prerequisites) before starting.
## 1. Supported clusters
- **Cloud:** AWS, Azure, GCP, Intel Developer Cloud, OpenShift (4.12 or later).
- **On-prem:** Kubeadm, K3s/K3d, MicroK8s, OKD, or any conformant cluster.
## 2. Latest artifacts
Pick the binary matching your control machine. Save it as `cli` (or `cli.exe` on Windows) and `chmod +x` on Linux/macOS.
## 3. Transfer images to an internal registry
Air-gapped and locked-down clusters pull every container image from your own registry instead of from TurinTech's. The `transfer.sh` helper reads the same **Container images** list shown under [latest artifacts](#2-latest-artifacts), then copies all required images into the target registry under a `turintech/` namespace, so you don't have to enumerate or tag images by hand. Pass `--type kubernetes` to select the Kubernetes image set.
Run it from a host that can reach **both** the source images and your internal registry (for fully air-gapped sites, this is typically a connected "jump" host or a DMZ mirror):
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/transfer.sh | bash -s -- --target myregistry.internal:5000 --type kubernetes
```
The script verifies access to both registries (prompting you to log in with your TurinTech credentials if needed), prints the full source → target transfer plan for confirmation, then copies each image.
### Options
| Flag | Description |
| ------------------- | ----------------------------------------------------------------------------- |
| `-t, --target` | Target registry, e.g. `myregistry.internal:5000` (**required**) |
| `-T, --type` | Image set to transfer: `docker` or `kubernetes` (**required**) |
| `-m, --method` | Transfer method: `crane` (default) or `docker` |
| `-y, --yes` | Skip all confirmation prompts; fails if not already logged in |
| `-h, --help` | Show usage |
### Transfer methods
- **`crane`** (default): copies images registry-to-registry without storing them locally, so no large local disk or running Docker daemon is required. `crane` is downloaded automatically if it isn't already on `PATH`.
- **`docker`**: uses `docker pull` / `tag` / `push`. Requires a running Docker daemon but no extra tooling.
### Non-interactive (CI / scripted)
Log in to both registries first, then pass `--yes` to skip the prompts:
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/transfer.sh | bash -s -- --target myregistry.internal:5000 --type kubernetes --method docker --yes
```
### After the transfer
Point the deployment at your registry with the following overrides in `.configrc.json` (see [Installation](#4-installation) step 6), then deploy with `--env offline`:
```json
{
"OVERRIDE": {
"REGISTRY": "myregistry.internal:5000",
"SERVICES_REGISTRY": "myregistry.internal:5000/turintech"
}
}
```
## 4. Installation
On-prem clusters pull every image from your own internal registry. The `--env offline` flag selects this environment, which resolves images against the registry configured in `.configrc.json`. Run the steps below from a machine with `kubectl` access to the target cluster.
1. Provision a cluster matching the [hardware requirements](./index.mdx#hardware).
2. Download the latest CLI from [latest artifacts](#2-latest-artifacts) and run the remaining steps from its folder.
3. **Air-gapped environments:** transfer every image listed above into your internal registry. See [Transfer images to an internal registry](#3-transfer-images-to-an-internal-registry).
4. Verify cluster connectivity:
```bash
./cli config cluster
```
5. Authenticate with the image registry:
```bash
./cli config registry-auth --env offline -u -p
```
6. **Air-gapped environments:** edit `.configrc.json` to point at your internal registry (these values match those printed by the [transfer script](#3-transfer-images-to-an-internal-registry)):
```json
{
"OVERRIDE": {
"REGISTRY": "your.internal.registry:port",
"SERVICES_REGISTRY": "your.internal.registry:port/turintech"
}
}
```
On an **OpenShift cluster**, also enable OpenShift mode (overrides can be combined in a single file):
```json
{
"OVERRIDE": {
"OPENSHIFT": "true"
}
}
```
7. Deploy:
```bash
./cli deploy up --env offline
```
8. Open Artemis at `http://:80` (or your load-balancer URL).
:::note
LLM provider credentials are not set here; they are configured from the Artemis UI after logging in.
:::
## 5. Expose Artemis (optional)
If your cluster has an ingress controller available, expose Artemis through it instead of using the node IP.
1. Apply an Ingress resource pointing at the `artemis-proxy` service. Replace `` with your Artemis namespace and `artemis.domain.foo` with the hostname you want to use. Add TLS, annotations, or `ingressClassName` as required by your controller.
```bash
kubectl apply -n -f - <<'EOF'
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
name: artemis-proxy-ingress
spec:
rules:
- host: artemis.domain.foo
http:
paths:
- path: /
pathType: Prefix
backend:
service:
name: artemis-proxy
port:
number: 80
EOF
```
2. Switch the proxy service to `ClusterIP` so traffic flows through the Ingress only. Add the override to `.configrc.json`:
```json
{
"OVERRIDE": {
"PROXY_SERVICE_TYPE": "ClusterIP"
}
}
```
3. Re-deploy the proxy to pick up the new service type:
```bash
./cli deploy up -f proxy
```
## 6. CLI reference
The deployment CLI groups commands under a few top-level verbs and shares a small set of flags. The most common ones are listed here. Run `./cli --help` or `./cli --help` for the full reference.
### Commands
| Command | Purpose |
| ------------------------------ | ------------------------------------------------------------------------ |
| `./cli config cluster` | Verify the CLI can reach the target Kubernetes cluster. |
| `./cli config registry-auth` | Save image-registry credentials for the chosen environment. |
| `./cli bundle images` | List the container images this release will install. |
| `./cli deploy up` | Install or upgrade Artemis components on the cluster. |
### Flags
| Flag | Applies to | Description |
| --------------------------------- | --------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--env offline` | `config registry-auth`, `deploy up` | Selects the `offline` environment profile, which resolves images against your internal registry per `.configrc.json`. |
| `-u`, `-p` | `config registry-auth` | Registry username and password (or token). |
| `-g ` | `deploy up` | Limit the deploy to a component group. Repeatable. Common groups: `worker`, `component`. Omit to reconcile the entire stack. |
| `-f ` | `deploy up` | Limit the deploy to a single component (e.g. `proxy`). Useful after a targeted override like `PROXY_SERVICE_TYPE`. |
## 7. Update
1. Download the latest CLI from [latest artifacts](#2-latest-artifacts). Copy the `.configrc.json` from your previous deployment into the same folder as the new CLI so your registry and override settings persist across the upgrade.
2. **Air-gapped environments:** mirror the new release's images to your internal registry. Re-run the [transfer script](#3-transfer-images-to-an-internal-registry) to copy them across.
3. Delete the existing `assets` folder, which sits next to the `cli` binary. It is safe to remove; the CLI regenerates it on the next deploy. Do **not** delete `.configrc.json` in the same folder, as it holds your personalised deployment configuration (registry and overrides) and is not regenerated.
4. Apply the update: `./cli deploy up -g worker -g component`
:::note
`./cli deploy up -g worker -g component` upgrades only the Artemis workers and application components, leaving shared infrastructure (databases, MinIO, Redis, etc.) untouched. This is the recommended path for routine version upgrades.
`./cli deploy up` (no flags) reconciles the entire stack, including bundled infrastructure. Use it for a fresh install or when a release explicitly requires infrastructure changes.
:::
---
## Single Machine / VM
ReleaseBadge,
DockerComposeRelease,
DockerComposeDownloadCommand,
ReleaseVersion,
} from "@site/src/components/ReleaseInfo";
# Single Machine / VM
Artemis ships as a set of Docker Compose files managed by the `./artemis` CLI (works with both `docker compose` and `podman compose`).
Review the [prerequisites](./index.mdx#2-prerequisites) before starting.
## 1. Supported operating systems
- Any Linux-based distribution, including Red Hat Enterprise Linux 9.0 or later.
- macOS or Windows with a container runtime such as Docker or Podman.
## 2. Runtime
Install one of:
- [Docker](https://docs.docker.com/engine/install/)
- [Podman](https://podman.io/docs/installation)
## 3. Latest artifacts
Credentials for the file server and image registry are provided separately by TurinTech.
## 4. Transfer images to an internal registry
Air-gapped and locked-down deployments pull every container image from your own registry instead of from TurinTech's. The `transfer.sh` helper reads the same **Container images** list shown under [latest artifacts](#3-latest-artifacts), then copies all required images into the target registry under a `turintech/` namespace, so you don't have to enumerate or tag images by hand.
Run it from a host that can reach **both** the source images and your internal registry (for fully air-gapped sites, this is typically a connected "jump" host or a DMZ mirror):
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/transfer.sh | bash -s -- --target myregistry.internal:5000 --type docker
```
The script verifies access to both registries (prompting you to log in with your TurinTech credentials if needed), prints the full source → target transfer plan for confirmation, then copies each image.
### Options
| Flag | Description |
| ------------------- | ----------------------------------------------------------------------------- |
| `-t, --target` | Target registry, e.g. `myregistry.internal:5000` (**required**) |
| `-T, --type` | Image set to transfer: `docker` or `kubernetes` (**required**) |
| `-m, --method` | Transfer method: `crane` (default) or `docker` |
| `-y, --yes` | Skip all confirmation prompts; fails if not already logged in |
| `-h, --help` | Show usage |
### Transfer methods
- **`crane`** (default): copies images registry-to-registry without storing them locally, so no large local disk or running Docker daemon is required. `crane` is downloaded automatically if it isn't already on `PATH`.
- **`docker`**: uses `docker pull` / `tag` / `push`. Requires a running Docker daemon but no extra tooling.
### Non-interactive (CI / scripted)
Log in to both registries first, then pass `--yes` to skip the prompts:
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/transfer.sh | bash -s -- --target myregistry.internal:5000 --type docker --method docker --yes
```
### After the transfer
Point the deployment at your registry by setting the following in `.env.custom`, then run `./artemis deploy`:
```env
REGISTRY=myregistry.internal:5000
SERVICES_REGISTRY=myregistry.internal:5000/turintech
```
## 5. Installation
### Automated (recommended)
Run the installer with the credentials provided by TurinTech. It logs in to the container registry, downloads the deployment package, deploys all services, and creates the default admin user in one step:
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/install.sh | bash -s -- --username --password --registry-username --registry-password
```
TurinTech provides all four credentials. `--registry-username` and `--registry-password` are optional if Docker is already authenticated with the registry (for example, after a previous `docker login`). The installer creates an `artemis-/` folder in the current directory. When it finishes, Artemis is running and the admin credentials are printed to the terminal.
LLM provider credentials are configured from the Artemis UI after logging in, so no additional deployment configuration is needed for them.
:::tip
Pass `--skip-deploy` if you want to review or edit `.env.custom` before the first deployment:
```bash
curl -fsSL https://turintech.github.io/artemis-deployment/install.sh | bash -s -- --username --password --registry-username --registry-password --skip-deploy
```
Then edit `artemis-/.env.custom` and run `./artemis deploy && ./artemis create-users` manually.
:::
### Manual
The flow is the same for online and air-gapped deployments. Steps marked **Air-gapped only** apply when the host has no internet access; skip them otherwise.
1. Provision a VM matching the [hardware requirements](./index.mdx#hardware).
2. **Air-gapped only:** transfer every image listed under [container images](#3-latest-artifacts) into your internal registry. See [Transfer images to an internal registry](#4-transfer-images-to-an-internal-registry).
3. Authenticate with the image registry:
- Online: `docker login --username --password `
- Air-gapped: `docker login your.internal.registry:5000`
4. Download the deployment package and extract it (uses the credentials provided by TurinTech):
Then move into the extracted folder: {"cd artemis-"}.
5. **Air-gapped only:** edit `.env.custom` to point at your internal registry (this matches the values printed by the [transfer script](#4-transfer-images-to-an-internal-registry)):
```env
REGISTRY=your.internal.registry:port
SERVICES_REGISTRY=your.internal.registry:port/turintech
```
6. Deploy Artemis:
```bash
./artemis deploy
```
7. Create the admin user:
```bash
./artemis create-users
```
8. Open Artemis at `http://:80`.
:::note
Run `./artemis info` from the deployment folder to view the admin credentials you need to log in.
:::
## 6. CLI reference
All operations are done with the `./artemis` script from inside the deployment folder.
| Command | Description |
| ---------------------------------------------- | ------------------------------------------------- |
| `./artemis` | List all available commands |
| `./artemis info` | Show VM details and admin credentials |
| `./artemis images` | List the images used by the deployment |
| `./artemis deploy` | Deploy or update all services |
| `./artemis deploy ` | Deploy a single service |
| `./artemis status` | Show health status of all containers |
| `./artemis logs` | Follow logs for all services |
| `./artemis logs ` | Follow logs for a specific service |
| `./artemis restart` | Restart all containers |
| `./artemis down` | Stop all containers |
| `./artemis destroy` | Remove containers and volumes |
| `./artemis update` | Check for a new version and update |
## 7. Configuration
All customisation goes into `.env.custom` in the deployment folder. This file is never overwritten by updates or re-installs, so your changes persist across versions.
:::warning
Do not edit the base `.env` file; it is reset on every update. Always use `.env.custom`.
:::
:::note
LLM provider credentials are not set here; they are configured from the Artemis UI after logging in.
:::
## 8. Update
### Automated
Run from inside the current deployment folder. The script checks for a newer version, prompts for confirmation, downloads it, and re-deploys your `.env.custom` and `keys/` are carried over automatically:
```bash
./artemis update
```
### Manual
1. Download the new deployment package and extract it:
2. **Air-gapped:** ensure the new [container images](#3-latest-artifacts) are in your internal registry. Re-run the [transfer script](#4-transfer-images-to-an-internal-registry) to copy the new release's images across.
3. Move into the new folder and deploy:
{"cd artemis-"}{" && ./artemis deploy"}
4. Open Artemis at `http://:80`.
:::note
Run `./artemis info` from the deployment folder to view the admin credentials.
:::
:::note
Check the release notes for any new environment variables, and add them to `.env.custom` if needed.
:::
---
## Pre-deployment questionnaire
1. What is your preferred mode of accessing the platform, out of the following:
a. On-premise, on a Kubernetes cluster
b. On-premise, Docker-based deployment
c. On-premise, OpenShift-based deployment
d. Deployed on your cloud
e. Deployed on the TurinTech cloud, with unique URL
f. Pre-deployed on a laptop
*(Mandatory)*
2. How many users will be using the platform? *(Mandatory)*
3. What is the level of permissions that can be provided to your infrastructure?
a. Kubernetes cluster access only
b. IAM User
c. SSH, if bare-metal deployment
*(Mandatory)*
4. Will Artemis be deployed in a custom domain? If yes, where is the domain located (e.g. Route 53)?
*(Mandatory)*
1. Does it need to be restricted to specific IPs or an internal network?
*(Mandatory)*
1. What is the estimated monthly cost on the cloud of choice for the default proposed deployment? (Mandatory)*
2. Will you be restarting the Kubernetes cluster or the machines used to deploy the platform? If yes, how often will this happen? *(Mandatory)*
3. Do you need the ability to execute code? If yes,
a. Would any internal libraries need to be used?
b. Approximately how many users would run code at the same time?
*(Mandatory)*
1. What Git / Version Control environment are you using? *(Mandatory)*
2. Is self-hosting of any LLMs required? *(Mandatory)*
3. If any non self-hosted LLMs are being used,
a. Is an API key for each going to be provided?
b. If a custom LLM service is going to be provided, what is the input and output format and way to access it?
See a list of LLMs provided by Artemis here: [LLMs provided by Artemis](../architecture/llm-usage.md)
*(Mandatory)*
4. What programming languages are you planning to use?
a. Which version of each?
*(Optional)*
---
## SaaS onboarding questionnaire
1. How many users will be using Artemis?
2. What code languages do you wish to evaluate/optimise using Artemis?
3. What is your primary purpose of using Artemis:
a. **Code audit**: Evaluate codebases to get a high-level overview of code health;
b. **Code optimisation suggestions**: Audit a codebase and receive potential improvement suggestions;
c. **End-to-end optimisation**: Run a code optimisation end-to-end, where you identify potential inefficiencies in the codebase, generate improved code snippets, and compile and test the code to ensure validity.
4. If you chose option c. for question 3. above:
a. Are you able to provide a codebase that already compiles?
*Please note that if your code does not already compile, Artemis may not be able to provide suggestions that can be validated.*
b. Are you able to provide unit tests and benchmarking tests?
*Please note that if you do not have unit tests or benchmarking tests, Artemis may not be able to generate credible optimisation metrics, i.e. runtime, CPU, memory improvement metrics.*
c. Does your code depend on any internal libraries?
*If your code depends on internal libraries, we may have to custom setup access to your build environment to compile and validate code, which may require additional time and effort.*
:::tip Get in touch
Send in your responses to support@turintech.ai to discuss how you can proceed with using the platform. We aim to respond within 2 business days.
:::
---
## Pre-deployment questionnaire(Deployment)
1. What is your preferred mode of accessing the platform, out of the following:
a. On-premise, on a Kubernetes cluster
b. On-premise, Docker-based deployment
c. On-premise, OpenShift-based deployment
d. Deployed on your cloud
e. Deployed on the TurinTech cloud, with unique URL
f. Pre-deployed on a laptop
*(Mandatory)*
2. How many users will be using the platform? *(Mandatory)*
3. What is the level of permissions that can be provided to your infrastructure?
a. Kubernetes cluster access only
b. IAM User
c. SSH, if bare-metal deployment
*(Mandatory)*
4. Will Artemis be deployed in a custom domain? If yes, where is the domain located (e.g. Route 53)? *(Mandatory)*
5. Does it need to be restricted to specific IPs or an internal network?
*(Mandatory)*
6. What is the estimated monthly cost on the cloud of choice for the default proposed deployment? *(Mandatory)*
7. Will you be restarting the Kubernetes cluster or the machines used to deploy the platform? If yes, how often will this happen? *(Mandatory)*
8. Do you need the ability to execute code? If yes,
a. Would any internal libraries need to be used?
b. Approximately how many users would run code at the same time?
*(Mandatory)*
9. What Git / Version Control environment are you using? *(Mandatory)*
10. Is self-hosting of any LLMs required? *(Mandatory)*
11. If any non self-hosted LLMs are being used,
a. Is an API key for each going to be provided?
b. If a custom LLM service is going to be provided, what is the input and output format and way to access it?
See a list of LLMs provided by Artemis here: [LLMs provided by Artemis](../architecture/llm-usage.md)
*(Mandatory)*
12. What programming languages are you planning to use?
a. Which version of each?
*(Optional)*
---
## Artemis Runner
The Artemis Runner is now distributed as a single **self-contained binary**, per operating system and architecture — no Python or tools bundle required.
The easiest way to get the exact download command is from the **New Artemis runner** panel in the Artemis web console (**Platform Settings → Runners → New Artemis runner**). Pick your **OS** and **architecture** and it fills in the current version, download command, and a single-use registration token for you.

For the full walkthrough (download → configure → start), see the [Artemis Runner](../features/artemis-runner.md) guide. This page is a reference for downloading specific versions directly.
## Latest release (5.2.0)
Linux and Windows ship as **self-contained binaries**; macOS is distributed as a **Python wheels** archive (requires **Python 3.11** and pip). All downloads are **public** — no credentials required.
| OS | Download |
|---|---|
| **Linux** (x64) | [artemis-runner-5.2.0-linux](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.2.0-linux) — standalone binary |
| **Windows** (x64) | [artemis-runner-5.2.0-windows.exe](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.2.0-windows.exe) — standalone binary |
| **macOS** | [artemis-runner-5.2.0-wheels.tar.gz](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.2.0-wheels.tar.gz) — Python wheels |
On Linux/Windows, download the binary and run it directly. On **macOS**, extract the wheels archive and install it into a virtual environment:
```bash
tar -xzf artemis-runner-5.2.0-wheels.tar.gz
cd artemis-runner-*-wheels
python3.11 -m venv .venv && source .venv/bin/activate
pip install --find-links wheels/ artemis-runner
```
Then `artemis-runner configure …` and `artemis-runner start` work the same on every platform. Keep the runner up to date with `artemis-runner upgrade`.
## Legacy Releases
### 5.1.1
- Linux (x64): [artemis-runner-5.1.1-linux](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.1-linux)
- Windows (x64): [artemis-runner-5.1.1-windows.exe](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.1-windows.exe)
- Wheels (other platforms): [artemis-runner-5.1.1-wheels.tar.gz](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.1-wheels.tar.gz)
### 5.1.0
- Linux (x64): [artemis-runner-5.1.0-linux](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.0-linux)
- Windows (x64): [artemis-runner-5.1.0-windows.exe](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.0-windows.exe)
- Wheels (other platforms): [artemis-runner-5.1.0-wheels.tar.gz](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.1.0-wheels.tar.gz)
### 5.0.0
- Linux (x64): [artemis-runner-5.0.0-linux](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.0.0-linux)
- Windows (x64): [artemis-runner-5.0.0-windows.exe](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.0.0-windows.exe)
- Wheels (other platforms): [artemis-runner-5.0.0-wheels.tar.gz](https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.0.0-wheels.tar.gz)
---
## Artemis Skills
Skills are Claude Code plugins that guide you through setting up and configuring Artemis — directly from your terminal. They are powered by the [turintech/skills](https://github.com/turintech/skills) marketplace.
---
## Installation
Add the TurinTech AI skills marketplace and install the Artemis plugin in Claude Code.

### Prerequisites
Ensure you have Claude Code installed and running:
- Claude Code CLI
- Active internet connection
### 1. Add the marketplace
Register the TurinTech AI skills marketplace in Claude Code:
```
/plugin marketplace add turintech/skills
```
### 2. Install the Artemis plugin
Install the Artemis plugin, which includes all available skills:
```
/plugin install artemis@skills
```
### 3. Verify installation
Check that the skills are available by listing installed plugins:
```
/plugin list
```
---
## Available Skills
Once installed, these skills are available as slash commands in Claude Code:
| Skill | Description |
|---|---|
| `/repo-setup` | Set up a repository for Artemis execution — configure build, test, and benchmark commands with `artemis_results`. |
| `/runner-setup` | Install and configure the Artemis runner on a machine. |
| `artemis` | Classify a request, check workflow readiness, and route to the right skill. |
| `cli-setup` | Install, update, and authenticate the Artemis CLI. |
| `runner-setup` | Install, register, start, update, and verify a runner. |
| `repo-prepare-fork` | Fork or privately mirror an upstream repository the user does not control, pinned to a known commit. |
| `repo-command-setup` | Derive and verify compile, test, and benchmark commands, including numeric `artemis_results` metrics. |
| `project-import` | Import a remote Git branch as a fresh Artemis project and capture its UUID. |
| `discovery-start` | Create a Discovery run with inline commands, wait for the baseline, and confirm exploration started. |
| `discovery-inspect` | Interpret a Discovery run: status, versions, metrics, and what the winning diff actually changed. |
| `discovery-steer` | Continue, expand the budget, or redirect a live Discovery run. |
| `maintain` | Run Maintain end to end: rules, scan, triage, fix, ship, and resync. |
---
## Updating
Keep your skills up to date with the latest changes:
```
/plugin marketplace update skills
```
---
## Using `/repo-setup`
Run `/repo-setup` inside Claude Code to automatically configure your project's build, test, and benchmark commands. The skill analyses your repository, detects your build system and hardware, and writes the correct commands to your Artemis project settings.
Push the resulting changes to Git — Artemis syncs automatically.
:::tip
You can also trigger this from the Execution settings page in Artemis using the **Agent Skill → View setup guide** option. See [Project Settings](../project-setup/settings/runner-and-scripts.md).
:::
---
## Artemis CLI
Command-line interface for the Artemis AI code platform.
The Artemis CLI drives the full Artemis platform from your terminal: import repositories, run AI-driven evolutionary discovery, build with AI agents, scan and fix code-health issues, and ship the results as pull requests. It is built for both humans and LLM agents — every command runs non-interactively and can emit structured JSON — which makes it ideal for scripting, CI/CD pipelines, and agent-driven workflows (e.g. Claude Code) as well as day-to-day terminal use.
---
## Install the Artemis CLI
### Prerequisites
- macOS, Linux, or Windows
- A bash shell on macOS/Linux, or PowerShell 5.0+ on Windows
- Internet connection for download and API access
- An Artemis API key — generate one from the Artemis web UI
### 1. Download and run the installer
The installer downloads the right `artemis` binary for your OS and architecture, verifies its checksum, installs it to `~/.local/bin`, and points the CLI at your Artemis deployment. Two independent choices are available:
- **Which build to install** — `--version ` (a specific release), `--nightly` (newest release including prereleases), or `--dev` (the rolling development build). The default is the newest stable release. The three are mutually exclusive.
- **Which deployment to talk to** — `--env prod` (the hosted Artemis platform, and the default), or `--base-url ` for an on-prem/custom deployment.
```bash
curl -L --digest -u "Artemis_User:Artemis_Custom_Runner_2025" \
"https://files.artemis.turintech.ai/artemis-cli/latest/artemis-cli-installer.sh" \
-o installer.sh && chmod +x installer.sh && ./installer.sh --env prod
```
**On-premise / custom deployment**
```bash
curl -L --digest -u "Artemis_User:Artemis_Custom_Runner_2025" \
"https://files.artemis.turintech.ai/artemis-cli/latest/artemis-cli-installer.sh" \
-o installer.sh && chmod +x installer.sh \
&& ./installer.sh --base-url https://your-custom.artemis.turintech.ai
```
**Install a specific version, or a pre-release build**
```bash
./installer.sh --version 2.3.0 --env prod # a specific stable release
./installer.sh --nightly --env prod # newest build incl. prereleases
./installer.sh --dev --env prod # rolling development build
```
Other installer flags: `--install-dir ` (default `~/.local/bin`) and `--help`.
:::note
If `~/.local/bin` is not on your `PATH`, the installer prints the line to add to your shell profile. Reload your shell (or `source ~/.bashrc`) and `artemis` will be available everywhere.
:::
### Alternative: download the binary directly
For CI images, containers, or air-gapped setups, download the binary yourself:
```bash
curl -L --digest -u "Artemis_User:Artemis_Custom_Runner_2025" \
"https://files.artemis.turintech.ai/artemis-cli/latest/artemis-cli-linux-amd64" \
-o artemis && chmod +x artemis
```
Swap `artemis-cli-linux-amd64` for `artemis-cli-linux-arm64`, `artemis-cli-darwin-amd64`, `artemis-cli-darwin-arm64`, or `artemis-cli-windows-amd64.exe` as needed, and swap `latest` for `nightly`, `dev`, or a version like `2.3.0`. Each channel directory also carries a `checksums.txt`. When you download the binary directly the installer hasn't configured anything — set the deployment yourself in the next step.
### 2. Connect and authenticate
`artemis login` points the CLI at a deployment and stores your API key. It writes exactly two values — `ARTEMIS_BASE_URL` and `ARTEMIS_API_KEY` — and every service endpoint is derived from that single base URL. The command verifies the URL is reachable and validates the key against it before storing either.
```bash
# Interactive — prompts for the deployment URL and API key
artemis login
# Non-interactive — pass prod (hosted Artemis) or a full URL
artemis login --url prod --api-key
artemis login --url https://your-custom.artemis.turintech.ai --api-key
```
The installer already set the base URL, so after running it you can simply supply the key:
```bash
artemis login --api-key
```
API keys are per-deployment: changing the URL clears any previously stored key. `artemis logout` removes the stored API key but keeps the base URL.
### 3. Verify
```bash
artemis status
```
`status` reports your configuration, whether you're authenticated, and health-checks each derived service endpoint. It exits non-zero if the configuration is invalid or no API key is set, so scripts can gate on it.
---
## Environments
If you work against more than one deployment — a dev box, staging, and production — `artemis env` gives you kubectl-style contexts instead of re-running `login` each time. Each environment is its own config file under the user config directory (`envs/.env`) holding that deployment's URL and API key, and the selected one is what `login`, `config set`, and every other command read and write.
```bash
# Create environments and switch between them
artemis env add staging --url stg --api-key
artemis env add production --url prod --use
artemis env use staging
# Where am I?
artemis env current
artemis env list
# One-off command against another environment
ARTEMIS_ENV=production artemis project list
# Back to the pre-environments config
artemis env use default
artemis env remove staging
```
`env add --url` takes a full base URL or a named deployment; the API key can be supplied here or set later by switching to the environment and running `artemis login`.
:::note
Environments are entirely opt-in. Until you create one, the CLI keeps using its single default config exactly as before, and the name `default` always refers to that config.
:::
---
## Feature Overview
The CLI is organized into command groups, grouped by workflow stage.
### Getting Started
| Command | What It Does |
|---------|--------------|
| `login` / `logout` | Connect the CLI to a deployment and store/remove your API key |
| `status` | Show configuration and connectivity status |
| `env` | Switch between deployments (named environments) |
| `config` | Show, set, or edit configuration values |
| `tui` | Launch the interactive terminal dashboard |
### Optimise
| Command | What It Does |
|---------|--------------|
| `project` | Import and manage Git repositories |
| `changeset` | Inspect, validate, publish, and ship the staged code changes behind PRs |
### Build with AI
| Command | What It Does |
|---------|--------------|
| `discovery` | AI-driven evolutionary code discovery |
| `task` | Create and execute AI coding tasks (single work items) |
| `plan` | Break complex features into structured tasks with AI |
| `chat` | AI-powered conversations about your codebase |
### Maintain
| Command | What It Does |
|---------|--------------|
| `maintain` | Scan, triage, and fix code-health issues, then ship the fixes |
### Resources
| Command | What It Does |
|---------|--------------|
| `context` | Manage durable context injected into your agents |
| `key` | Manage Git authentication keys |
| `runner` | View the Artemis Runner fleet |
| `model` | View available LLM models and manage registered model entries |
| `profile` | Manage the platform's LLM provider connections |
| `process` | Inspect background processes started by async commands |
| `logs` | Browse the platform's own service logs (admin-only) |
| `version` | Print CLI version information |
Run `artemis --help` for full details on any group or subcommand.
---
## Conventions
Every command follows the same house rules, which make the CLI predictable for both people and agents:
- **Structured output.** Add `--output-format json` to any command to get one JSON document on stdout; human-readable progress and errors go to stderr. The default is `text`.
- **ID or name.** Wherever a command takes `-p, --project`, you can pass either the project ID or its name. Name resolution is scoped to your user; on an ambiguous name the CLI lists the candidates rather than guessing.
- **Positional IDs.** The primary resource ID is a positional argument (`artemis discovery get `), not a flag.
- **Pagination.** List commands accept `--page` / `--per-page`, and `--all` to fetch and aggregate every page.
- **Long-running ops.** Async commands accept `--wait` (block until a terminal state) and `--timeout` (default 20m). A wait that times out exits with code 6.
- **Destructive ops.** Commands that delete or overwrite accept `-f, --force` to skip the confirmation prompt.
- **Interactive when interactive.** Commands whose agent can ask a question (`plan create`, `plan respond`, `maintain rules create`, `maintain chat`) prompt at a terminal, and fall back to `--answer` / `-m` flags or a single request/response turn when piped — so the same command works for a person and for an agent driving the CLI.
### Global flags
| Flag | Description |
|------|-------------|
| `--debug` | Enable verbose debug output |
| `--config ` | Path to the config file (default: `./.env` if present, else the selected environment's file) |
| `--output-format ` | `text` (default) or `json` |
| `-h`, `--help` | Show help for the command |
### Exit codes
| Code | Meaning |
|------|---------|
| 0 | Success |
| 1 | Generic error |
| 3 | Authentication error (HTTP 401/403) |
| 4 | Not found (HTTP 404) |
| 5 | Server error (HTTP 5xx) |
| 6 | Wait timed out (`--wait` / `--timeout` expired) |
---
## Typical Workflow
A complete end-to-end run, from an empty account to a pull request:
```bash
# 1. SETUP — verify your connection
artemis status
# 2. ADD A GIT KEY — register your Personal Access Token
artemis key add --name "github-work" --provider github --token
# 3. IMPORT A PROJECT — clone a repo into Artemis
artemis project import \
--git-url https://github.com/your-org/your-repo.git \
--key-id
# 4. SET BUILD COMMANDS — what a runner executes to compile, test, benchmark
artemis project commands set --project \
--compile "go build ./..." --test "go test ./..." --benchmark "go test -bench=."
# 5. CHECK THE COMMANDS WORK — validate the unmodified code on a runner
artemis changeset create --project --name "baseline"
artemis changeset validate --project \
--version original --runner my-runner --wait
# 6. DISCOVER — run the AI optimisation loop against a task
artemis discovery create --project \
--task "Reduce p99 latency of the request path" \
--model --target-files src/server.go \
--versions 10 --runner my-runner
# 7. INSPECT — review what the agent produced and how it scored
artemis discovery get
artemis discovery versions list
artemis discovery metrics --stats
# 8. SHIP — open a pull request from the winning changeset
artemis changeset list --project
artemis changeset pr --project --title "Performance improvements"
```
---
## Discovery
**Discovery** is Artemis's continuous AI-driven optimisation loop. An agent proposes **experiments** (testable hypotheses about what might improve the code), implements each attempt as a code **version**, executes it on a runner, and scores it against the run's metric schema — bounded by the run's version budget.
| Entity | What it is |
|--------|-----------|
| run | The top-level optimisation loop for a task |
| experiment | A testable hypothesis, concluded validated / refuted / inconclusive |
| version | A generated code candidate, executed and scored by fitness |
| baseline | The unmodified code, executed once to anchor metric comparisons |
| metrics | Recorded metric values for the run's executed versions |
### Starting a run
Execution runs (the default) measure a baseline and run each generated version, so they need a benchmark command and a [runner](./artemis-runner.md). The project's stored build commands are used as defaults, matching the UI; `--compile-cmd` / `--test-cmd` / `--benchmark-cmd` override them. With `--skip-execution`, versions are graded by review instead and no commands or runner are needed.
```bash
# Minimal run — no commands or runner needed
artemis discovery create --project \
--task "Speed up JSON parsing" --model --skip-execution
# Full configuration
artemis discovery create --project \
--task "Reduce p99 latency" \
--model \
--target-files src/handler.go --target-files src/cache.go \
--versions 10 \
--compile-cmd "go build ./..." \
--test-cmd "go test ./..." \
--benchmark-cmd "go test -bench=." \
--runner my-runner --mode automatic
```
`--model` is required — the API does not pick a default. It takes a model-catalogue UUID or a model-type code (see [Models](#models-and-providers)). `--target-files` and `--review-model` are repeatable.
### Following and steering a run
```bash
artemis discovery list --project
artemis discovery get
artemis discovery versions list
artemis discovery versions logs
artemis discovery experiments list --status validated
# Redirect an active agent mid-run
artemis discovery steer --message "Focus on algorithmic changes, don't touch build flags"
# Extend a finished run's version budget
artemis discovery continue --versions 5
# Change a run's commands, runner, or status
artemis discovery update --runner other-runner
artemis discovery cancel
```
### Metrics and fitness
Each metric is measured once per benchmark repetition, so a metric can have many raw samples per version. `metrics` lists the individual samples by default; `--stats` shows the summary statistics over them — mean, standard deviation, standard error, min, max, sample count, and improvement against the baseline — the same numbers the UI shows.
```bash
artemis discovery metrics
artemis discovery metrics --stats --all
# Replace the run's fitness metric schema and recompute version fitness
artemis discovery metrics-schema set --file schema.json
# Set or (re)execute the baseline
artemis discovery baseline set --metrics-schema schema.json
artemis discovery baseline execute
```
A metric schema is a JSON array of metric descriptors:
```json
[
{"metricId": "", "source": "worker", "higherIsBetter": false, "importance": 0.7},
{"metricId": "", "source": "agent", "higherIsBetter": true, "importance": 0.3,
"description": "Code readability", "extractionHint": "Judge naming and structure"}
]
```
Discovery also exposes `experiments create/update/delete` and `versions create/execute/update` for finer control — see `artemis discovery --help`.
---
## Changesets and validation
A **changeset** is the staged set of code changes that discovery runs, tasks, plans, chats, and maintain fixes produce before they become pull requests. Your git remote stays untouched until you publish a branch or open a PR. See [Changesets](./changeset.md) for the UI equivalent.
```bash
artemis changeset list --project
artemis changeset get --project
artemis changeset diff --project --stat
artemis changeset diff --project --base --head
```
### Validation
`changeset validate` runs a version's compile, test, and benchmark commands on a [runner](./artemis-runner.md). This is the same primitive discovery uses to evaluate every version it generates, including the baseline — so it's the exact code path real runs take, not an approximation. The commands come from the project's configured build commands, or from a named validation script via `--script`.
Creating a changeset gives you exactly one version — the project's current original code — which makes it the standard way to check your build commands actually work before starting a run:
```bash
artemis changeset create --project --name "baseline"
artemis changeset validate --project \
--version original --runner my-runner --wait
# Per-command results and the full process log
artemis changeset validation get
artemis changeset validation logs
```
### Shipping
```bash
# Publish to a branch, without opening a PR (auto-named unless --branch is given)
artemis changeset publish --project \
--branch my-fix --commit-message "fix: nil deref"
# Publish and open a pull request — title and description are AI-generated when omitted
artemis changeset pr --project --title "feat: add auth" --base develop
```
`changeset pr` works on any changeset regardless of where it came from, so the whole loop can be driven from the terminal. `task pr` and `maintain issues pr` are convenience wrappers that resolve the changeset for you.
---
## AI Coding
### Tasks
A **task** is a single work item for an AI agent to implement. Tasks move through `todo` → `in_progress` → `done` / `failed` / `cancelled`.
```bash
# Create and auto-start a task, waiting for it to finish
artemis task create --project \
--prompt "Add input validation to user registration" \
--auto-start --wait
# Or create now, start later
artemis task create --project --prompt "Implement rate limiting"
artemis task start --model --wait --timeout 30m
# List, inspect, and follow a task
artemis task list --project --status done
artemis task get
artemis task logs
artemis task stop
# Ship the result as a PR
artemis task pr --title "feat: add input validation"
```
### Plans
A **plan** breaks a large feature into ordered tasks with AI assistance. The agent asks clarifying questions, analyzes your code, and produces an implementation roadmap.
```bash
# Interactive planning (the agent asks questions)
artemis plan create --project \
--prompt "implement user authentication with OAuth2"
# Skip the Q&A for simple, well-defined work
artemis plan create --project \
--prompt "add unit tests for the user service" --skip-interaction
artemis plan list --project
artemis plan get
```
At a terminal the agent's questions are asked inline. Elsewhere — agents, CI, anything that pipes stdin — the command prints what is being asked and stops, and you answer the **same** plan with `plan respond`:
```bash
# See what the plan is waiting on
artemis plan respond
# Answer the first question with its second choice
artemis plan respond --answer 2
# Answer several questions, targeting them by number
artemis plan respond --answer "1=comprehensive" --answer "2=3"
```
:::warning
Don't re-run `plan create` to supply an answer — that starts a *second* plan, whose agent asks its own question, leaving the first one parked forever. `plan create` also accepts `--answer` up front, which implies `--wait`.
:::
### Chats
Chats are AI-powered conversations about your codebase — for understanding, debugging, or architecture questions. Use `chat send` to answer an agent's questions and `chat messages` to follow the conversation; this is the same mechanism that drives interactive rule and plan authoring.
```bash
# Async chat (runs in the background)
artemis chat create --project --message "Explain the authentication flow"
# Real-time streaming
artemis chat create --project --message "Where are the vulnerabilities?" --sync
# Continue an existing chat
artemis chat send --message "Now focus on the login handler"
artemis chat messages
artemis chat cancel
```
**Chat vs Task vs Plan:** *Chat* answers questions (no code changes); *Task* is a single coding work item; *Plan* breaks a feature into multiple tasks.
---
## Maintain
**Maintain** finds, triages, and fixes code-health issues, then ships the fixes. The flow is: author **rules** → **scan** the code against them (which creates issues) → **triage** the issues → **fix** them (with Artemis's agent, or by exporting a prompt for your own) → **publish** a branch or open a **PR** → **sync** the board as the code moves on.
```bash
# 1. Get rules in place — import the default catalogue, or author your own
artemis maintain rules defaults # browse the platform catalogue
artemis maintain rules import-defaults --project
artemis maintain rules create --project \
--prompt "Flag any SQL query built with string concatenation"
artemis maintain rules update --project --name "No raw SQL"
# 2. Scan the code (creates issues on the board; --rule is required, repeatable)
artemis maintain scans run --project --rule --count 10 --wait
artemis maintain scans run --project --rule \
--path src/ --path lib/ --commit
# 3. Triage the findings
artemis maintain issues list --project --severity high --status open
artemis maintain issues confirm # true positive
artemis maintain issues dismiss # false positive (closes it)
artemis maintain issues close # close without ruling on validity
# 4. Fix — with Artemis's agent, or export a prompt for your own agent
artemis maintain issues fix
artemis maintain issues prompt --project | my-agent
# 5. Ship — publish a branch, or open a PR
artemis maintain issues publish --project
artemis maintain issues pr --project --title "fix: sanitize query"
# 6. Keep the board honest as the code changes
artemis maintain syncs run --project --wait
```
Every issue and rule carries a human-friendly display ID (`ISS-143`, `RULE-7`). Those are for readability only — commands take the underlying UUID.
`issues fix` accepts several issue IDs at once: all the fixes land in a single changeset, and the agent's work streams into one chat you can follow with `artemis chat messages `. `issues list` filters on `--severity`, `--status`, `--validity`, `--fix-status`, `--complexity`, `--rule`, and `--path-prefix`, and sorts with `--sort` / `--order`.
### Rule authoring
Rule authoring is agent-driven. By default `rules create` waits for the authoring agent and approves the rule it proposes, so it returns a rule you can scan with straight away. Pass `--auto-approve=false` to get the `[DRAFT]` back immediately with the agent left waiting — a draft cannot be scanned.
A *question* is never auto-answered. At a terminal the CLI asks you; otherwise pass `--answer`, which also wins over the prompt so scripts stay deterministic. Rule editing supports renaming (`--name`) and rewriting the definition from markdown (`--markdown-file`); category, severity, and tags come from the rule definition and aren't editable directly.
### Maintain chat
`artemis maintain chat` holds a conversation with the maintain agent over a project's board. The agent reads both the board and the project's source, so you can hunt for a problem by describing it rather than scanning for it — and have the agent raise the issue once you agree what it is. It can also manage rules and start scans and fixes from the same conversation.
```bash
# Back-and-forth session at a terminal (empty line to end)
artemis maintain chat --project
# One turn, for scripting
artemis maintain chat --project \
-m "is there anywhere we parse the same response twice?" --output-format json
```
Issues raised this way land on the board like any other, and can be fixed with `artemis maintain issues fix`.
---
## Projects and Git Keys
### Supported Git providers
- GitHub (`github`)
- GitLab (`gitlab`)
- Bitbucket (`bitbucket`)
- Azure DevOps (`azure`)
### Managing keys
Artemis needs a Personal Access Token to clone private repos, create branches, and open PRs. Keys are encrypted at rest and referenced by ID.
```bash
artemis key add --name "github-work" --provider github --token ghp_xxxxxxxxxxxx
artemis key add --name "bitbucket" --provider bitbucket --token --email you@example.com
artemis key add --name "azure" --provider azure --token --organization myorg
artemis key list
artemis key delete # does not revoke the underlying token
```
Required token scopes:
| Provider | Token Type | Scopes |
|----------|------------|--------|
| GitHub | PAT / Fine-grained PAT | `repo` |
| GitLab | PAT | `api`, `read_repository`, `write_repository` |
| Bitbucket | App Password | Repositories read/write |
| Azure DevOps | PAT | Code read/write |
### Importing and managing projects
```bash
# Import (auto-sync enabled by default)
artemis project import \
--git-url https://github.com/your-org/repo.git \
--key-id --name "My API Service" --branch develop
# Track a different branch/commit, or pull upstream changes
artemis project branch --branch main
artemis project pull
artemis project compare
# Set build/test/benchmark commands and a default runner
artemis project commands set --project \
--compile "go build ./..." --test "go test ./..." --benchmark "make bench"
artemis project commands get --project
artemis project runner set --project --runner my-runner
# Search, filter, and clean up
artemis project list --search "my-api" --language python
artemis project delete
```
Auto-sync mirrors your repository to Artemis's internal Gitea, which is required for task execution and PR creation. It's on by default at import; if you imported with `--auto-sync=false`, enable it later with `artemis project sync `.
---
## Context
**Contexts** are durable knowledge about how you work, applied to every agent you run. They're personal — they apply only to agents you run.
| Availability | Behaviour |
|--------------|-----------|
| `always_on` | Injected into every agent's system prompt (counts against the upfront token budget) |
| `on_demand` | Agents see the name and description only, and choose when to read the body |
| `disabled` | Stored but not offered to agents |
```bash
# Store an always-on convention
artemis context add --name "code style" --body "We use conventional commits" --always-on
# On-demand reference material from a file, with the description agents see
artemis context add --name "deploy runbook" --description "How we ship" --body-file runbook.md
# From a pipe — e.g. an agent recording what it learned
echo "staging DB resets nightly" | artemis context add --name "staging db" --source agent
# Inspect and manage
artemis context list --availability always_on
artemis context get
artemis context update --availability always_on
artemis context usage # upfront context size against the token budget
artemis context delete
```
New contexts are on-demand unless `--always-on` or `--disabled` is given.
---
## Models and providers
Commands that generate code or reason about it accept `--model`. Each model has **two identifiers**, and different commands want different ones:
- the **model-type code** (e.g. `claude-sonnet-5`) — used by `task create` / `task start`
- the **catalogue ID** (a UUID) — used by `chat create`
`discovery create`, `maintain scans run`, `maintain issues fix`, and `maintain chat` accept either form. `artemis model list` prints both.
```bash
artemis model list # the preset tiers agents can use, with both IDs
artemis model groups --task coding # models organized by task type
```
If no model is specified, Artemis uses the configured default for each task type — except `discovery create`, where `--model` is required.
### Provider connections
`artemis profile` manages the platform's LLM provider connections: the credentials and endpoints through which agents reach Anthropic, OpenAI, Azure, Bedrock, or a local Ollama instance. Each profile holds one provider's credentials; the models it exposes are managed with `artemis model`.
```bash
# What providers can be connected, and what credentials they take
artemis profile providers
# Connect a provider
artemis profile create --name anthropic-prod --provider anthropic --api-key sk-ant-...
artemis profile create --name local-ollama --provider ollama --no-auth --base-url http://localhost:11434
artemis profile create --name bedrock --provider bedrock \
--credentials '{"type":"aws_iam","access_key":"...","secret_key":"...","region":"eu-west-2"}'
# What the provider offers, then register some of it
artemis profile catalog
artemis model add --profile --from-catalog claude-sonnet-5 --from-catalog claude-haiku-4-5
# Register a custom deployment manually
artemis model add --profile \
--model-id my-tuned-model --base-model claude-sonnet-5 --name "Tuned Sonnet"
# Inspect, verify, and clean up
artemis model registry --profile
artemis model validate
artemis profile list
```
`--base-model` takes a model id from the [litellm model catalog](https://models.litellm.ai/model_catalog); it tells the platform which catalog entry a custom-named model should inherit capabilities, token limits, and pricing from.
---
## Background processes and platform logs
Async commands hand back a `processId` instead of blocking. A process's overall status can read `success` while an individual step inside it was a no-op or a failure, so use `status` for the summary and progress-detail breakdown, and `logs` for the full step-by-step trace.
```bash
artemis process status
artemis process logs
```
`artemis logs` browses the logs of the platform's own services — APIs, workers, and infrastructure like postgres or kafka. It requires an admin user; other users get a permission error. It defaults to the last hour, newest first.
```bash
artemis logs services # what can be queried
artemis logs falcon --level error
artemis logs falcon --search "changeset" --since 6h
artemis logs falcon --follow # live tail
```
---
## Interactive TUI
For a richer terminal experience, launch the dashboard:
```bash
artemis tui
```
The TUI (built on Bubble Tea) provides a two-panel view — projects on the left, details on the right — with `↑`/`↓` or `j`/`k` to navigate, `Tab` to switch panels, `r` to refresh, and `q` to quit.
---
## Configuration
The CLI loads configuration from environment variables and a `.env` file. Priority: environment variables > `.env` file > defaults. The file is resolved as `./.env` in the current directory if present (a project-local override), otherwise the selected [environment's](#environments) file under `~/.config/artemis/`.
### Common commands
```bash
# Show current configuration
artemis config
artemis config show
# Set a single value
artemis config set ARTEMIS_API_KEY
# Open the config file in your editor
artemis config edit
```
The recommended way to (re)point the CLI at a deployment is `artemis login` — it writes and validates `ARTEMIS_BASE_URL` and `ARTEMIS_API_KEY` for you.
### Environment variables
**Required**
| Variable | Description |
|----------|-------------|
| `ARTEMIS_BASE_URL` | Deployment base URL. Every service endpoint is derived from it. Accepts a full URL, or `prod` for hosted Artemis. |
| `ARTEMIS_API_KEY` | Your Artemis API key |
A single `ARTEMIS_BASE_URL` is all most users need — the services are path prefixes on one host, so the CLI derives the user-management, Artemis backend, and Falcon endpoints from it. For advanced setups you can still override an individual endpoint by setting its explicit variable (`USER_MGMT_URL`, `ARTEMIS_API_URL`, `FALCON_URL`); an explicit override shadows the derived value.
**Optional preferences**
| Variable | Default | Description |
|----------|---------|-------------|
| `ARTEMIS_ENV` | — | Named environment to use for this invocation (overrides the selected one) |
| `ARTEMIS_DEBUG` | `false` | Enable verbose debug output |
| `ARTEMIS_OUTPUT_FORMAT` | `text` | Output format: `text` or `json` |
| `ARTEMIS_TIMEOUT` | `120s` | Request timeout (e.g. `30s`, `2m`) |
| `ARTEMIS_RETRY_ATTEMPTS` | `3` | Number of retry attempts |
| `ARTEMIS_RETRY_DELAY` | `1s` | Delay between retries |
| `ARTEMIS_MODEL_TYPE` | — | Default model for code generation and analysis |
---
## Getting Help
Every command and subcommand has its own help text with examples:
```bash
artemis --help
artemis maintain --help
artemis discovery create --help
```
For runner setup, see [Artemis Runner](./artemis-runner.md). For genetic-algorithm-based optimization details, see [Artemis Intelligence](./artemis-intelligence.md).
---
## Artemis Intelligence
Artemis Intelligence is the optimization engine of the Artemis platform, developed by TurinTech.
It executes targets with an internal configuration, collects execution logs, and uses the results to generate improved versions in a continuous optimization cycle.
---
## Core Features
* Internal run setup ensures every generated version is evaluated with real execution data, so each new generation learns from the previous one.
* Ability to extract actual values of any metrics that appear in logs, define them as score metrics, and analyze them.
* Metric-driven optimization: specify your focus in a prompt, and Artemis will optimize towards that metric. This can be a built-in score, a custom metric, or one extracted from logs.
## How Internal Run Works
You can enable **internal run** by selecting **Artemis Intelligence** as the method for generating targets and configuring its settings.
1. Go to `Projects` → `Optimisations` → `Targets` and click **+ (Create)**.
2. Choose **Artemis Intelligence**.

When opening the Artemis Intelligence configuration, you can adjust its settings:

Artemis will then use execution logs to guide the generation of subsequent target versions.
## How the Scoring System Works
* When you generate targets using Artemis Intelligence, scores are automatically extracted from logs and displayed for both the original and generated versions.
* If you want to optimize or analyze a specific metric, it's better to include it in your prompt. Artemis will then focus on that metric throughout the optimization cycle.
---
## Artemis Runner(Features)
A runner enables you to validate your code by running builds, tests, and benchmarks on your own machine. The Artemis Runner is a single self-contained binary that you download, configure, and run to connect your hardware to the Artemis platform — letting you run code outside the platform safely and efficiently.
{/* Video hidden pending review — it may demonstrate the older Python-bundle setup flow rather than the current standalone-binary flow. Re-enable once confirmed/re-recorded.
:::tip Video: How to set up a runner
- **[Artemis Runner](https://youtu.be/AbWhnw8jlZw)** — Learn how the Artemis Runner works and how to set it up
:::
*/}
## Accessing Runner Setup
There are two ways to reach the runner setup screen, where you generate the download command and a single-use registration token.

### Method 1: Via Platform Settings
1. Click **Platform Settings** in the header bar
2. Go to the **Runners** section under **Integrations** in the left sidebar
3. Click **"New Artemis runner"** to generate a registration token
### Method 2: Via Project Settings
1. Navigate to your project's **Settings** tab in the top navigation
2. Go to the **Runner and Scripts** section in the left sidebar
3. Click **"Set up a new runner"** under the **Runner** dropdown — this takes you to the **Runners** screen above, where you click **"New Artemis runner"**
## Quickstart
On Linux and Windows the runner ships as a single self-contained binary; on **macOS** it installs from a Python wheels archive (**Python 3.11** + pip). On the **New Artemis runner** screen, choose your **OS** (Linux, Windows, or macOS) and **architecture**; the panel generates the exact download command and a single-use registration **token**. Use a bash shell on macOS/Linux, or PowerShell 5.0+ on Windows. See the [downloads page](../downloads/custom-runner-downloads.md) for direct links and the macOS install steps.

1. **Create a folder and download the runner binary**
**Windows (PowerShell):**
```powershell
New-Item -ItemType Directory artemis-runner; Set-Location artemis-runner
iwr -Uri "https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.2.0-windows.exe" -OutFile "artemis-runner.exe"
```
**Linux (bash):**
```bash
mkdir artemis-runner && cd artemis-runner
curl -L "https://files.artemis.turintech.ai/public/artemis-runner/artemis-runner-5.2.0-linux" -o artemis-runner && chmod +x artemis-runner
```
> Copy the exact command for your platform from the setup panel — it fills in the current version, OS, and architecture for you.
2. **Configure the runner**
Pass the deployment URL and the single-use token from the setup panel. Optionally add `--runner-name` to skip the interactive name prompt.
```powershell
.\artemis-runner.exe configure --url https://artemis.turintech.ai --token --runner-name "my-runner"
```
On Linux/macOS, invoke it as `./artemis-runner configure ...`.
3. **Start the runner**
```powershell
.\artemis-runner.exe start
```
Once it connects, your runner appears in the **Active Runners** list and becomes selectable in the project's **Runner and Scripts** dropdown.
:::note
The registration token is **single-use** and time-limited. If it expires or is already spent, click **Regenerate** on the setup panel (or create a new runner) to get a fresh one.
:::
### Registering with an API key
The token flow above is what the Web UI setup panel generates. A runner can equally register itself on first `start` using your Artemis API key, which avoids the Web UI round-trip entirely and is usually the better fit for scripted or agent-driven setup:
```bash
set -a; . ~/.config/artemis/.env; set +a # exports ARTEMIS_API_KEY
./artemis-runner start \
--runner-name "my-runner" \
--url https://artemis.turintech.ai \
--no-delete-task-output
```
## Upgrading the runner
To update an existing runner to the latest release, run:
```bash
artemis-runner upgrade
```
## How the Runner Works

The runner operates through a secure REST API communication:
1. **Command triggered** — User runs a validation command on the Artemis web platform
2. **Runner receives command** — Your local runner picks up the command from the channel
3. **Repository copied locally** — Runner clones your repository to a temporary folder (see [Task output: where your code is downloaded and run](#task-output-where-your-code-is-downloaded-and-run) to learn where, and how to change it)
4. **Command executed** — Runner executes the command on the local copy
5. **Logs sent back** — Real-time logs stream back to the Artemis server
## Configuration Options
Running `configure` saves your settings to a `settings.env` file next to the binary. When you `start` the runner, values are resolved in this order: **CLI flags > environment variables > `settings.env` > defaults**, so you can override any saved setting on the command line without re-running `configure`.
### On-premise deployments
For on-premise Artemis, pass your deployment's base URL with `--url` when configuring. All service connection variables are derived automatically from that URL — no separate microservice configuration is required.
```bash
./artemis-runner configure --url https://artemis.internal.company.com --token
```
### SSL Configuration
Configure SSL certificate verification with the `--ssl-verify` flag or the `ARTEMIS_SSL_VERIFY` environment variable:
```bash
export ARTEMIS_SSL_VERIFY=true # Use system CA certificates (default)
export ARTEMIS_SSL_VERIFY=false # Disable SSL verification
export ARTEMIS_SSL_VERIFY=/path/to/ca/certificates.pem # Custom CA certificates
```
## Usage Tips
- Ensure your runner has adequate disk space for project dependencies
- Keep the `start` process running — the runner is only online while it is running
- Use meaningful runner names to identify them in the platform
- Monitor runner logs to troubleshoot any connection issues
# Advanced Usage
This section covers advanced usage scenarios for the Artemis runner, including running multiple runners, resource management, proxy configuration, and where your code is downloaded and run.
## Running multiple runners
You can run more than one runner at the same time. Runners that share a name form a **pool**: when a task comes in, Artemis sends it to any available runner in that pool. You have no control over which one is picked, so every runner in a pool should be interchangeable — same code, same environment, same toolchain.
To scale out, just start several runners with the same name. Tasks are distributed across whichever ones are free.
To create a **separate** pool, start a runner under a different name. Only one runner name is stored in the settings file, so pass `--runner-name` to override it:
```bash
./artemis-runner start --runner-name "my-runner-name"
```
Runners with different names appear as separate options on the platform and never share tasks.
## Resource Management
### Limiting RAM Usage
You can control the amount of RAM available to your evaluations using the `--ram-limit-mb` flag or the `ARTEMIS_RAM_LIMIT_MB` environment variable. This is particularly useful on systems with limited resources or when you need consistent resource usage across environments.
```bash
# Set RAM limit to 4GB (4096MB) via flag
./artemis-runner start --ram-limit-mb 4096
# Or via environment variable
export ARTEMIS_RAM_LIMIT_MB=4096
./artemis-runner start
```
:::note
The RAM limit is specified in megabytes (MB). For example:
- 1GB = 1024MB
- 2GB = 2048MB
- 4GB = 4096MB
- 8GB = 8192MB
:::
:::warning
Setting the RAM limit too low may cause evaluations to fail if they require more memory than allocated. Monitor your evaluations' memory usage to determine appropriate limits.
:::
## Proxy Configuration
If you're experiencing connection issues in a corporate environment with a proxy, configure `no_proxy` to allow direct connections to your Artemis deployment.
### Environment Variables
- **`no_proxy`/`NO_PROXY`**: Comma-separated list of hosts to bypass the proxy
### Troubleshooting Connection Issues
#### For SaaS Artemis (artemis.turintech.ai)
```sh
export no_proxy=localhost,127.0.0.1,artemis.turintech.ai
./artemis-runner start
```
Direct connections to Artemis can be faster and more reliable than going through a corporate proxy.
#### For On-premise Artemis
```sh
# For domain-based deployment
export no_proxy=localhost,127.0.0.1,artemis.internal.company.com
# For IP-based deployment
export no_proxy=localhost,127.0.0.1,192.168.41.1
./artemis-runner start
```
### Testing Connectivity
Before starting the runner, verify connectivity:
```sh
# Test direct connection (with no_proxy)
curl -v https://artemis.turintech.ai
# Test internal deployment
curl -v https://artemis.internal.company.com
```
### Diagnosing proxy issues
1. **Verify `no_proxy` is set correctly**
```sh
echo $no_proxy
```
2. **Check if the proxy is blocking Artemis** — SSL certificate errors may indicate proxy SSL inspection; connection timeouts may indicate proxy blocking
## Task output: where your code is downloaded and run
When a task runs, the runner clones each candidate version of your code into a subfolder of its **worker output root** — your system's cache directory by default — executes your build, test, and benchmark commands there, and streams the results back to the Artemis platform. At command entry, `$PWD` is that candidate checkout (`output/build`); write `artemis_results.json` or `artemis_results.csv` there.
The exact path is printed in the runner output at the start of each run. If you ever need to locate files or debug a failure, check there first — see [What's inside a task folder](#whats-inside-a-task-folder) for the layout.
Two advanced options control this behaviour: **Worker Output Root** (where the files go) and **Delete Task Output** (whether files are kept after a run). To change either:
1. Run `./artemis-runner configure`
2. Choose **Edit Advanced Options**
3. Select the option you want to change
### Changing where tasks run (Worker Output Root)
By default, the runner works inside your system's cache directory. If you'd rather have tasks run somewhere else — a larger disk, a faster drive, or simply a folder that's easier to find — set a custom location:
1. Run `./artemis-runner configure`
2. Choose **Edit Advanced Options**
3. Select **Worker Output Root** and enter the directory you want the runner to use
All subsequent tasks will be downloaded and executed under that directory.
### Keeping files after a run (Delete Task Output)
By default, the runner deletes a task's folder as soon as the task completes, so old runs don't fill up your disk. If you want to keep the files for inspection — for example, to look at build artefacts or dig into a failing test — turn this off:
1. Run `./artemis-runner configure`
2. Choose **Edit Advanced Options**
3. Select **Delete Task Output** and answer **No**
:::warning Watch your disk space
With **Delete Task Output** set to **No**, every run leaves its files behind, including a full copy of your repository per task. Clear out old task folders from the worker output root periodically.
:::
### Keeping built versions (Delete Mutated)
This setting applies to [Code Optimization](#code-optimization) runs. **Delete Mutated** controls whether built versions are archived once they finish: with it set to **Yes**, a version's `build/` folder is copied into the `mutated/` folder; with **No**, the `build/` folder is simply deleted. To change it:
1. Run `./artemis-runner configure`
2. Choose **Edit Advanced Options**
3. Select **Delete Mutated** and answer **No**
:::note
**Delete Task Output** and **Delete Mutated** are independent: the first decides whether the whole task folder survives, the second decides whether built versions are kept inside it.
:::
### Reusing build artefacts (Incremental Build)
This setting applies to batch validations. When **Incremental Build** is set to **Yes**, build artefacts from an earlier validation in the same batch run are reused by later validations, which can speed the run up; with **No**, each validation builds from scratch. [Code Optimization](#code-optimization) always builds incrementally, regardless of this setting. To change it:
1. Run `./artemis-runner configure`
2. Choose **Edit Advanced Options**
3. Select **Incremental Build** and answer **Yes**
### What's inside a task folder
Each task gets its own folder, named `task-{task_id}`, inside the worker output root. The layout inside depends on which Artemis feature triggered the task. There are three main variations:
#### [Code validation](../optimization/code-validation/code-validation-overview.md)
Used for most activity on the Optimise page (other than Code Optimization): single and batch code validation, Artemis Intelligence, Spec Coder, and testing your commands from the Settings page.
```
task-{task_id}/
├── input/
│ └── {project_id}/ # your code, as downloaded
└── output/
├── original_repo/ # pristine working copy
├── build/ # validated version — kept after the run (the last one, for batch validation)
└── build_dir_backup/ # baseline with build artefacts (only when incremental builds are enabled)
```
#### [Code Optimization](../optimization/code-optimization/overview.md)
Used for multi-target Code Optimization runs.
```
task-{task_id}/
├── input/
│ └── {project_id}/ # your code, as downloaded
└── output/
├── original_repo/ # pristine working copy (baseline)
├── build/ # version currently being built (not kept — see note below)
├── mutated/ # archived built versions — inspect these after a run
│ ├── 0/ # baseline (trial 0)
│ └── {version_number}/ # one folder per candidate version
└── build_dir_backup/ # baseline with build artefacts (only when incremental builds are enabled)
```
When you evaluate a single version from Code Optimization, the layout is the same except archived versions are stored under `mutated/{test_id}/`.
#### [Changesets](./changeset.md) and [Discover](../optimization/discover/overview.md)
Used for changeset evaluation. Discover uses changesets under the hood, so its tasks look the same.
```
task-{task_id}/
├── input/
│ └── {project_id}/ # current state of changeset, as downloaded
└── output/
└── build/ # build environment (copy of changeset code, kept after the run)
```
:::note What happens to the build/ folder
The `build/` folder is where commands are actually executed against a candidate version. What happens to it when a run finishes depends on the feature:
- **Code validation** and **Changesets / Discover**: the `build/` folder is preserved. For batch validation it holds the contents of the *last* version validated.
- **Code Optimization**: the `build/` folder is ephemeral. Whether a built version is kept is governed by [Delete Mutated](#keeping-built-versions-delete-mutated) — use the `mutated/` folders to inspect built versions after a run.
:::
## Next Steps
Once your runner is configured and running, you can:
- Set up build commands in [Project Settings](/project-setup/settings/runner-and-scripts)
## Troubleshooting
If you encounter connection issues:
1. Verify your saved settings in `settings.env` (re-run `configure` if needed)
2. Check your internet connection
3. Confirm the runner name is unique on your account
4. Make sure your registration token hasn't expired — regenerate it if it has
5. Review SSL certificate configuration if using HTTPS
---
## Changesets
Review, publish, and open pull requests for your changesets — code changes that live entirely in Artemis. Your git remote stays untouched until you publish a branch or open a pull request.

A changeset is created whenever you keep a result — for example, **Create PR** on a [Discover version](../optimization/discover/versions.md), or a version you've assembled from Optimise targets. Filter the list by **All**, **Unpublished**, **Published**, or **PR**, and search by name.
---
## Creating a pull request
Open a changeset and choose **Create PR** to open the pull-request form. Fill in the **branch name**, the branch you're **merging into**, a **title**, and a **description** — or click **Generate with AI** to have the agent write the title and description from the diff. The changed files are shown below so you can review them before opening the PR.

When you're happy with it, click **Create PR**.
---
## Reviewing the changes
After the PR is created, the **File changes** tab shows the full diff for each changed file (here `cli/xxhsum.c`, `tests/cli-seed.sh`, and the `Makefile`). Use **Open in GitHub** to view the pull request on your git provider, or the download icon to grab the diff.

Switch to the **Validations** tab to run the changeset's build, test, and benchmark checks before you merge.
---
## Validating a changeset
On the **Validations** tab, choose a **runner** and the **commands** to run — these default to your project's build, test, and benchmark scripts. If no runner is connected, [set one up](../project-setup/settings/runner-and-scripts.md) first. Add or remove commands as needed, then click **Run validation**.

Each command runs on the selected runner and reports **Passed** / **Failed**, with full **logs** you can expand — including any [custom metrics](../project-setup/settings/benchmarks.md) your benchmark writes to `artemis_results.json`.

Every validation run is kept — the **left panel** lists the **history** of past runs (status, timestamp, commit, and each command's result), so you can revisit earlier validations or start a fresh one with **Run new validation**.

---
## Opening the pull request in GitHub
Once a changeset is published as a PR, it appears under the **PR** filter with a **PR** badge. Click **Open in GitHub** to jump straight to the pull request on your git provider.

---
## Index your codebase
Code indexing in Artemis allows you to create a comprehensive understanding of your codebase beyond just the specific files you've targeted for optimization. This broader context helps Artemis provide more intelligent and contextual suggestions when using Code Search or chatting with the agent.
### Why Index Your Code?
When you index your code, Artemis:
- Creates embeddings of your entire codebase
- Understands relationships between different parts of your code
- Provides more accurate and contextual responses in Code Search
- Offers more intelligent suggestions during agent chat interactions
### How to Index Your Code
- Access your project
- Click on `Optimise`, `Targets`
- Click on index you code

The indexing process will run in the background, and you'll be notified when it's complete.
### Using Indexed Code
Once your code is indexed, you can:
- Extract additional files related to one target, such as unit tests, implementation of an interface or similar code (e.g. find duplication)
- Use the "Code Search" option when generating new target versions, this is more powerful than simple Ask LLM, and will use the full index as context.
- Chat with the agent about your code with improved context
### Best Practices
- Index your code after making significant changes to ensure the embeddings are up to date
- Consider indexing before starting a new optimization task to get the most context-aware suggestions
- Use indexing in conjunction with code extraction to get the most value from Artemis's features
---
## Custom Metrics
Track domain-specific measurements — throughput, accuracy, error rates, or anything your benchmark produces. Artemis already records runtime, CPU, and memory automatically; custom metrics let you measure what matters to **your** project, then compare those values across versions of your code.
## How Artemis reads your metrics
Your benchmark writes a results file; Artemis picks it up after every run — no extra configuration.
1. **Write a results file** — have your benchmark script write an `artemis_results.json` or `artemis_results.csv` to the project root before it exits.
2. **Run a benchmark** — run a benchmark from the project's execution settings, or let an optimisation run it. Each run produces one results file.
3. **Artemis picks it up** — after the run, Artemis reads the file from the project root and stores every value. If both a `.json` and a `.csv` exist, **JSON takes priority**.
4. **Compare across versions** — recorded values show up in the project's metrics table and feed the distribution and trend charts, so you can see how each version moves the numbers.
## File format
Use any metric names you want. Each object (JSON) or row (CSV) is one measurement — run your benchmark multiple times to build a distribution.
```json title="artemis_results.json"
[
{ "throughput": 4500, "error_rate": 0.02 },
{ "throughput": 4620, "error_rate": 0.01 },
{ "throughput": 4480, "error_rate": 0.03 }
]
```
```text title="artemis_results.csv"
throughput,error_rate
4500,0.02
4620,0.01
4480,0.03
```
:::info Numbers only
Every value must be a finite number. Keep metric names consistent across measurements so they line up into one series.
:::
The rules Artemis enforces:
- The file must be named exactly `artemis_results.json` or `artemis_results.csv` and live in the working directory (project root), not a subfolder.
- Every metric value must be a finite number (integer or float). No strings, booleans, null, or nested objects.
- Use clear, consistent metric names across runs (e.g. `throughput`, `accuracy`, `error_rate`, `inference_ms`).
- One run → a single JSON object: `{"throughput": 4500, "error_rate": 0.02}`.
- Multiple measurements → a JSON array of objects, or a CSV with a header row and one numeric row per measurement.
- If both a `.json` and a `.csv` exist, Artemis uses the JSON.
## Set it up with your coding agent
Custom metrics need a small change to your benchmark code. Paste this prompt into your own coding agent (Claude Code, Cursor, Copilot…) inside your repo — it reads your benchmark and adds the `artemis_results` output for you.
```markdown
I'm setting up **custom metrics** for TurinTech Artemis.
Artemis runs my benchmark on a runner and, after each run, reads a results file from the project root to track performance metrics across versions of my code.
Please update my benchmark so that, right before it exits, it writes the key metrics it measures to an `artemis_results.json` (or `artemis_results.csv`) file in the project root.
Rules Artemis enforces:
- The file must be named exactly `artemis_results.json` or `artemis_results.csv` and live in the working directory (project root), not a subfolder.
- Every metric value must be a finite number (integer or float). No strings, booleans, null, or nested objects.
- Use clear, consistent metric names across runs (e.g. throughput, accuracy, error_rate, inference_ms).
- One run -> a single JSON object: {"throughput": 4500, "error_rate": 0.02}
- Multiple measurements -> a JSON array of objects, or a CSV with a header row and one numeric row per measurement.
- If both a .json and a .csv exist, Artemis uses the JSON.
Steps:
1. Read my benchmark code and list the numeric metrics it already computes.
2. Pick the ones worth tracking and add code to write them to artemis_results.json before the benchmark exits.
3. If the benchmark runs in a separate directory, copy the results file back to the project root before exiting.
4. Run the benchmark locally and confirm the file appears in the project root with numeric values.
5. Show me the diff.
```
:::tip Prefer a guided, end-to-end setup?
Install the `repo-setup` Artemis skill and run it in your terminal — it walks through build, test, and benchmark configuration, including custom metrics. See [Artemis Skills](/features/artemis-agent-skills).
:::
## Running in a separate directory
If your benchmark runs somewhere other than the project root — a clone, a build dir, a container mount — copy the results file back before the script exits.
```bash
# Run your benchmark wherever it lives, then copy the
# results file back to the project root before exiting.
ORIG=$(pwd)
cd /path/to/clone
./run_bench.sh
cp artemis_results.json "$ORIG/"
```
Artemis only looks at the **project root** after a run, so the file has to land there. Capturing `$(pwd)` first is the simplest way to copy it back from wherever your benchmark ran.
## What you get
Once values are recorded, each metric gets a distribution (box plot) and a trend over time (line chart) — the same charts you'll see in the project's metrics table.
The box plot shows the spread — minimum, quartiles, and median — so you can spot noise and outliers at a glance. The line chart shows each measurement in order, so a drift or regression across runs is easy to see.
---
## MCP Servers
Configure Model Context Protocol (MCP) servers for your account. Configured servers are available across all agent runs on the Artemis platform — chat, planning, coding, and target generation.

## Supported transports
Only HTTP-based transports are supported. SSE and Streamable HTTP endpoints are both accepted. Local command execution (stdio) is not available.
## Configuration format
Define your servers under the `mcpServers` key. Each entry requires a `url` pointing to the endpoint. You can optionally include `headers` for authentication.
```json
{
"mcpServers": {
"my-server": {
"url": "https://mcp.example.com/sse",
"headers": {
"Authorization": "Bearer "
}
}
}
}
```
## Adding servers
Open [Platform Settings](/settings/user-settings) and select **MCP Servers** under Integrations. Add, edit, or remove server entries in the JSON editor. Your configuration is encrypted at rest.
---
## Agents Memory
Agents Memory keeps a record of every experiment Artemis has run across all your projects. You can ask it questions — what has worked, what hasn't, and what ideas from one project might apply to another — without having to dig through past results yourself.
## How it works
Every experiment Artemis runs is automatically saved as a memory. Over time this builds up a knowledge base that spans all your projects, so insights are never lost between runs.
You can query this knowledge base in two ways:
- **General memory chat** — ask questions across all your projects at once.
- **Experiment-level chat** — open a specific experiment and ask questions scoped to that memory, with the full conversation history preserved per experiment.
## Accessing Agents Memory
Click your **avatar** (or initials) in the top-right corner, then select **Agents Memory** from the dropdown.

The page opens with three areas:
- **Left panel (MEMORIES)** — lists all your stored experiments, searchable by keyword. Shows the total count and the project each experiment belongs to.
- **Centre panel** — displays the selected experiment's detail, or a welcome prompt when nothing is selected.
- **Right panel** — shows your chat history and quick-start prompts.
Click **+ New chat** at the top of the left panel to start a fresh general chat across all your memories.

## The experiment detail view
Clicking an experiment in the left panel opens its detail in the centre:
- **Project path** — shows the project and optimisation the experiment belongs to, with an **Open in Discovery** link to jump directly to it.
- **Status badge** — current state (e.g. Queued, Validated, Refuted, Inconclusive).
- **Confidence** — the confidence score for this experiment's outcome.
- **Created** — the date the experiment was created.
- **Hypothesis** — the full hypothesis text describing what was changed and why.
The right panel updates to show **CHATS ABOUT THIS MEMORY** — the conversation history scoped to this experiment.

## Asking questions
### General prompts
From the main Agents Memory view (no experiment selected), the right panel shows three quick-start buttons and a chat input. These cover the most common questions across all your projects:
- **What reliably works** — "Looking across all my projects, which optimisation approaches have reliably improved performance, and which keep failing?"
- **Don't repeat** — "What have I already tried and refuted, so I don't waste time repeating it?"
- **Transferable wins** — "Which validated experiments could likely transfer to my other projects, and why?"
You can also type any question into the **Ask about your memories…** input — the agent has access to all your experiments.
### Experiment-level prompts
When you open a specific experiment, the right panel switches to **CHATS ABOUT THIS MEMORY** with its own quick-start prompts:
- **Summarise** — "Summarise this experiment: the hypothesis, what the versions actually changed, and why it was concluded this way."
- **The winning change** — "What did the best version change, and how did it move the metrics versus the baseline?"
- **Try next** — "Given how this turned out, what follow-up experiments would be worth running — here or on similar code?"
The chat input scopes automatically to the open experiment. You're not limited to these prompts — ask anything about the experiment.
## Chat history
Every conversation you have in Agents Memory is saved. General chats appear in the **MEMORY CHATS** panel on the right of the main view. Experiment-level chats are saved under **CHATS ABOUT THIS MEMORY** and reappear whenever you open that experiment, so context is never lost between sessions.
---
## Settings
Configure your project's execution environment and project-level details from the **Settings** tab inside any project.
The Settings page has two sections accessible from the left sidebar: **Execution** and **Project**.
---
## Execution
The Execution section lets you configure the runner and the commands Artemis uses to compile, test, and benchmark your code.

### Set up a runner
Before configuring commands, [set up the Artemis Runner](/features/artemis-runner) if you haven't already.
Select a runner from the **Runner Name** dropdown. The selected runner will pick up all execution tasks for this project.
### Command Configuration
Configure the command for each execution stage:
- **Compilation** — compiles the code. Ensures the code is free from syntax errors and is ready for execution.
- **Unit Tests** — runs unit tests on the compiled code. Verifies that individual components function as expected.
- **Benchmark** — runs your performance benchmark to measure runtime, CPU, and memory.
Each command can be edited, duplicated, run manually, or deleted using the action icons on the right.
### Agent Assistant
The right-hand panel in the Execution settings contains a built-in chat agent that can help you configure and troubleshoot your commands. The agent is hardware-aware — it knows the specifications of your connected runner (CPU, memory, platform) — and has full context of the commands you've already set up.
You can ask it to:
- Set up build commands for your project from scratch
- Review and fix issues in your existing compilation, test, or benchmark commands
- Suggest improvements based on your runner's hardware
- Troubleshoot failures in any of the execution stages
### Custom Metrics
Track metrics beyond the built-in runtime, CPU, and memory. Have your benchmark script write an `artemis_results.json` or `.csv` file to the **project root** before exiting — Artemis will automatically pick up and display any values in that file as additional score metrics.
:::tip
See the **File format & examples** section in the Custom Metrics panel for the expected JSON/CSV schema.
:::
---
## Project
The Project section contains project-level configuration for your repository connection and settings.

### Fields
- **Name** — the display name of your project.
- **Description** — an optional description.
- **Owner** — the owner of the project.
- **Git Repository** — the URL of the connected Git repository.
- **Git Branch** — the branch Artemis will use.
- **Git Commit** — optionally pin to a specific commit hash.
- **Code Authors** — the authors associated with this project.
- **Git Key** — the authentication key used to access the repository. See [Using private code repositories](/project-setup/git-keys) for setup instructions.
- **Auto Pull Request** — when enabled, Artemis will automatically open a pull request for accepted code changes.
---
## Next Steps
After configuring your settings:
[Validate your new code versions using these commands](optimization/code-validation/code-validation-overview.md)
---
## Quick Overview
Artemis is built around four modules — Build, Maintain, Discover, and Optimise — that share a single connection to your codebase. Every module reads and writes the same source of truth.

---
## Getting started
### Log in to Artemis
Access Artemis via the web platform or your local deployment. After logging in you'll land on the **Projects** page.
*New user?* [Create your account here](./signup-login.md)
### Create a project
From the Projects page, click **+ Import Project** to connect a Git repository, upload a zip archive, or import a sample project. Or click **Plan with AI** to describe what you want to build and let the Planning Agent create a project and structured plan for you.
For detailed instructions, see [Import your codebase](../project-setup/import-codebase.md).
---
## Build
The Build module helps you generate and ship code through three modes:
- **Plan** — a Planning Agent breaks your goal into sub-tasks and implementation steps
- **Standalone** — direct code generation tasks that apply changes automatically or via Git
- **Chat** — conversational agent assistance for coding decisions, debugging, and exploration
[Learn more about Build →](../build/overview.md)
---
## Maintain
Maintain gives you a structured workflow for keeping your codebase clean and standards-compliant.

- **Rules** — define quality, security, and style standards. Create rules with agent assistance, import from another project, or start from Artemis's built-in library.
- **Scan** — run rules against your codebase. Select up to 20 rules per scan, set an issue budget, and watch live scan logs.
- **Triage** — review findings filtered by severity. Mention `#Issues` and `#Rules` directly in chat.
- **Fix** — send any issue straight to an AI coding agent. Complex issues can be escalated to Discover or a Build plan automatically.
[Learn more about Maintain →](../scan/overview.md)
---
## Discover
Discover is the experimentation engine — explore objectives, generate ideas, and run experiments that produce validated code variants.

- **Objective** — define what you want to improve
- **Ideas** — the agent proposes candidate approaches
- **Experiments** — each idea becomes an experiment that moves through Draft → Queued → In Progress → Concluded
- **Versions** — each experiment produces measured code variants, scored against your metrics
- **Goals / Score** — validate variants against your performance targets, then iterate
[Learn more about Discover →](../optimization/discover/overview.md)
---
## Optimise
The Optimise module connects code targeting, version generation, and validation into a single pipeline:
- **[Code targeting](../optimization/code-targeting/overview.md)** — identify areas to improve using agents, file-by-file scanning, or tool integrations
- **[Version generation](../optimization/version-generation/overview.md)** — generate alternatives using LLMs, agents, or Artemis Intelligence
- **[Validation](../optimization/code-validation/code-validation-overview.md)** — verify improvements against real runtime, memory, and CPU metrics on your runner
- **[Changesets](../features/changeset.md)** — package your best versions and open a pull request directly from Artemis
[Learn more about Optimise →](../optimization/overview.md)
---
## Agents
All modules are powered by Artemis agents. In v3.0.0, agents are faster, more resilient, and easier to manage.

- **Multi-tab chat** — run multiple agent conversations in parallel without losing context
- **Global checkpoint resume** — if an agent fails mid-run, it picks up from the last saved state automatically
- **Streaming output** — responses stream directly from the LLM for noticeably faster results
- **Agents Memory** — browse and query past Discovery experiments across all your projects
[Learn more about Agents Memory →](../features/memories.md)
---
## Next steps
- [Import your codebase](../project-setup/import-codebase.md)
- [Set up a runner](../features/artemis-runner.md)
- [Read the v3.0.0 release notes](../release-notes/v-3.0.0.md)
---
## Account Setup & Authentication
Create your Artemis account or log in to your existing account to start optimizing your code. This guide covers the complete account setup process, including authentication options and initial configuration.
## Creating Your Account
### Step 1: Access the Sign Up Page
Navigate to the Artemis platform and click the **Sign Up** button.
### Step 2: Complete Registration
Fill in the registration form with your details:

Click **Create Account** to complete registration.
### Step 3: Account Verification
After registration, you'll receive a verification email. Click the verification link to activate your account.
:::info Account Approval Process
All new accounts require approval from a TurinTech administrator before you can access the platform.
After email verification:
1. Your account request will be reviewed by the TurinTech team
2. You'll receive an email notification once your account is approved
3. You can then log in and start using Artemis
**Approval typically takes 1-2 business days.** If you experience delays, contact TurinTech support at support@turintech.ai
:::
## Logging In
### Standard Login
If you already have an Artemis account, use the login form:

:::tip Git Setup Recommendation
We recommend setting up Git access immediately after account creation. This allows you to import private repositories and enables advanced features like automated analysis triggers.
**Next Step**: Follow our comprehensive [Git Keys Setup Guide](project-setup/git-keys.md)
:::
## Troubleshooting Account Issues
### Common Login Problems
**Forgot Password**
1. Click "Forgot Password" on the login page
2. Enter your email address
3. Check your email for reset instructions
4. Create a new strong password
**Account Locked**
Contact your administrator or support@turintech.ai
**Email Verification Issues**
1. Check spam/junk folder
2. Request new verification email
3. Contact support if not received within 10 minutes
---
**Next Steps**:
- [Complete your first code analysis](./quick-overview.md)
- [Set up Git repository access](project-setup/git-keys.md)
- [Explore advanced features](build/overview.md)
---
## Artemis Documentation
Artemis is an AI-powered code intelligence platform that helps engineering teams build, maintain, discover, and optimise their codebases — through intelligent agents, real execution metrics, and a unified multi-module workflow.
---
## The four modules
### [Build](./build/overview.md)
Plan tasks, generate code, and run agentic development workflows from natural language. Includes Plan mode for structured strategies, Standalone tasks for direct code changes, and Chat for conversational assistance.
### [Maintain](./scan/overview.md)
Define quality rules, scan your codebase for violations, triage findings by severity, and fix them directly with an AI coding agent. Rules can be created, imported, or seeded from Artemis's built-in library.
### [Discover](./optimization/discover/overview.md)
Explore objectives, generate ideas and experiments, and track code variants through their full lifecycle — from draft to validated. A rebuilt ground-up experience in v3.0.0 with multi-LLM review, multi-metric plots, and a unified experiment board.
### [Optimise](./optimization/overview.md)
Target specific code, generate improved versions, validate against real execution metrics, and ship regression-safe changes. Connects directly to Discover experiments and produces changesets you can open as pull requests.
---
## Agents
Artemis agents power all four modules. In v3.0.0 they got significantly faster and more resilient:
- **Streaming from the LLM** — noticeably faster output for long responses
- **Global checkpoint resume** — if an agent fails mid-run, it recovers from the last good state
- **Multi-tab chat** — run multiple agent conversations in parallel tabs
- **Agents Memory** — browse past Discovery experiments across all projects and ask questions about them
---
## Get started
- [Quick Overview](./getting-started/quick-overview.md) — the full Artemis workflow in one page
- [Sign up / Log in](./getting-started/signup-login.md) — create your account
- [Import your codebase](./project-setup/import-codebase.md) — connect a repository or start from scratch
- [Git Keys](./project-setup/git-keys.md) — authenticate with your git provider
---
## Platform & settings
- [Platform Settings](./settings/user-settings.md) — agent limits, contexts, model management, MCP servers
- [Admin Settings](./settings/admin-settings.md) — per-user governance, usage tracking, feature flags
- [Artemis Runner](./features/artemis-runner.md) — run builds and benchmarks on your own hardware
- [Artemis CLI](./features/artemis-cli.md) — manage projects and tasks from the terminal
- [MCP Servers](./features/mcp-servers.md) — connect external data sources to your agents
- [Agents Memory](./features/memories.md) — search and query past experiments across all projects
---
## Deployment & architecture
- [Deployment Options](./deployment/deployment-options.md) — SaaS or on-premise
- [Architecture Overview](./architecture/architecture-diagram.md) — how Artemis works under the hood
- [Release Notes](./release-notes/v-3.0.0.md) — what's new in v3.0.0
---
## Need help?
- [FAQs](./FAQs.md)
- Email: support@turintech.ai
---
## Artemis Standard T&Cs
## For web-based users
These Standard Terms (SaaS) are made between Turing Intelligence Technology Limited (Company No. 10318035) whose registered office is at Unit 2G, 2nd Floor, 1 Finsbury Avenue EC2M 2PF (“we” “us” “our”) and the customer who orders our services (“you”).
### Background
(A) We have developed a hosted service providing you with access to our Artemis code optimisation tools made available on a subscription basis via the internet.
(B) You wish to use our service in your business operations.
(C) We have agreed to provide and you have agreed to take and pay for our service subject to these terms and conditions.
### Agreed terms
1. Agreement
1.1 Your use of the Service is governed by these Standard Terms and Conditions.
1.2 When we use the term “this Agreement” in any of these Standard Terms and Conditions or an Order, we are referring to both of them.
1.3 Your use of the Service includes the ability to enter into further transactions with us, use additional services and make purchases electronically. You acknowledge that your signature or electronic assent to an Order constitutes your acceptance that the terms of this Agreement and apply to each further transaction, use of additional services and electronic purchase.
1.4 In our sole discretion we may accept or reject any Order that you submit. Only an executed Order, or the commencement of the Service, shall constitute our acceptance of an Order.
2. Defined Terms
2.1 The definitions and rules of interpretation in this clause apply in this Agreement.
**Additional Fees**: means fees relating to Subscription Fees for additional User Licences or additional services that we have agreed to provide under this Agreement as specified in a signed Order or agreed in writing by the parties.
**Authorised Users**: those employees, agents and independent contractors of you who are authorised by you to use the Service and Documentation as described in clause 3.2.
**Business Day**: a day other than a Saturday, Sunday or public holiday in England when banks in London are open for business.
**Confidential Information**: information consisting of technical or commercial know-how, specifications, inventions, processes or initiatives or relating to a party's business, customers, products or services and which in either case is proprietary or confidential in nature and information which is particularly identified as "Confidential Information" by the parties.
**Data Protection Policy**: our data protection policy as put in place and amended from time to time in accordance with clause 19 (Variation).
**Data Protection Legislation**: the UK Data Protection Legislation and (for so long as and to the extent that the law of the European Union has legal effect in the UK) the General Data Protection Regulation ((EU) 2016/679) and any other directly applicable European Union regulation relating to privacy.
**Documentation**: the documents, user instructions and materials relating to use of the Service made available to you by us by any means.
Initial Subscription Term: the initial term of this Agreement as set out in an Order.
**Large Language Models**: A model that is capable of intaking, processing, and generating text and content in other modalities.
**License**: means the license granted in relation to your use of the Platform described in clause 3.1.
**Normal Business Hours**: 8.00 am to 6.00 pm local UK time, each Business Day.
**Open-Source Software**: any software licensed under any form of open-source licence meeting the Open Source Initiative's Open Source Definition (http://www.opensource.org/docs/definition.php) or any libraries or code licensed from time to time under the General Public Licence (as described by the Free Software Foundation and set out at http://www.gnu.org/licenses/gpl.html), or anything similar, included or used in the provision of the Service.
Order means (i) the order form (either in electronic or paper form) provided to you by us for signature that describes the type or types of services you are purchasing, and that is signed by you, either manually or electronically, and (ii) any other online order that you submit or accept for the Service, (iii) your use or acceptance of the Service.
**Output**: means new, amended or optimised code or coding suggestions or recommendations generated by using our Platform and including code generated by Large Language Models accessed using our Platform.
**Platform**: means our website (currently as updated or replaced from time to time) and all of our proprietary or licensed software programs, control panels and tools accessed using our website or that form part of our Service.
**Personal Data**: has the meaning given in clause 12.2.
**Renewal Period**: the period described in clause 16.1.
**Service**: our subscription service for optimising software delivered online via our Platform, as more particularly described in the Order and Documentation.
**Subscription Fees**: the subscription fees payable by you to us for the User Licences, as set out in an Order.
**Subscription Term**: has the meaning given in clause 16.1 (being the Initial Subscription Term together with any subsequent Renewal Periods).
**UK Data Protection Legislation**: any data protection legislation from time to time in force in the UK including the Data Protection Act 2018 or any successor legislation.
**User Licences**: the user licences purchased by you pursuant to clause 13.1 which entitle Authorised Users to access and use the Service and the Documentation in accordance with this Agreement.
**Virus**: any thing or device (including any software, code, file or programme) which may: prevent, impair or otherwise adversely affect the operation of any computer software, hardware or network, any telecommunications service, equipment or network or any other service or device; prevent, impair or otherwise adversely affect access to or the operation of any programme or data, including the reliability of any programme or data (whether by re-arranging, altering or erasing the programme or data in whole or part or otherwise); or adversely affect the user experience, including worms, trojan horses, viruses and other similar things or devices.
**Your Data**: data inputted onto the Platform by you or Authorised Users.
**Your Software**: software programs uploaded by you or Authorised Users for optimisation using the Platform.
2.2 Clause, schedule and paragraph headings shall not affect the interpretation of this Agreement.
2.3 A person includes an individual, corporate or unincorporated body (whether or not having separate legal personality).
2.4 Unless the context otherwise requires, words in the singular shall include the plural and in the plural shall include the singular.
2.5 A reference to a statute or statutory provision is a reference to it as it is in force as at the date of this Agreement.
2.6 A reference to writing or written includes e-mail.
3. User Licences
3.1 Subject to you purchasing the User Licences in accordance with this Agreement, we hereby grant to you a non-exclusive, non-transferable right, without the right to grant sublicences, to permit the Authorised Users to use the Service and the Documentation during the Subscription Term solely for your internal business operations.
3.2 In relation to the Authorised Users, you undertake that:
(a) the maximum number of Authorised Users entitled to use the Service and the Documentation shall not exceed the number of User Licences specified in an Order;
(b) you will not allow or suffer any User Licence to be used by anyone who is not an Authorised User named in an Order unless we have approved the use in writing;
(c) you shall permit us to audit the Service in order to establish the name and password of each Authorised User and any unauthorised use of the Service and you shall pay to us an amount equal to any underpayment.
3.3 You shall ensure that the Authorised Users use the Platform in accordance with this Agreement and shall be responsible for any Authorised User's breach of this Agreement.
3.4 You may, from time to time during any Subscription Term, make a request to purchase additional User Licences and we shall consider such request and, if agreed, grant access to the Service and the Documentation to such additional Authorised Users within a reasonable period.
3.5 You shall use all reasonable endeavours to prevent any unauthorised access to, or use of, the Service and/or the Documentation and, in the event of any such unauthorised access or use, promptly notify us.
3.6 The rights provided under this Agreement are granted to you only, and shall not be considered granted to any subsidiary or holding company of you
4. Service
4.1 We shall, during the Subscription Term and subject to us receiving the Subscription Fees, provide the Service and make available the Documentation to you on and subject to the terms of this Agreement.
4.2 We shall use commercially reasonable endeavours to make the Service available 24 hours a day, seven days a week, except for:
(a) planned maintenance carried out during the maintenance window of 10.00 pm to 2.00 am UK time; and
(b) unscheduled maintenance performed outside Normal Business Hours, provided that we have used reasonable endeavours to give you at least 6 Normal Business Hours' notice in advance.
4.3 If the commencement of the Service or the Service Start Date is conditional upon payment of the Subscription Fees or satisfaction of any other condition, we shall have an absolute discretion to determine that such condition is, in our view, not satisfied or is unlikely to be satisfied and to terminate this agreement with immediate effect without any liability to you.
5. Support Services
We will provide you with up to five (5) hours per week of standard support services during Normal Business Hours as part of the Service and at no additional cost to you, in accordance with our support policy in effect at the time that the Service is provided. We may put in place and amend the support policy in our sole and absolute discretion from time to time in accordance with clause 19.
6. Storage
6.1 Your Software may be stored on the Platform provided that adequate storage capacity has been first agreed in a signed Order and you have paid the applicable storage fees in advance of the storage requirement arising. You are responsible for ensuring that you have purchased adequate storage for your requirements in advance.
6.2 Subject to our obligation to provide storage agreed and paid for in accordance with clause 6.1, we are under no obligation to store Your Software and we are not responsible for any loss or damage to Your Software due to inadequate storage capacity.
6.3 Our storage obligations in clauses 6.1 and 6.2 are subject to the provisions of any storage or back-up policy adopted by us and advised to you from time to time in accordance with clause 19.
7. Variations
7.1 We may, from time to time and without notice to you, vary the Service provided such changes do not have a material adverse effect on the quality of the Service.
7.2 Additional support, services and/or facilities must be agreed in a signed Order (or approved by us in writing) in either case specifying the additional support, services and/or facilities and any Additional Fees that are payable.
8. Restrictions
8.1 For the avoidance of doubt, the restrictions in clause 8.2 shall not apply to Your Software or derivations of Your Software produced using our Service.
8.2 Subject to clause 8.1, you may not:
(a) attempt to copy, modify, duplicate, create derivative works from, frame, mirror, republish, download, display, transmit, or distribute all or any portion of the Platform in any form or media or by any means;
(b) attempt to de-compile, reverse compile, disassemble, reverse engineer or otherwise reduce to human-perceivable form all or any part of the Platform;
(c) license, sell, rent, lease, transfer, assign, distribute, display, disclose, or otherwise commercially exploit, or otherwise make the Platform available to any third party except the Authorised Users;
(d) give access to the Platform through any network of computers to users who are not Authorised Users;
(e) use the Platform to develop a similar or competing product or service;
(f) attempt to reconstruct or discover any source code, underlying ideas, algorithms, file formats or programming interfaces of the Platform;
(g) modify or create derivative works of the Platform;
(h) remove or obscure any product identification or proprietary notices in the Platform; or
(i) publish benchmarks or performance information about the Platform.
8.3 You shall not access, store, distribute or transmit any Viruses, or any material during the course of your use of the Platform that:
(a) is unlawful, harmful, threatening, defamatory, obscene, infringing, harassing or racially or ethnically offensive;
(b) facilitates illegal activity;
(c) depicts sexually explicit images;
(d) promotes unlawful violence;
(e) is discriminatory based on race, gender, colour, religious belief, sexual orientation, disability; or
(f) is otherwise illegal or causes damage or injury to any person or property;
and we reserve the right, without liability or prejudice to our other rights to you, to disable your access to any material that breaches the provisions of this clause.
9. Warranty and disclaimers
9.1 We undertake that the Service will be provided substantially in accordance with the Order and Documentation and with reasonable skill and care.
9.2 The undertaking at clause 9.1 shall not apply to the extent of any non-conformance which is caused by use of the Service contrary to our instructions, or modification or alteration of the Service by any party other than us. If the Service does not conform with the foregoing undertaking, we will, at our expense, use all reasonable commercial endeavours to correct any such non-conformance promptly, or provide you with an alternative means of accomplishing the desired performance. Such correction or substitution constitutes your sole and exclusive remedy for any breach of the undertaking set out in clause 9.1.
9.3 We:
(a) do not warrant that the Service or your use of the Platform will meet your requirements, be fit for a particular purpose or be compatible with any software and hardware
(b) do not warrant that your use of the Service will be uninterrupted or error-free; and
(c) are not responsible for any delays, delivery failures, or any other loss or damage resulting from the transfer of Your Software over communications networks and facilities, including the internet, and you acknowledge that the Service and Documentation may be subject to limitations, delays and other problems inherent in the use of such communications facilities.
9.4 We do not provide any assurance whatsoever in relation to the results of using our Service and our Service should not be considered as advice or an endorsement in respect of any results obtained by using our Service
Large Language Models
9.5 We give no warranty whatsoever regarding your right to access or use Large Language Models or any data comprised within Large Language Models and you acknowledge that you are responsible for:
(a) the selection and use of Large Language Models when using our Service;
(b) obtaining any licenses, consents or approvals that may be necessary or desirable before you access or use Large Language Models or software or data produced by or from Large Language Models; and
(c) complying with all licensing terms and restrictions that apply to your access or use Large Language Models or software or data produced by or from Large Language Models.
9.6 Due to the nature of our Service and artificial intelligence generally, you acknowledge and accept that we make no representations, warranties or guarantees (whether express or implied) that the data, software and content made available to you by utilising Large Language Models, is complete, accurate or up-to-date.
9.7 Our Service makes suggestions and recommendations using Large Language Models however you are responsible for reviewing all suggestions and recommendations and deciding whether to integrate any suggestions and recommendations into Your Software. You assume sole responsibility for testing and assessing results and conclusions drawn from using Large Language Models.
Your Software
9.8 You are responsible for Your Software and represent and warrant that you have all rights, licenses, and permissions required to upload Your Software to the Platform and apply our Service to Your Software.
9.9 You are solely responsible for the application of our Service to Your Software and evaluating the suggestions made by our Service for accuracy and appropriateness for your use case, including by utilizing human review as appropriate.
9.10 We shall have no liability for any damage caused by errors or omissions in Your Software or any information, instructions or scripts provided to us by you in connection with the Service, or any actions taken by us at your direction.
Outputs
9.11 You must assess the suitability, adequacy and appropriateness of our Service and all Outputs and you must rely on your own testing, investigations and professional judgment of the accuracy and usefulness of our Service and all Outputs.
9.12 Due to the nature of our Service and artificial intelligence generally, you acknowledge and accept that:
(a) Output may not be unique and other users may receive similar content by using our Service; and
(b) responses that are requested by and generated for other users are not considered your Output. The assignment of Output contained in clause 10.3 below does not extend to other users’ output or any content delivered by third parties.
10. Proprietary rights
10.1 The Platform belongs to us (or our third party licensors) and you acquire no rights in or to the Platform. Except as expressly stated herein, this Agreement does not grant you any rights to, under or in, any patents, copyright, database right, trade secrets, trade names, trade marks (whether registered or unregistered) or any other rights or licences in respect of the Platform.
10.2 The Platform may incorporate or provide access to Large Language Models and Open-Source Software and we make no representation or warranty whatsoever in relation to such Large Language Models or Open-Source Software. Licenses to which Large Language Models and Open-Source Software are subject shall apply to such Large Language Models and Open-Source Software on a standalone basis instead of this Agreement.
10.3 As between us and you, and to the extent permitted by applicable law, you (a) retain all ownership rights to Your Data and (b) own all Output. We hereby assign to you all our right, title, and interest, if any, in and to Output.
11. Your Data
11.1 We acknowledge that you own all right, title and interest in and to all of Your Data and shall have sole responsibility for the legality, reliability, integrity, accuracy and quality of Your Data.
11.2 You agree that you will be solely responsible for all of Your Data that you create or upload using our Platform. Specifically, you agree, represent and warrant that you have the right to create or upload Your Data and the right to use all materials of which it is comprised and that it will not contravene any of the restrictions in clause 8 (Restrictions).
11.3 You agree that you will be liable to us and will, to the fullest extent permissible by law, indemnify us for any breach of the warranties given by you under clause 11.2. You will be responsible for any loss or damage suffered by us as a result of such breach.
11.4 We may reject, reclassify, or remove Your Data created or uploaded onto the Platform where Your Data, in our sole opinion, violates any of the restrictions in clause 8 (Restrictions).
12. Data Protection
12.1 Both parties will comply with all applicable requirements of the Data Protection Legislation. This clause 12 is in addition to, and does not relieve, remove or replace, a party's obligations under the Data Protection Legislation. In this clause 12, Applicable Laws means (for so long as and to the extent that they apply to us) the law of the European Union, the law of any member state of the European Union and/or Domestic UK Law; and Domestic UK Law means the UK Data Protection Legislation and any other law that applies in the UK.
12.2 The parties acknowledge that for the purposes of the Data Protection Legislation, you are the data controller and we are the data processor (where Data Controller and Data Processor have the meanings as defined in the Data Protection Legislation). Our Data Protection Policy sets out the subject matter, nature and purpose of processing by us, the duration of the processing and the types of personal data (as defined in the Data Protection Legislation, Personal Data) and categories of Data Subject.
12.3 Without prejudice to the generality of clause 12.1 you will ensure that you have all necessary appropriate consents and notices in place to enable lawful transfer of the your Personal Data to us for the duration and purposes of this Agreement.
12.4 Without prejudice to the generality of clause 12.1, we shall, in relation to your Personal Data processed in connection with the performance by us of our obligations under this Agreement:
(a) process your Personal Data only on your written instructions, which may be:
(i) specific instructions given to us by your authorised representative in writing; or
(ii) the general instructions set out in our Data Protection Policy; or
(iii) unless we are required by Applicable Laws to otherwise process your Personal Data. Where we are relying on Applicable Laws as the basis for processing your Personal Data, we shall promptly notify you of this before performing the processing required by the Applicable Laws unless those Applicable Laws prohibit us from so notifying you;
(b) ensure that we have in place appropriate technical and organisational measures to protect against unauthorised or unlawful processing of your Personal Data and against accidental loss or destruction of, or damage to, your Personal Data, appropriate to the harm that might result from the unauthorised or unlawful processing or accidental loss, destruction or damage and the nature of the data to be protected, having regard to the state of technological development and the cost of implementing any measures (those measures may include, where appropriate, pseudonymising and encrypting your Personal Data, ensuring confidentiality, integrity, availability and resilience of our systems and services, ensuring that availability of and access to your Personal Data can be restored in a timely manner after an incident, and regularly assessing and evaluating the effectiveness of the technical and organisational measures adopted by it);
(c) ensure that all personnel who have access to and/or process your Personal Data are obliged to keep your Personal Data confidential;
(d) not transfer your Personal Data outside of the European Economic Area unless your prior written consent has been obtained and the following conditions are fulfilled:
(i) either of us has provided appropriate safeguards in relation to the transfer;
(ii) the data subject has enforceable rights and effective legal remedies;
(iii) we comply with our obligations under the Data Protection Legislation by providing an adequate level of protection to your Personal Data that is transferred; and
(iv) we comply with reasonable instructions notified to it in advance by you with respect to the processing of your Personal Data;
(e) assist you, at your cost, in responding to any request from a Data Subject and in ensuring compliance with our obligations under the Data Protection Legislation with respect to security, breach notifications, impact assessments and consultations with supervisory authorities or regulators;
(f) notify you without undue delay on becoming aware of a Personal Data breach;
(g) at your written direction, delete or return your Personal Data and copies thereof to you on termination of the Agreement unless required by Applicable Law to store your Personal Data; and
(h) maintain complete and accurate records and information to demonstrate our compliance with this clause 6 and allow for audits by you or your designated auditor.
12.5 You consent to us appointing the third parties listed in our Data Protection Policy together with such replacement or additional third parties as we shall notify to you in writing from time to time as third-party processors of our Personal Data under this Agreement. We confirm that we have entered or (as the case may be) will enter with each third-party processor into a written agreement incorporating terms which are substantially similar to those set out in this clause 12.
12.6 We may, at any time on not less than 30 days’ notice, revise this clause 12 by replacing it with any applicable controller to processor standard clauses or similar terms forming party of an applicable certification scheme (which shall apply when replaced by attachment to this Agreement).
13. Charges and payment
13.1 You shall pay the Subscription Fees to us for the User Licences and any Additional Fees in accordance with the terms of each Order and this clause 13.
13.2 If we have not received payment within 7 days after the due date, and without prejudice to any other rights and remedies of us:
(a) we may, without liability to you, disable your password, account and access to all or part of the Service and we shall be under no obligation to provide any or all of the Service while the invoice(s) concerned remain unpaid; and
(b) interest shall accrue on a daily basis on such due amounts at an annual rate equal to 4% over the then current base lending rate of our bankers in the UK from time to time, commencing on the due date and continuing until fully paid, whether before or after judgment.
13.3 All amounts and fees stated or referred to in this Agreement:
(a) shall be payable in pounds sterling;
(b) are non-cancellable and non-refundable;
(c) are exclusive of value added tax, which shall be added to our invoice(s) at the appropriate rate.
13.4 We shall be entitled to increase the Subscription Fees and any Additional Fees at the start of each Renewal Period upon 90 days' prior notice to you and the relevant Order shall be deemed to have been amended accordingly.
13.5 You are not entitled to a refund of Subscription Fees if you cease to use the Service.
14. Confidentiality
14.1 Each party may be given access to Confidential Information from the other party in order to perform its obligations under this Agreement. A party's Confidential Information shall not be deemed to include information that:
(a) is or becomes publicly known other than through any act or omission of the receiving party;
(b) was in the other party's lawful possession before the disclosure;
(c) is lawfully disclosed to the receiving party by a third party without restriction on disclosure; or
(d) is independently developed by the receiving party, which independent development can be shown by written evidence.
14.2 Subject to clause 14.3, each party shall hold the other's Confidential Information in confidence and not make the other's Confidential Information available to any third party, or use the other's Confidential Information for any purpose other than the implementation of this Agreement.
14.3 A party may disclose Confidential Information to the extent such Confidential Information is required to be disclosed by law, by any governmental or other regulatory authority or by a court or other authority of competent jurisdiction.
15. Limitation of liability
15.1 This clause 15 sets out our entire financial liability (including any liability for the acts or omissions of its employees, agents and sub-contractors) to you:
(a) arising under or in connection with this Agreement;
(b) in respect of any use made by you of the Services and Documentation or any part of them; and
(c) in respect of any representation, statement or tortious act or omission (including negligence) arising under or in connection with this Agreement.
15.2 Except as expressly and specifically provided in this Agreement:
(a) we shall have no liability for any disclaimed matters;
(b) all warranties, representations, conditions and all other terms of any kind whatsoever implied by statute or common law are, to the fullest extent permitted by applicable law, excluded from this Agreement; and
(c) the Services and the Documentation are provided to you on an "as is" basis.
15.3 Nothing in this Agreement excludes our liability:
(a) for death or personal injury caused by our negligence; or
(b) for fraud or fraudulent misrepresentation.
15.4 Subject to clause 15.1 and clause 15.3:
(a) we shall not be liable whether in tort (including for negligence or breach of statutory duty), contract, misrepresentation, restitution or otherwise for any loss of profits, loss of business, depletion of goodwill and/or similar losses or loss or corruption of data or information, or pure economic loss, or for any special, indirect or consequential loss, costs, damages, charges or expenses however arising under this Agreement including in relation the supply and use of Third-Party Software; and
(b) our total aggregate liability in contract, tort (including negligence or breach of statutory duty), misrepresentation, restitution or otherwise, arising in connection with the performance or contemplated performance of this Agreement shall be limited to the total Subscription Fees paid for the User Licences during the 12 months immediately preceding the date on which the claim arose.
16. Term and termination
16.1 This Agreement shall, unless otherwise terminated as provided in this clause 16, commence on the Service Start Date and shall continue for the Initial Subscription Term and, thereafter, this Agreement shall be automatically renewed for successive periods of 12 months (each a Renewal Period), unless:
(a) either party notifies the other party of termination, in writing, prior to the commencement of any Renewal Period, in which case this Agreement shall terminate upon the expiry of that Renewal Period; or
(b) otherwise terminated in accordance with the provisions of this Agreement;
and the Initial Subscription Term together with any subsequent Renewal Periods shall constitute the Subscription Term.
16.2 Without affecting any other right or remedy available to it, either party may terminate this Agreement with immediate effect by giving written notice to the other party if:
(a) the other party fails to pay any amount due under this Agreement on the due date for payment and remains in default not less than 10 Business Days after being notified in writing to make such payment;
(b) the other party commits a material breach of any other term of this Agreement which breach is irremediable or (if such breach is remediable) fails to remedy that breach within a period of 10 Business Days after being notified in writing to do so;
(c) the other party suspends, or threatens to suspend, payment of its debts or is unable to pay its debts as they fall due or admits inability to pay its debts or is deemed unable to pay its debts within the meaning of section 123 of the Insolvency Act 1986; or
(d) the other party suspends or ceases, or threatens to suspend or cease, carrying on all or a substantial part of its business.
16.3 On termination of this Agreement for any reason:
(a) all licences granted under this Agreement shall immediately terminate and you shall immediately cease all use of the Services and/or the Documentation;
(b) each party shall return and make no further use of any equipment, property, Documentation and other items (and all copies of them) belonging to the other party;
(c) we may destroy or otherwise dispose of Your Data and Your Software in our possession unless we receive, no later than ten days after the effective date of the termination of this Agreement, a written request for the delivery to you of the then most recent back-up of Your Data and Your Software. We shall use reasonable commercial endeavours to deliver the back-up to you within 30 days of our receipt of such a written request, provided that you have, at that time, paid all fees and charges outstanding at and resulting from termination (whether or not due at the date of termination). You shall pay all reasonable expenses incurred by us in returning or disposing of Your Data and Your Software; and
(d) any rights, remedies, obligations or liabilities of the parties that have accrued up to the date of termination, including the right to claim damages in respect of any breach of the agreement which existed at or before the date of termination shall not be affected or prejudiced.
17. Force majeure
We shall have no liability to you under this Agreement if it is prevented from or delayed in performing our obligations under this Agreement, or from carrying on our business, by acts, events, omissions or accidents beyond our reasonable control, including, without limitation, strikes, lock-outs or other industrial disputes (whether involving our workforce or any other party), failure of a utility service or transport or telecommunications network, act of God, war, riot, civil commotion, malicious damage, compliance with any law or governmental order, rule, regulation or direction, accident, breakdown of plant or machinery, fire, flood, storm or default of suppliers or sub-contractors, provided that you are notified of such an event and its expected duration.
18. Conflict
If there is an inconsistency between any of the provisions in the main body of this Agreement and the Order, the provisions in the Order shall prevail.
19. Variation
No variation of this Agreement shall be effective unless it is in writing and signed by the parties (save for policies in relation to data protection, back-up, storage and support services which we may (acting reasonably) put in place and amend from time to time provided that such policies are notified to you and are in a form typically required by software service providers, in which case such policies shall take effect and be binding upon you from the time they are notified to you).
20. Waiver
No failure or delay by a party to exercise any right or remedy provided under this Agreement or by law shall constitute a waiver of that or any other right or remedy, nor shall it prevent or restrict the further exercise of that or any other right or remedy. No single or partial exercise of such right or remedy shall prevent or restrict the further exercise of that or any other right or remedy.
21. Rights and remedies
Except as expressly provided in this Agreement, the rights and remedies provided under this Agreement are in addition to, and not exclusive of, any rights or remedies provided by law.
22. Severance
22.1 If any provision (or part of a provision) of this Agreement is found by any court or administrative body of competent jurisdiction to be invalid, unenforceable or illegal, the other provisions shall remain in force.
22.2 If any invalid, unenforceable or illegal provision would be valid, enforceable or legal if some part of it were deleted, the provision shall apply with whatever modification is necessary to give effect to the commercial intention of the parties.
23. Entire agreement
23.1 This Agreement constitutes the entire agreement between the parties and supersedes and extinguishes all previous agreements, promises, assurances, warranties, representations and understandings between them, whether written or oral, relating to its subject matter.
23.2 Each party acknowledges that in entering into this Agreement it does not rely on, and shall have no remedies in respect of, any statement, representation, assurance or warranty (whether made innocently or negligently) that is not set out in this Agreement.
24. Assignment
24.1 You shall not, without our prior written consent, assign, transfer, charge, sub-contract or deal in any other manner with all or any of your rights or obligations under this Agreement.
24.2 We may at any time assign, transfer, charge, sub-contract or deal in any other manner with all or any of our rights or obligations under this Agreement.
25. No partnership or agency
Nothing in this Agreement is intended to or shall operate to create a partnership between the parties, or authorise either party to act as agent for the other, and neither party shall have the authority to act in the name or on behalf of or otherwise to bind the other in any way (including, but not limited to, the making of any representation or warranty, the assumption of any obligation or liability and the exercise of any right or power).
26. Third party rights
This Agreement does not confer any rights on any person or party (other than the parties to this Agreement and, where applicable, their successors and permitted assigns) pursuant to the Contracts (Rights of Third Parties) Act 1999.
27. Notices
27.1 Any notice required to be given under this Agreement shall be in writing and shall be delivered by hand or sent by pre-paid first-class post or recorded delivery post to the other party at its address set out in this Agreement, or such other address as may have been notified by that party for such purposes, or sent by email to the other party's last known and previously used email address for receiving correspondence under this Agreement.
27.2 A notice delivered by hand shall be deemed to have been received when delivered (or if delivery is not in business hours, at 9 am on the first business day following delivery). A correctly addressed notice sent by pre-paid first-class post or recorded delivery post shall be deemed to have been received at the time at which it would have been delivered in the normal course of post. A notice sent by email shall be deemed to have been received one Business Day after transmission.
28. Governing law
This Agreement and any dispute or claim arising out of or in connection with it or its subject matter or formation (including non-contractual disputes or claims) shall be governed by and construed in accordance with the law of England and Wales.
29. Jurisdiction
Each party irrevocably agrees that the courts of England and Wales shall have exclusive jurisdiction to settle any dispute or claim arising out of or in connection with this Agreement or its subject matter or formation (including non-contractual disputes or claims).
---
## Actions on an Optimized Version
Learn how to work with your optimized code versions using the available actions in Artemis.
## Available Actions
Once you have optimization results, you can perform several actions on any version. Access these by clicking the menu button (⋮) next to any version.
### Further Optimization

#### Evaluate
- **Purpose**: Run additional performance evaluations on this version
- **Configuration**:
- **Benchmark Repetitions**: Set number of evaluation runs (e.g., 10 for better accuracy)
- **Runner Selection**: Choose specific hardware (e.g., beast9runner)
- **Different Hardware**: Test performance on different systems
- **Use**: Get more accurate performance data or test on target deployment hardware
- **Benefit**: Higher repetitions provide more reliable performance metrics
#### Verify
- **Purpose**: Run additional validation tests on this version
- **Options**:
- **More evaluations**: Run additional benchmarks for better accuracy
- **Different hardware**: Test on different runner/hardware configuration
- **Use**: Confirm performance consistency
#### New Optimization
- **Purpose**: Create another optimization using this version as the starting point
- **Use**: Iterative improvement for even better performance
- **Benefit**: Build upon successful optimizations
### Git Integration
#### Create Changeset
- **Purpose**: Generate a Git changeset for the optimization
- **Use**: Apply changes to your existing Git repository
- **Benefit**: Maintain version control history
#### Push Commit
- **Purpose**: Automatically commit optimized code to your repository
- **Use**: Direct integration with your development workflow
#### Create Pull Request
- **Purpose**: Generate a pull request with the optimization
- **Use**: Code review process before merging optimizations
### Download Actions
#### Download Code
- **Purpose**: Get the optimized source code files
- **Use**: Implement the optimized version in your project
- **Format**: Source code files ready for deployment
## Quick Action Guide
### To Deploy Your Code
1. **Download** → Get the optimized source files
2. Test in your development environment
3. Deploy to production
### To Continue Optimizing
1. **New Optimization** → Use current version as baseline
2. **Verify** → Test on different hardware or with more repetitions
3. Iterate until you reach desired performance
### To Integrate with Git
1. **Create Changeset** → Generate Git-compatible changes
2. **Push Commit** → Direct commit to repository
3. **Create Pull Request** → Initiate code review process
## Best Practices
- **Always download and test** optimized code before production deployment
- **Use verification** when deploying to different hardware than used for optimization
- **Create changesets** to maintain proper version control history
## Tips
- In our example Version 18 shows as "best" - this indicates the highest performing version
- Green performance indicators show excellent results
- Use "Verify" to test optimizations on your target deployment hardware
- Multiple evaluations improve result accuracy but take more time
---
## Creating an Optimization
Learn how to create and configure an optimization in Artemis to find the best-performing combination of your code versions.
## Navigating to a New Optimization
Go to the top-level **Optimisations** tab. It lists all your optimizations — this is where you create new ones and manage existing runs. Click **New optimisation** in the top right to start.

---
## Setting up the optimization
The new-optimization page is a single screen: the **configuration** at the top, and the **code versions to combine** below.

**Configuration**
- **Optimisation name** — a descriptive name to find this optimization later. Leave blank for an auto-generated one.
- **Benchmark repetitions** — how many times each version is re-run; results are averaged. Higher improves accuracy but takes longer (useful for small/fast benchmarks that are noise-prone).
- **Runner** — your connected runner. Make sure it's set up first — see [Artemis Runner](../../features/artemis-runner.md).
**Choose the versions to combine**
- Keep the **Original** as a baseline.
- Prioritise versions with green scores that passed validation.
- Focus on the best performers to keep the run efficient.
Click **Create Optimisation** to start. You'll return to the **Optimisations** tab, where the run first appears as **Pending** and then completes with a **best solution** summary on its card.
---
## Next Steps
1. [Review optimization results](./reviewing-results.md)
2. [Actions on optimized versions](./actions-on-versions.md)
---
## Code Optimization Overview
Artemis provides a **powerful optimization engine** that helps you discover the most effective combinations of code versions to improve performance, memory usage, and CPU efficiency.
While version generation produces multiple alternatives for a given target, **it is not obvious which one is the best** or how it fits in your larger codebase.
With **optimization**, Artemis:
* Uses a **genetic Algorithm** to combine your chosen versions
* Validates them with **real execution metrics** (runtime, memory usage, CPU time, or any custom metric extracted from logs)
* Presents the **top 3 best-performing combinations**
* Lets you perform additional actions such as **git integration, repeated verification, or iterative optimizations**
This ensures you not only generate alternatives but also identify the **best-fit, production-ready code**.
## Optimization Workflow
### [Creating an Optimization](creating-an-optimization.md)
Set up and configure your optimization process:
* Choose versions to include
* Configure benchmark repetitions
* Select runners for execution
* Start the optimization process
### [Reviewing Optimization Results](reviewing-results.md)
Analyze the optimization outcomes:
* Review the **top 3 recommended combinations**
* Compare performance across runtime, CPU, and memory metrics
* Explore detailed insights per code target
* Select the version that matches your performance goals
### [Actions on an Optimized Version](actions-on-versions.md)
Take further actions once you’ve selected an optimized version:
* Run additional evaluations or verifications
* Create new optimizations starting from the current version
* Generate Git changesets, commits, or pull requests
* Download source code or generate detailed reports
## Next Steps
After learning about optimization, you can:
- [Explore use cases](/optimization/code-optimization/creating-an-optimization)
---
## Reviewing Optimization Results
Learn how to read an optimization's results in Artemis and pick the best-performing combination of your code versions.
## Accessing Results
From the **Optimisations** tab, click a finished optimization to open it. Its detail view has three tabs: **Versions**, **Metrics**, and **Insights**.
## Understanding the Results
### Performance summary
Each optimization card shows its **best solution** at a glance — the runtime, CPU, and memory of the strongest combination versus your original code, along with the runner's hardware.

### Versions
The **Versions** tab lists every combination Artemis evaluated.

- **Code Version** — each row is a version built from a combination of your selected changes (the `best` and `target` badges mark the winning and baseline versions).
- **Targets Changed** — how many targets that version touches.
- **Diff** — lines added / removed.
- **Runtime, CPU Time, Memory Usage** — the measured result of each version, each shown with its **% change vs. the original** (green = better, red = worse).
### Metrics
The **Metrics** tab compares every version across **all** of your metrics at once — runtime, CPU, memory, and any custom metrics (such as throughput) you extract from logs — each against the baseline.

Switch to **Compare** to pick any two versions and view them side by side, with **mean comparison** and **run-distribution** charts per metric.

## Key Insights
The **Insights** tab breaks the result down per code target.

- **Location & Versions** — the targets, and the versions chosen for each. Optimization versions are combinations of these.
- **Scores** — the per-target scores for each version.
- **Importance (Runtime / CPU / Memory)** — how much each change contributes to each metric, so you can see what's actually driving the improvement.
- **Weights & filters** — adjust the R / C / M weights, or filter to the **most important** targets, to reorder by what matters to you.
## Selecting the Best Version
- **Speed-critical** → the version with the best **Runtime**.
- **Memory-limited** → the version with the best **Memory**.
- **Balanced** → the **best** combined version (marked in the Versions tab).
## Next Steps
After reviewing results you can take [further actions on optimized versions](./actions-on-versions.md).
---
## Agent Targeting
Agent Targeting is the default, agent-driven way to find optimisation targets. Instead of scanning every file yourself, you describe your goals to the built-in agent on the **Targets** page and it analyses your codebase to surface the highest-impact areas — then creates the targets for you.
## How it works
### 1. Describe your goals to the agent
On the **Targets** page, the right-hand **Activity** panel hosts the agent. Type your optimisation goal in your own words, or pick one of the suggested default prompts to get started.

### 2. Review and create the suggested targets
The agent analyses your codebase and returns a set of suggested targets — each with a file, line range, and a short rationale. Untick any you don't want, then click **Create** to add them to your **Targets** list.

### 3. Read the agent's reasoning
Alongside the targets, the agent explains *why* it chose them — the performance domains it found, the hot paths involved, and what to measure. Use this to decide where to focus and what a good result should look like before generating versions.

Once the targets are in your list, click **Generate versions** on any target to start producing optimised variants.
## When to use it
- You want a quick, high-signal starting point without a full file-by-file scan
- You have a specific optimisation goal and want the agent to find the best targets for it
- You're working with a large codebase and want to narrow down fast
## Next Steps
After targets are created:
1. [Score your targets](scoring-original.md) to further prioritise
2. [Generate new code versions](../version-generation/overview.md)
---
## Chat with Agent
Chat with Agent lets you have an open conversation with Artemis about your codebase. Before you commit to any targets — or let the agent change anything — you can ask questions and get answers, so you understand where the real opportunities are first.
## How it works
In the **Build** tab, open the agent and switch to **Chat** mode. Chat is for exploring: you ask, Artemis answers, and nothing is changed until you decide to act (by moving to **Plan** or **Code**).

Type your question in your own words, or pick one of the default prompts — *Find Optimisation Targets*, *Caching Opportunities*, *Compilation Flag Optimisation*, and more — to get started quickly.
Artemis reads the relevant code and replies with a detailed, grounded answer, citing the exact files and line ranges it's referring to. This is the same purpose it has always served: **check the codebase before doing anything**, so your next step is informed rather than a guess.

## When to use it
- You want to explore and understand your codebase before committing to a targeting approach
- You have questions about specific performance issues and want the agent's input
- You prefer a conversational, iterative workflow over an automated scan
## Next Steps
Once you've pinned down the areas worth optimising:
1. [Score your targets](scoring-original.md) to prioritise them
2. [Generate new code versions](../version-generation/overview.md)
---
## File-by-file targeting
Prefer to hand-pick exactly what Artemis works on? File-by-file targeting lets you browse your repository and turn specific files into optimisation targets yourself — no agent required.
## Browse the file explorer
The left-hand **Files** panel lists every file in your repository, mirroring its folder structure. Expand folders to drill into the tree.

In large codebases, use the **Search files** box at the top of the panel to jump straight to a file by name.

## Add files as targets
Hover over any file in the explorer and click the **+** (**Add target**) button that appears next to it. This opens the **Select files to target** dialog.

## Select files and generate targets
The **Select files to target** dialog shows your full file tree on the left and a preview of the highlighted file's contents on the right — so you can confirm you're picking the right code before committing to it.
Tick every file you want to target, across any folders, then click **Generate targets** to add them all to your **Targets** list in one go.

:::note Accepted file formats
Artemis only extracts targets from source files it can parse. Supported extensions include:
| Language | File Extensions |
|--------------|--------------------------------------------------------------------------------------------------------|
| C++ | .cpp, .c, .h, .hpp, .cc, .hh, .cxx, .hxx, .c++, .h++, .cu, .cuh |
| C | .c, .h |
| Java | .java |
| Python | .py |
| Fortran | .f, .for, .f90, .f95, .f03, .f08, .F, .F90 |
| JavaScript | .js, .jsx |
| TypeScript | .ts, .tsx |
| Ruby | .rb |
| PHP | .php |
| C# | .cs |
| Go | .go |
| Swift | .swift |
| Kotlin | .kt, .kts |
| Scala | .scala |
| Rust | .rs |
| Dart | .dart |
| R | .r, .R |
| Lua | .lua |
| Perl | .pl, .pm |
| SQL | .sql |
| Q | .q |
| COBOL | .cob, .cbl, .cpy |
| OCaml | .ml |
| Elixir | .ex |
| Text | .txt, .md, .html, .css, .scss, .vue, .xml, .json, .yaml, .yml, .ini, .log, .conf, .cfg, .tsv, .rst, .tex, .bat, .sh, .pl, .toml, .properties, .gradle, .maven, .cmd, .awk, .env, .helm, .tpl, .kubeconfig, .npmrc, .prettierrc, .eslintrc, .babelrc, .terraformrc, .tfvars, .tf, .editorconfig, .gitignore, .gitconfig, .zshrc, .bashrc, .profile, .flake8, .pylintrc, .coveragerc, .drl, .m, .jl, .vba, .bas, .cls, .frm |
| Unsupported | .csv |
:::
## Next steps
Once your targets appear in the **Targets** list:
1. [Score your targets](scoring-original.md) to prioritise where to focus
2. [Generate new code versions](../version-generation/overview.md)
---
## Code Targeting Overview
Artemis can work with codebases of any size, from small projects to large enterprise applications. Code targeting lets you extract a focused subset of your codebase so Artemis works on the most impactful areas — reducing processing time and keeping AI context tight and relevant.
---
## Navigating to Code Targeting
### Step 1: Go to the Optimise tab
From your project, click the **Optimise** tab in the top navigation.

### Step 2: Describe your goals to the agent
You'll land on the **Targets** page. The right-hand panel has a built-in chat agent — describe your optimisation goals in your own words, or pick one of the default prompts, and it will analyse your codebase to find the highest-impact areas.

### Step 3: Review and create the suggested targets
The agent returns a set of suggested targets, each with a file, line range, and a short rationale. Review the selection — untick any you don't want — then click **Create** to add them to your **Targets** list.

---
## Targeting Methods
### File-by-File Targeting *(Thorough)*
Scans each file in your codebase individually. Apply filters to extract specific code targets. Best for comprehensive coverage when you want full visibility across the entire project.
- Processes each file sequentially
- Filter by criteria (size, complexity, content patterns)
- Extract targets with full coverage
[Learn more →](file-by-file.md)
---
### Agent Targeting *(Fast)*
Uses an AI agent to analyse your code and identify the highest-impact areas for optimisation. Provides quick results by focusing on high-value sections rather than scanning everything.
- Agent-based codebase analysis
- Priority results based on impact
- Focused approach with quick insights
[Learn more →](agent-targeting.md)
---
### Chat with Agent *(Interactive)*
Have a conversational session with an AI agent about your codebase. Ask questions, explore optimisation opportunities, and get guidance on where to focus — then extract targets directly from the conversation.
- Ask questions about your codebase
- Set optimisation goals through dialogue
- Explore optimisation opportunities interactively
[Learn more →](chat-with-agent.md)
---
## Browsing Your Targets
Once targets and versions have been generated, the top of the Targets page gives you an overview of your exploration space.

**Explore code variants** — Browse single-file variants generated by Artemis. Each target shows the original alongside one or more improved versions. Compare them in a diff view and apply the changes you want. This is your exploration phase: see what's possible across your codebase.
### Two ways to browse
Switch between views any time from the toolbar:
- **Table** — compact spreadsheet layout for scanning many targets at once.
- **List** — card-based layout that surfaces metrics, scores, and version diffs inline.

### What's next from here?
- **Ready to evolve the best combination?** → [Create an Optimisation](../code-optimization/creating-an-optimization.md) — combine your strongest versions and find the best overall result.
- **Want full autonomous multi-file evolution?** → [Discover](../discover/overview.md) — let Artemis autonomously explore and evolve changes across multiple files.
---
## Next Steps
After identifying your targets:
1. [Score your targets](scoring-original.md) to prioritise where to focus
2. [Generate new code versions](../version-generation/overview.md)
3. [Validate the results](../code-validation/code-validation-overview.md)
---
## Score your targets
After analyzing your codebase and extracting targets, the next step is to **score** them.
Scoring helps you understand which parts of your code would benefit most from optimization or improvement.
---
### Step 1: Open scoring options
There are two ways to start scoring a target:
- **Table view** — the balance icon (scale icon) appears next to each target. Click it to begin scoring.
- **List view** — click **Actions** on a target card, then select **Score targets**.


---
### Step 2: Choose scoring method
You’ll see a list of available LLMs and criteria. Select either:
* **LLM** → One result per score per LLM. Cheapest, fastest.
* **Agent** → Adds advanced context awareness, refining results per LLM. More expensive.

:::warning Be mindful of LLM costs
Some models incur costs. Always check the **Estimated Cost** at the bottom of the panel before starting a scoring task.
:::
### Step 3: Define criteria
You can either:
* **Use built-in metrics** (e.g. Optimisation, Quality, Security, Stability).
* **Define your own**:
- Click `Define new` to open the **Define your own score** dialog.
- Enter a **Prompt Name**.
- In **Prompt Text**, describe your scoring criteria in natural language — for example, *"How well does the code scale as the size of the input grows?"*
- Click **Create**.

Custom prompts are marked with a **human figure outline icon**.
### step 4: Choose model(s)
Select one or more models to apply.
### Step 4: Run the scoring
* Click `Score` to start evaluation.
* When complete, results will appear under the **Scores** tab.
### Understanding the results
Artemis provides several default scores:
| Score | Meaning |
| ----------------- | ---------------------------------------------------------------- |
| **Optimisation** | How optimized the code is. |
| **Quality** | Broader measure of code health and inefficiencies. |
| **Security** | Checks for security issues. |
| **Stability** | Identifies potential bugs or failure points. |
| **Average Score** | Average across criteria (and across LLMs if multiple were used). |
Click on any score tile for details on *why* a specific score was assigned.
Low scores indicate areas worth reworking. Once identified, you can move to [Generate code versions](../version-generation/overview.md) to apply improvements.
---
## Semantic Search
Semantic Search is a method for extracting targets by finding similar patterns and potential duplicates across your repository.
It uses embeddings to understand the meaning of code rather than just matching text.
### What It Does?
- Finds semantically similar code (even if variable names differ).
- Detects duplicates and near-duplicates.
- Supports pattern matching and code similarity checks.
When you click on `Semantic Search`, the following page will appear:

Enter a code pattern or keyword in the input box and click `Search`.
Artemis will detect and return the most relevant targets matching your query.
### Example
Suppose you want to find functions in your codebase that **look like a generic function definition**.
You can follow these steps:


## Next steps:
- Evaluate target quality using Artemis scoring. See [Code Scoring](optimization\code-validation\code-evaluation-with-scoring.md).
- Index your code for better context-aware suggestions. See [Code Indexing](/features/code-indexing.md).
---
## Code Scoring
You can generate **new scores** for different versions of a target.
This allows you to compare each version against the original and make better decisions.
Scores can be produced using LLMs or Agents, following the same process you used when scoring your original code (see [Score your targets](../code-targeting/scoring-original.md)).
To start, go to the `Targets` section of your project and select the **New Score** option.
You can either use the built-in scoring criteria or define your own custom rules.
:::note
If you generated target versions using **Artemis Intelligence**, scores are automatically created.
:::
:::note
Make sure your original code has been scored first.
If not, new scores cannot be generated.
:::
#### If you haven't scored your original code yet, see [Score your targets](../code-targeting/scoring-original.md).
---
### Steps to generate new scores
**Step 1 :** Select the **New Score** button.

**Step 2 :** Configure your scoring options:
- Choose between **LLM** or **Agent**.
- Use built-in scoring criteria or define your own.
- Select the model(s) to use.

**Step 3 :** Click `Score`.
**Step 4 :** View your new scores in the results.

---
## Code Validation Overview
After generating alternative code versions for your targets, Artemis provides tools to help you decide which versions are best to integrate into your project.
This stage ensures that quality, correctness, and performance are thoroughly assessed before merging.

## Validation Areas
Code validation in Artemis consists of two main areas:
### 1.Evaluate New Versions
Run structured checks to measure quality and reliability.
- **[Scoring](./code-evaluation-with-scoring.md)**: Assess code quality against defined criteria such as maintainability, readability, or complexity.
- **[Validation](./validation-and-performance-metrics.md)**: Execute the code to test correctness, performance, and reliability.
#### Ensure your build environment is configured, see [Project Settings](../../project-setup/settings/runner-and-scripts.md) if not already set up.
### 2.[Review and Compare](./review-and-compare-new-versions.md)
Explore generated versions side-by-side with the original. Inspect logs, analyze detailed scores, and take informed actions on each version.
By combining **structured evaluation (scoring + validation)** with **interactive review and comparison**, you gain a complete picture of each version’s quality and impact.
## Next Steps
- [Learn about Code Optimization](../code-optimization/overview.md)
---
## Review and Compare
After Artemis generates optimized versions of your targets, you can **review and compare** them using several built-in tools.
---
Navigate to the `Targets` tab to explore all generated code variations.
Click on any `version` to open its details and access the following features:
* ### **Side-by-side comparison** with the original code.
* ### **Artemis Chat**: ask questions or request clarifications about how or why a version was produced.

* ### **Log filtering**: quickly narrow down relevant outputs.
*(Execution logs are available only when you validate a version or run it internally with Artemis Intelligence.)*
Search the output or filter by status (Info, Debug, Warn, Error) to focus on what matters.

Every log for the version is listed in the **Logs** panel — click any entry to open it.

* ### **Performance & score data**: compare every version's measured results side by side.
Open the **Data** tab to see all versions against the `baseline` — each cell shows the value and its **% change**.

- **Runtime / CPU / Memory** — measured execution time, CPU time and peak memory (lower is better).
- **XXH128 / XXH32 / XXH3 64b / XXH64 MBps** — your custom throughput metrics, one per algorithm (higher is better).
- **Clarity / Hot-path** — quality scores for the version (higher is better).
Once you've chosen the best version, use **Create PR** to package it — **Create Changeset** to combine versions across targets, or **Create PR** to open a pull request directly. See [Changesets](../../features/changeset.md) for the full flow.
### Next steps:
- You can start [making optimization](../code-optimization/overview.md).
- You can make a [changeset](../../features/changeset.md) with your desired combination of versions.
---
## Validate New Versions
Validation ensures that generated versions not only **look correct** but also **function as intended**.
Artemis provides three main validation options:
* **Compile**: checks if the code builds successfully
* **Test**: runs unit tests to verify functionality
* **Benchmark**: measures runtime and performance
In addition, Artemis tracks performance metrics such as **runtime**, **CPU time**, and **memory usage**, providing deeper insight into efficiency.
:::note Performance metrics explained
* **Runtime** → total execution time of the benchmark
* **Memory usage** → unique set size, memory exclusively used by the process.(USS)
* **CPU time** → actual CPU processing time consumed
:::
Want to track domain-specific measurements too — throughput, accuracy, error rate? See [Custom Metrics](../../features/custom-metrics.md) to add your own alongside these built-in ones.
#### If you haven’t set up your project’s build settings yet, see [Project Settings](../../project-setup/settings/runner-and-scripts.md).
## How to Validate
### **Step 1: Select target(s)**
You can validate all targets at once or validate each target individually.
Click the **triangle button** next to a version to start.

### **Step 2: Configure validation**
* Choose one or more options: *compile, test, benchmark*
* Select your preferred online runner
* (Optional) Enable **Compare with Original**: reruns the original code and update value of metrics.
* Rhen click on `run`

### **Step 3: view results**
* View **performance metrics** (runtime, CPU, memory)
* Access **execution logs** for detailed insights
Each version has a **Checks** column showing the status of its **Compile**, **Test**, and **Benchmark** runs. Click a check to open its log in the **Activity** panel, where you can read the full output, **search** it, and **filter by status**.
When a check shows **Failed**, open its log to see exactly *why* — for example, a compile error in a generated version — so you can decide whether to discard that version or adjust your target.

---
## Experiments
An **Experiment** is the main unit of Discovery — a distinct approach the agent tries against your objective, each carrying a **confidence score**. The **Experiments board is the default view**, organising every experiment by its **lifecycle status**.
## The board

Experiments move left to right through these statuses:
- **Draft** — proposed but not yet accepted. **Queue** it to accept, or **Dismiss** it.
- **Queued** — accepted and waiting to run.
- **In Progress** — currently being generated and validated on your runner.
- **Concluded** — finished, and marked **Validated**, **Refuted**, or **Inconclusive** once its versions are scored.
- **Dismissed** — discarded.

You can **drag** cards between columns, **bulk-select and combine** experiments, and add your own with **New**. When at least one experiment is queued, click **Resume** to continue the run.

Once at least one experiment is queued, the banner switches to **Ready to resume**. Click **Resume** and the agent picks up the queued experiments, generates and validates their **Versions** on your runner, and scores them against your [Goals](./goals.md). In **Manual approval mode** it then pauses again for your next round of approvals; with Manual approval off, it keeps going automatically until the run completes.
Each concluded experiment links to the [Versions](./versions.md) it produced.
---
## Goals
**Goals** are the fitness criteria every version is scored against — they define what "better" means for your run. Each goal has a **direction** (Maximise or Minimise) and a **weight**; the weights sum to **1.00** and determine how much each metric counts toward a version's overall score.

## Metric types
- **Worker** metrics are **measured on your runner** — the built-in runtime, CPU, and memory, plus any **custom benchmark metrics** your benchmark records (e.g. `XXH32_MBps`, `XXH64_MBps`). See [Benchmarks](../../project-setup/settings/benchmarks.md) for how these are produced.
- **LLM** metrics are **judged by the review panel** — qualitative criteria the reviewer models score, such as `seed_option_malformed_input_robustness`, `hash_output_compatibility`, `cli_regression_coverage_depth`, and `fix_scope_and_maintainability`.
## Direction and weights
- **Maximise / Minimise** sets which way is "better" for each metric.
- The **weight** column sets each metric's importance. In this run the primary goal — robust handling of a malformed `--seed` operand — is weighted **0.60**, so it dominates scoring, while the performance metrics are kept small as non-regression guardrails.
- Weights must total **1.00** — use **Normalise** to rescale them, then **Save & recompute** to re-score every version against the updated goals.
You can **pin** goals and tune weights at any point during a run; recomputing re-ranks the versions — and the **★ BEST** pick — accordingly.
---
## Graph
The **Graph** is the main view of a Discovery run — a visual map that grows from your objective into the experiments the agent tries and the versions they produce. Use the **Compact / Full** toggle to switch between a stacked list of cards and the full branching tree, and **New** to add an experiment of your own.
## Reviewing and steering drafts
The agent proposes **draft experiments**, each with a confidence score. **Recommended drafts are highlighted.** For each draft you can:
- **Queue** — accept it so the agent will work on it
- **Dismiss** — discard it

:::note Manual approval vs. automatic
This step-by-step review happens because **Manual approval mode** is on — the run pauses (*"Awaiting your approval"*) and waits for you to **Queue** at least one draft and click **Resume**. Turn Manual approval mode **off** and the agent queues and proceeds through experiments **automatically**, without pausing for you.
:::
## Nodes
The tree is built from three node types:
- **Objective** — the goal you typed in; it anchors the graph.
- **Experiment** (`EXP-…`) — a distinct approach, with a confidence score.
- **Version** (`v1`, `v2`, …) — the actual code diff an experiment produced, with a **fitness delta** vs. baseline (e.g. `+0.53`).
Click any node to open its detail panel. On a **version** node, two actions let you keep exploring:

- **Generate variations from here** (the **+** icon) — branch new experiments off this version.
- **Combine with another node** (the merge icon) — merge this version with another to blend their changes.
Every queued experiment runs your **Run config** (build, test, benchmark) against each version, so versions arrive already scored.
---
## Discover
**Autonomous multi-file evolution**
Describe a goal and the agent runs the full cycle autonomously, building **Experiments**, generating multi-file **Versions**, and carrying the best results forward.
Need per-file diff exploration? [Targets](../code-targeting/overview.md) · Need to combine specific changes? [Optimise](../code-optimization/creating-an-optimization.md)
---
## Starting a Discovery Run
From the **Discover** page, describe what you want the agent to discover or optimise in the goal input, adjust the settings below, and submit. You can also pick one of the **starting-point** suggestions (e.g. *Optimise performance*, *Cut runtime by 20%*, *Find and fix the highest-value bug*) to prefill a goal.

---
## Configuration
Before starting a run, configure how Discover explores your codebase and how each version is validated:
| Setting | Description |
|---|---|
| **Model** | The LLM that drives the discovery (e.g. GPT-5.6). Pick it by name or by effort tier. |
| **Versions** | How many versions to generate in the run (up to 10) — Discovery can produce multiple experiment versions simultaneously. |
| **Run code after each version** | Automatically executes and validates each version as it is generated, using your runner and scripts. |
| **Manual approval mode** | Pauses for your approval before each experiment proceeds, so you can review queued work first. |
| **Reviewers** | One or more LLMs that independently score each experiment *before* budget is spent on it — a multi-LLM review panel with confidence ratings and critique notes. |
| **Runner** | The connected runner that executes the scripts for each version. |
| **Compile / Unit test / Benchmark** | The scripts run against every version, taken from your [Runner and Scripts](../../project-setup/settings/runner-and-scripts.md) setup. |
---
## Inside a Discovery Run
Once a run starts, the left sidebar gives you the views you need to navigate the run:
- **Overview** - run summary, run configuration, and the current best version
- **Graph** - visual graph of the full run
- **Experiments** - list of all Experiments and their status
- **Versions** - list of all generated code versions, scores, and diffs
- **Goals** - the fitness criteria the agent is optimising toward
### Overview
The **Overview** is the starting point for a run. It shows the run's **Objective**, the agent's **notes**, live counts of **Experiments** and **Versions**, the **Run config** used to validate every version, and the current **best version**.

#### Agent notes
The **Agent notes** panel (expand it with **Show more**) is the agent's running context and findings for the run. It typically captures:
- **Baseline assessment** — what the codebase is, how it builds and tests, and the constraints to preserve. For xxHash, that's the strict `-O3` warning build, `make check`, and hash outputs that must stay bit-identical across platforms.
- **The strongest defect found** — the highest-value issue the agent will target, and why it matters. In this run it flagged a real crash: `xxhsum --seed` with no value reads past `argv` and passes `NULL` to the seed parser, segfaulting on ordinary malformed input.
- **Other weaknesses surveyed** — lower-priority issues it noticed but did not prioritise.
- **Measurable baseline for scoring** — the metrics and constraints versions are scored against (correctness, the strict-warning build, and performance treated as a non-regression constraint).
Reading these notes tells you *why* the agent proposes the experiments it does — which is what you use to decide what to queue and approve.
#### Run config
The Run config defines how each version is built, verified, and measured. Set up a **runner** and provide a command for each stage — every stage runs in order against each version the agent produces:
| Stage | Purpose |
|---|---|
| **Runner** | The execution environment that carries out the build, test, and benchmark commands. If none is connected, [set up a runner](../../project-setup/settings/runner-and-scripts.md) from the project's runner setup section. |
| **Build** | Compiles your project. Runs first, before every test, so only valid code moves forward. |
| **Test** | Guardrails that verify each code change. Make sure these tests cover the code being optimised. |
| **Benchmark** | Measures performance and writes custom metrics that are compared across versions. |
You control when this pipeline runs: enable **Run code after each version** to validate every version as it is generated, or leave it off and run only the versions you select on demand.
---
## Next Steps
- [Tutorials](./tutorials/overview.md) — learn with your coding agent how to drive Discovery through the CLI by example
- [Code Targeting](../code-targeting/overview.md) - identify specific targets for manual, per-file exploration
- [Creating an Optimisation](../code-optimization/creating-an-optimization.md) - combine specific versions you've already selected
- [Reviewing Results](../code-optimization/reviewing-results.md) - understand the output metrics
---
## Discovery tutorials
These tutorials help you and your coding agent learn how to drive Discovery through the Artemis CLI. Rather than documenting commands in isolation, they use Particle Life as a small, measurable project and take you through complete workflows you can adapt to your own repository.
The agent can run most commands, apply the relevant Artemis skills, and explain the results. You remain responsible for credentials, account-level choices, and reviewing consequential decisions.
## Where to start
Start with [Get started with Particle Life](./particle-life-example.md). It establishes the shared setup—skills, CLI authentication, Git access, and a runner—and completes a Discovery run from import through result inspection.
The other tutorials assume that foundation is in place. Follow them in order for a progressive learning path, or choose the one that matches the problem you need to solve.
## Tutorials
### [Get started with Particle Life](./particle-life-example.md)
Learn the complete agent-assisted workflow: install the skills, authenticate the CLI, bring a runner online, import Particle Life, start Discovery, and inspect the winning change.
### [Make a repository ready](./particle-life-harness-example.md)
Start from a repository without a benchmark harness. Fork it, add compile, test, and benchmark commands that emit numeric Artemis results, import the prepared repository, and run Discovery.
### [Verifying commands on a runner](./particle-life-runner-commands-example.md)
Validate compile, test, and benchmark commands in the environment where Discovery will execute. Use process logs to diagnose failures, fix the harness, pull the updated project, and verify it again.
### [Steer a running discovery](./particle-life-steering-example.md)
Start a focused run, redirect the active Discovery agent toward a different optimisation strategy, extend the version budget, and inspect how the run responded.
## What you should take away
By the end of the series, you should understand how to use a coding agent and the Artemis skills to prepare a project, validate its execution pipeline, run and steer Discovery, and interpret the measured results from the CLI.
---
## Get started with Particle Life
## Basic goal
This example gets you familiar with using a coding assistant to drive Artemis. The assistant will use the Artemis skills and CLI to import a ready-made C++ project, start a Discovery optimisation run, and inspect what it found.
The assistant can carry out most of the workflow, but you remain in control. You provide credentials and make account-level choices, while the assistant explains and verifies each stage. The commands are included so that you can follow what it is doing and reuse the process for your own project.
## Machine prerequisites
The machine that will run Particle Life needs:
- CMake 3.16 or newer, including `ctest`;
- a C++17 compiler; and
- Python 3.
The walkthrough below guides you through Artemis authentication, Git access, and bringing the runner online.
## What you and your assistant will have done
By the end of the example, you and your assistant will have:
- loaded the Artemis skills into your coding assistant;
- installed and authenticated the Artemis CLI;
- brought a compatible runner online;
- imported Particle Life at a known revision;
- run Discovery against the `simulation_fps` benchmark; and
- compared the baseline with the best candidate and inspected what changed.
You should also understand which inputs—repository, commands, metric, task, runner, model, and version budget—you would replace for your own project.
## What this example does not cover
- Writing a benchmark harness or making an arbitrary repository Artemis-ready. Particle Life already provides compile, test, and benchmark commands. For that workflow, see [Make a repository ready](./particle-life-harness-example.md).
- Validating commands on a specialised target runner when local and remote environments differ, for example when a project requires dependencies on a remote machine. For that workflow, see [Verifying commands on a runner](./particle-life-runner-commands-example.md).
Those are important steps for many real projects, but this example deliberately starts with an Artemis-ready repository.
## What is Particle Life?
[Particle Life](https://github.com/turintech/particle-life) is a deterministic C++17 simulation in which five species of particles move in a toroidal 2D world according to fixed interaction rules. A checksum-based test pins the simulation behaviour, so making it faster must not change the physics.
The repository ships an optional Tk renderer, shown above.
```bash
python3 tools/window_renderer.py --duration 10
```
The seed implementation checks every pair of particles in `Simulation::step()`, an **O(N²)** operation, even though forces only act within a fixed radius. This gives Discovery a clear optimisation problem and `simulation_fps` gives it a numeric metric to maximise.
## Let's begin
### 1. Install the skills
You or the assistant can follow [Artemis Skills](../../../features/artemis-agent-skills.md) to install or load the skills for your assistant host. Finish this before the assistant sets up the CLI or runs Discovery: the skills tell it how to carry out and verify each stage.
If the host requires a session reload, that is a human action. For example, after installing the Claude Code plugin, run `/reload-plugins` and then verify the installation with `/plugin list`.
**Checkpoint:** the assistant can access the Artemis skills, including `cli-setup`, `runner-setup`, `project-import`, `discovery-start`, and `discovery-inspect`.
### 2. Complete the prerequisites
Ask the assistant to use the relevant skill for each item and explain the result. Stop at any human-only action rather than pasting credentials into the conversation.
1. **Install and authenticate the CLI** (`cli-setup`)
- The assistant can install the CLI and check its configuration.
- You must create an Artemis API key in the web UI and enter it in your own terminal.
- **Checkpoint:** `artemis status` reports `Status: ok` for Configuration and Authentication. The service probes may say `ok reachable (HTTP 404)`; that is healthy.
2. **Connect a Git provider and identify a Git key**
- You must connect a provider in the Artemis web UI if your account does not already have one.
- The assistant can run `artemis key list` and record the key ID. A key ID is required for import even though Particle Life is public.
- **Checkpoint:** `artemis key list` returns at least one key ID.
3. **Set up a runner** (`runner-setup`)
- The assistant or a human can install and start the runner.
- Confirm that `cmake`, `ctest`, the C++17 compiler, and `python3` are all available on the runner's `PATH`.
- Start it with `--no-delete-task-output` if you want the assistant to inspect logs and files from failed versions later.
- **Checkpoint:** `artemis runner list` shows the chosen runner as online.
Particle Life already contains the required compile, test, and benchmark commands, so there is no repository-side setup. In particular, the benchmark must run headlessly:
```bash
python3 tools/benchmark.py --no-visualize
```
## Run Discovery
The following steps show the skill the assistant should use, the shape of the CLI command, and the evidence that the step succeeded. Ask the assistant to work through them in order and pause whenever it needs a credential or account choice from you.
### 1. Confirm readiness
**Skill:** `cli-setup` and `runner-setup`
```bash
artemis status
artemis key list
artemis runner list
artemis model list
```
Use the output to select the Git key ID, runner name, and catalogue UUID for `gpt-5.6-terra`.
**Checkpoint:** authentication is healthy, a Git key exists, the runner is online, and the model is available. Do not start a run while any of these checks is unresolved.
### 2. Import Particle Life
**Skill:** `project-import`
```bash
artemis project import \
--git-url https://github.com/turintech/particle-life \
--key-id \
--branch main \
--name particle-life
```
The public repository can be imported directly; you do not need to fork or clone it. Import is asynchronous, so the command returning only proves that it was queued. Check the project list until the imported project reports `importedStatus: success`:
```bash
artemis --output-format json project list
```
Then verify the seed revision:
```bash
artemis project compare
```
The expected upstream head is:
```text
1399caa42c2c9a473853008ceb945c0c21ad839f
```
If `main` has moved and you want to reproduce this example at the same revision, pin it before starting Discovery:
```bash
artemis project branch --branch main \
--sha 1399caa42c2c9a473853008ceb945c0c21ad839f
```
**Checkpoint:** import reached `success` and the project points at the intended revision. The assistant gives you a clickable project link:
```text
https://artemis.turintech.ai/projects/
```
### 3. Start the optimisation
**Skill:** `discovery-start`
```bash
artemis discovery create \
--project \
--task "Maximize simulation_fps without changing simulation behavior or weakening the correctness tests." \
--versions 10 \
--compile-cmd "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--test-cmd "ctest --test-dir build --output-on-failure" \
--benchmark-cmd "python3 tools/benchmark.py --no-visualize" \
--target-files src/simulation.cpp \
--target-files src/simulation.hpp \
--runner \
--mode automatic \
--model
```
Pass each target file with its own `--target-files` flag. The hot loop is in `src/simulation.cpp`, but an algorithm such as a spatial grid may need new member state in `src/simulation.hpp`.
The commands are passed inline so the run records exactly how candidates were compiled, tested, and measured.
**Checkpoint:** the run has a non-null `baselineObservationId`, `baselineVersionSha`, and `metricsSchema`, and `versionCount` is at least 1. A finalised baseline alone does not prove that exploration started. The assistant gives you a clickable Discovery link:
```text
https://artemis.turintech.ai/projects//discovery/
```
### 4. Monitor the run
**Skill:** `discovery-inspect`
```bash
artemis discovery get
artemis discovery versions list
```
The assistant should confirm that the baseline was measured, versions were generated, and completed versions passed the supplied compile, test, and benchmark commands. Individual versions may fail; that does not make the whole run invalid.
If the run appears inactive, inspect the runner log. Gaps while the Discovery agent plans its next candidate are normal.
**Checkpoint:** the run reaches a terminal state and at least one candidate has a measured `simulation_fps`.
### 5. Inspect and report the result
**Skill:** `discovery-inspect`
The assistant should:
1. report the baseline and best measured `simulation_fps`;
2. account for the 10-version budget, including failed versions;
3. rank candidates by `simulation_fps`, not only by composite fitness;
4. retrieve and read the winning diff; and
5. explain whether it found an algorithmic change, a smaller local optimisation, or no meaningful improvement.
**Checkpoint:** you know what improved, by how much on this runner, and what code produced the result.
## What to expect
Discovery is a stochastic search. Different runs against the same seed can produce very different improvements, and some versions may fail during generation, compilation, or scoring.
The purpose of the example is to learn how to:
- give Discovery a measurable goal and a fixed correctness check;
- distinguish a healthy baseline from active exploration;
- interpret how the version budget was spent; and
- verify that the best metric belongs to a change you would actually accept.
Both algorithmic changes (for example a spatial grid over the O(N²) pair loop) and compiler or build-flag changes can improve `simulation_fps`. How large the gain is depends on the runner environment. Rank candidates by your primary metric and read the full metric set alongside the winning diff so you stay focused on that goal; confirm the checksum test remains intact. Model-judged qualitative scores are review signals, not measurements.
Have fun experimenting to see what you can find!
## Optional next steps
- **Verify the winner independently:** pull the candidate diff, apply it to a clean checkout of the pinned seed, rebuild, run `./build/particle_life_tests`, and compare checksums at another particle count.
- **Learn to redirect a live run:** follow [Steer a running discovery](./particle-life-steering-example.md) to steer from compiler flags to source algorithms, then expand the budget.
- **Make a repository Discovery-ready:** follow [Make a repository ready](./particle-life-harness-example.md) to fork the no-benchmark lab branch, author a harness, and import your fork.
- **Verify commands on a runner:** follow [Verifying commands on a runner](./particle-life-runner-commands-example.md) to iterate commands remotely, fix a harness, and `project pull` before Discovery.
- **Adapt the workflow:** replace the repository URL and revision, runner environment, compile/test/benchmark commands, metric, task, target files, model, and version budget for your own project.
### Troubleshooting
Use `discovery-inspect` and retained runner output to investigate a run with no measured versions. Check authentication, Git key, import status, runner availability, headless benchmark configuration, and model selection first. Failed individual versions are normal; a run that finishes without measuring any candidate is not.
---
## Make a repository ready
## Goal
This example assumes you have completed [Get started with Particle Life](./particle-life-example.md): skills loaded, CLI authenticated, Git key available, and a compatible runner online.
Unlike the basic example, this lab starts from a branch **without** a Discovery-ready benchmark. You will fork it, author a harness that writes `artemis_results.json`, push, import your fork, and run a short Discovery.
## What you will learn
- when a repository is not yet Artemis-ready;
- how to author a headless harness that emits numeric metrics;
- how to verify compile → test → benchmark before import; and
- how to run Discovery against a repository you own.
## Teaching seed
Use the public lab branch:
```text
https://github.com/turintech/particle-life
branch: lab/no-benchmark
commit: 92b0b7d0e55f39361d7f5d01cc37d19932213237
```
That revision keeps CMake, the simulation library, checksum tests, and a timed `./build/particle_life benchmark` path that prints `fps=` to stdout. It does **not** provide `tools/benchmark.py` or write `artemis_results.json`.
## 1. Fork and clone the lab branch
**Skill:** `repo-prepare-fork`
Ask the assistant to fork `turintech/particle-life` under your account (explicit permission required), then clone your fork and check out `lab/no-benchmark` at the commit above.
```bash
gh repo fork turintech/particle-life --clone=true
cd particle-life
git fetch origin lab/no-benchmark
git checkout lab/no-benchmark
git rev-parse HEAD # expect 92b0b7d0e55f39361d7f5d01cc37d19932213237
```
**Checkpoint:** the checkout is your fork, on `lab/no-benchmark`, at the lab commit.
## 2. Author the harness
**Skill:** `repo-command-setup` (companion `HARNESS.md`)
Ask the assistant to add a repository-owned headless script (typically `tools/benchmark.py`) that:
1. requires `build/particle_life`;
2. removes any stale `artemis_results.json` / `.csv`;
3. runs a timed workload equivalent to 2,200 particles and 30 frames after warmup (wrapping `./build/particle_life benchmark 2200 30` is fine);
4. writes numeric `{"simulation_fps": ...}` to `artemis_results.json` at the repository root;
5. stays headless — no visualization window.
Keep `ctest` as the correctness gate. Do not weaken checksum determinism to chase speed.
**Checkpoint:** the harness exists in the working tree and is ready to verify.
## 3. Verify the three commands
**Skill:** `repo-command-setup`
```bash
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel
ctest --test-dir build --output-on-failure
rm -f artemis_results.json artemis_results.csv
python3 tools/benchmark.py --no-visualize # or the script path you chose
test -f artemis_results.json
```
Confirm `artemis_results.json` contains a numeric `simulation_fps`. Record the exact compile, test, and benchmark command strings for Discovery.
**Checkpoint:** all three commands pass from the repository root and the results file is fresh and numeric.
## 4. Push, then import your fork
Push the harness commit to your fork:
```bash
git add tools/benchmark.py # plus any supporting files
git commit -m "Add Discovery-ready simulation_fps harness"
git push -u origin lab/no-benchmark
```
**Skill:** `project-import`
Import the **fork** URL and `lab/no-benchmark` branch — not upstream `main`:
```bash
artemis project import \
--git-url https://github.com//particle-life \
--key-id \
--branch lab/no-benchmark \
--name particle-life-harness-lab
```
Wait until `importedStatus` is `success`, then confirm the imported `gitHash` matches your harness commit.
**Checkpoint:** Artemis project UUID exists and points at your harness revision.
## 5. Run a short Discovery
**Skills:** `discovery-start`, then `discovery-inspect`
```bash
artemis discovery create \
--project \
--task "Maximize simulation_fps without changing simulation behavior or weakening the correctness tests." \
--versions 5 \
--compile-cmd "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--test-cmd "ctest --test-dir build --output-on-failure" \
--benchmark-cmd "python3 tools/benchmark.py --no-visualize" \
--target-files src/simulation.cpp \
--target-files src/simulation.hpp \
--runner \
--mode automatic \
--model
```
Use the same verified commands inline. Monitor with `discovery get` / `versions list` until the baseline is finalised and at least one version has measured `simulation_fps`.
**Checkpoint:** Discovery ran on your user-owned harness; rank candidates by measured `simulation_fps`, not only fitness.
## What to expect
- The lab teaches the Artemis metrics contract: stdout timing alone is not enough.
- First harness drafts often forget headless mode, stale results files, or writing at the repo root — local verification catches those before import.
- Discovery is still stochastic; a successful lab proves the repository is ready, not that every run finds a large speedup.
## Optional next steps
- [Verifying commands on a runner](./particle-life-runner-commands-example.md) when you must iterate commands on the runner and pull script fixes into the project.
- [Steer a running discovery](./particle-life-steering-example.md) to redirect a live run and expand its budget.
- Adapt the same harness pattern to your own repository: choose a metric, add a correctness gate, emit `artemis_results.json`, verify, import, discover.
---
## Verifying commands on a runner
## Goal
This example assumes you have completed [Get started with Particle Life](./particle-life-example.md): skills loaded, CLI authenticated, Git key available, and a compatible runner online.
Unlike the basic example, you will **not** treat local compile/test/benchmark success as the gate. You will fork a teaching branch, import it, iterate command strings on the runner with `changeset validate`, fix a broken harness in Git, pull the project to the new commit, re-validate, and run a short Discovery.
## What you will learn
- how to try different compile, test, and benchmark command strings on a runner;
- how to read `artemis process logs` when exit codes alone are not enough;
- how to update project code after editing scripts (`project pull`, not `project sync`); and
- why a fresh empty changeset is required after the project's `gitHash` moves.
## Teaching seed
Use the public lab branch:
```text
https://github.com/turintech/particle-life
branch: lab/runner-commands
commit: 00f6b2d484d05be9cb6e652573e4953b3cc1b9e5
```
That revision keeps CMake, the simulation library, and checksum tests. `./build/particle_life benchmark` prints `fps=` to stdout only. `tools/benchmark.py` exists but writes `artemis_results.json` under `tools/` instead of the repository root.
## 1. Fork and clone the lab branch
**Skill:** `repo-prepare-fork`
Ask the assistant to fork `turintech/particle-life` under your account (explicit permission required), then clone your fork and check out `lab/runner-commands` at the commit above.
```bash
gh repo fork turintech/particle-life --clone=true
cd particle-life
git fetch origin lab/runner-commands
git checkout lab/runner-commands
git rev-parse HEAD # expect 00f6b2d484d05be9cb6e652573e4953b3cc1b9e5
```
**Checkpoint:** the checkout is your fork, on `lab/runner-commands`, at the lab commit.
## 2. Import the fork
**Skill:** `project-import`
Import the **fork** URL and `lab/runner-commands` branch — not upstream `main`:
```bash
artemis project import \
--git-url https://github.com//particle-life \
--key-id \
--branch lab/runner-commands \
--name particle-life-runner-commands-lab
```
Wait until `importedStatus` is `success`, then confirm the imported `gitHash` matches the lab commit.
**Checkpoint:** Artemis project UUID exists and points at the teaching seed. Do not treat a local build as verification.
## 3. Level 1 — try commands on the runner
**Skill:** `repo-command-setup` (§5b)
Create an empty changeset, then validate candidate command triples on your runner:
```bash
artemis --output-format json changeset create --project
# → capture
artemis --output-format json changeset validate \
--project --version original \
--command "make -j\$(nproc)" \
--command "ctest" \
--command "./build/particle_life benchmark 2200 30" \
--runner --wait
```
Expect failures. Iterate toward working compile and test strings:
```bash
artemis --output-format json changeset validate \
--project --version original \
--command "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--command "ctest --test-dir build --output-on-failure" \
--command "python3 tools/benchmark.py --no-visualize" \
--runner --wait
```
Reuse the same empty changeset while only changing `--command` strings. Capture `status.id` from the validate response and inspect what the benchmark actually did:
```bash
artemis process logs
```
Compile and test should reach `exitCode: 0`. The harness still writes metrics under `tools/`, so the Artemis results contract is not satisfied even when the benchmark process exits zero. Exit codes never report metric values or results-file location — the process log does.
**Checkpoint:** you have working compile/test commands and evidence from process logs that the harness writes to the wrong path.
## 4. Level 2 — edit, push, and update project code
Fix `tools/benchmark.py` so it writes numeric `{"simulation_fps": ...}` to `artemis_results.json` at the **repository root** (not under `tools/`). Keep the harness headless.
```bash
git add tools/benchmark.py
git commit -m "Write simulation_fps to root artemis_results.json"
git push origin lab/runner-commands
```
Update the Artemis project to the new commit. `project sync` only enables auto-sync; use `project pull` to fetch:
```bash
artemis project compare
artemis project pull
```
Wait until the project's `gitHash` matches your fix commit.
Create a **new** empty changeset after the pull. The previous changeset's `original` stays on the old SHA.
```bash
artemis --output-format json changeset create --project
# → capture
artemis --output-format json changeset validate \
--project --version original \
--command "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--command "ctest --test-dir build --output-on-failure" \
--command "python3 tools/benchmark.py --no-visualize" \
--runner --wait
artemis process logs
```
Confirm every command shows `exitCode: 0` and the logs show a root-level numeric `simulation_fps` write.
**Checkpoint:** the project's original code includes the fixed harness, and runner validation proves the three Discovery commands.
## 5. Run a short Discovery
**Skills:** `discovery-start`, then `discovery-inspect`
```bash
artemis discovery create \
--project \
--task "Maximize simulation_fps without changing simulation behavior or weakening the correctness tests." \
--versions 5 \
--compile-cmd "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--test-cmd "ctest --test-dir build --output-on-failure" \
--benchmark-cmd "python3 tools/benchmark.py --no-visualize" \
--target-files src/simulation.cpp \
--target-files src/simulation.hpp \
--runner \
--mode automatic \
--model
```
Use the same verified commands inline. Monitor with `discovery get` / `versions list` until the baseline is finalised and at least one version has measured `simulation_fps`.
**Checkpoint:** Discovery ran on runner-verified commands against your fixed harness; rank candidates by measured `simulation_fps`, not only fitness.
## What to expect
- Command-string iteration is cheap and does not change project code: reuse the empty changeset.
- Script or source fixes require push → `project pull` → a **new** empty changeset before re-validation.
- `changeset validate` reports exit codes and resources only; use `artemis process logs` for the Artemis results contract.
- Local success on your laptop is useful rehearsal, not proof the selected runner can run the same commands.
## Optional next steps
- [Steer a running discovery](./particle-life-steering-example.md) to redirect a live run and expand its budget.
- [Make a repository ready](./particle-life-harness-example.md) when the repository has no harness at all.
- Adapt the same runner verify → fix → pull loop to your own repository when local and runner environments differ.
---
## Steer a running discovery
## Goal
This example assumes you have completed [Get started with Particle Life](./particle-life-example.md). Your Particle Life project, runner, commands, model, and `simulation_fps` benchmark should already be ready.
You will let the agent explore unguided, steer it mid-run toward using every CPU core, let the budget finish, then add one more version and steer it to combine what it has found.
This is one example of what steering a Discovery run can look like. Since each run has some randomness you may see different behaviour, but this example shows all the elements you'll need to steer it as you see fit.
## 1. Start with ten versions
**Skill:** `discovery-start`
```bash
artemis discovery create \
--project \
--task "Maximize simulation_fps without changing simulation behavior or weakening the correctness tests." \
--versions 10 \
--compile-cmd "cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build --parallel" \
--test-cmd "ctest --test-dir build --output-on-failure" \
--benchmark-cmd "python3 tools/benchmark.py --no-visualize" \
--runner \
--mode automatic \
--model
```
Capture the returned ``. Wait for the baseline to finalise and at least one version to appear:
```bash
artemis discovery get
artemis discovery versions list
```
## 2. Redirect the search while it is active
**Skill:** `discovery-steer`
Steer around halfway, before the budget is exhausted:
```bash
artemis --output-format json discovery steer \
--message "You are leaving significant performance on the table. This benchmark runs on a multi-core machine and the simulation currently uses one core. Consider how to use all the available CPU cores. Preserve checksum determinism and all existing tests."
```
Successful output includes a resulting `agentRunId` and `verified: true`. Steering follows the child agent run created by the platform and repoints Discovery to it.
Check delivery and later behavior separately:
```bash
artemis --output-format json discovery get
artemis chat messages
artemis discovery experiments list
artemis discovery versions list
```
The child chat should contain the instruction. Subsequent experiments and diffs—not successful delivery alone—show whether the agent followed it. Work already in flight may still finish under the original direction.
## 3. Let the first budget finish
Wait until the run reaches a terminal state at ten versions, then inspect how the budget was spent:
```bash
artemis discovery get
artemis discovery versions list
artemis discovery metrics --stats --all
```
Individual versions may fail generation, compilation, testing, or scoring. Compare successful candidates by measured `simulation_fps`, and read their diffs to see which technique produced each result. Note which strong ideas appear in separate versions but never together—that is what step 4 acts on.
## 4. Add one version, then steer
The continue endpoint expands and restarts a finished run, but it cannot carry new guidance. Add budget first:
```bash
artemis discovery continue --versions 1
```
Refetch until the run is active with an `agentRunId`, then give the added budget its focus:
```bash
artemis discovery get
artemis --output-format json discovery steer \
--message "Your strongest results optimise different things and have never been combined. . These are independent and should compound. Use the additional budget to combine them rather than replace one with the other. Preserve checksum determinism and all existing tests."
```
Name the actual versions from your own run. A steer that cites measured results is far more likely to be followed than a generic instruction.
Do not reverse this order at the end of a run: first `continue` to create room for more versions, then `steer` to provide new guidance.
## What a steered run looks like

Unguided, the agent found a spatial grid at v1. The first steer produced thread-level parallelism at v6—but the agent dropped the grid to get it. The second steer said the two were independent and should compound: v11 combined them at 1,382 fps, 42× the baseline and more than three times either technique alone.
Both steers were acted on by the very next version. Neither was guaranteed to be—judge compliance from the diffs, not from `verified: true`.
## What to expect
- Steering cancels the parent agent turn and continues on a child run. After refreshing the Web UI, the parent may appear as **Interrupted**; this is expected.
- A steer changes direction but does not guarantee immediate compliance. Judge later experiments, versions, and diffs.
- The original ten-version budget becomes eleven after `continue --versions 1`; existing versions and metrics remain available.
- Discovery is stochastic. Your run may find different techniques, in a different order, or none that beat the baseline on your runner.
At the end, use `discovery-inspect` to account for every version, compare measured `simulation_fps` with the baseline, and read the best candidate's diff.
---
## Versions
A **Version** is the actual code diff an experiment produced. Each version is built, tested, and benchmarked on your runner, then **Scored** against your [Goals](./goals.md) — so you can compare it directly with the baseline and with other versions.
## The versions table
Switch between the **Data** table and the **Graphs** view. The table lists every version against the **baseline** reference, showing its **AI Score**, per-metric results (e.g. `XXH32_MBps`, `XXH64_MBps`) with their percent change vs. baseline, and lines added/removed. The strongest version is tagged **★ BEST**.

The left panel lists the **files each version changed** (here `cli/xxhsum.c`, `tests/cli-seed.sh`, and the `Makefile`). Per-version actions (**⋯ More actions**) include:
- **Create PR** — sends the version to the **Changesets** tab, where you review the diff and open the pull request. See [Changesets](../../features/changeset.md).
- **Download zip** — download the version's changes.
## Working with multiple versions
Select two or more versions to act on them together:

- **Run** — (re)run the scripts against the selected versions.
- **Combine** — merge the selected versions into a new one.
- **Download zip** — download them together.
When you find the version you want to keep, **Create PR** takes it to the [Changesets](../../features/changeset.md) tab, where you open the pull request to review and merge.
---
## Optimise Overview
Artemis provides a comprehensive system for improving your codebase across performance, quality, security, and any other metrics you define.
## Getting Started
Before running optimisations, set up your repository by completing these three steps:

- **Step 1 — [Set up a runner](../features/artemis-runner.md)**: Connect your local machine to the Artemis platform to execute code in your own environment.
- **Step 2 — Configure commands**: Define your compilation and unit-test commands in [Runner and Scripts](../project-setup/settings/runner-and-scripts.md), and your performance benchmark in [Benchmarks](../project-setup/settings/benchmarks.md), so Artemis can verify that improvements don't break existing logic.
- **Step 3 — [Find targets to optimise](code-targeting/overview.md)**: Identify the highest-impact areas of your codebase to focus on.
---
## Optimise Components
### [Code Targeting](code-targeting/overview.md)
Identify the most impactful areas of your codebase to optimise. Use file-level analysis, agent targeting, interactive chat, tool integrations, pull request analysis, and contributor analysis to narrow down where optimisation will have the greatest benefit.
### [Version Generation](version-generation/overview.md)
Automatically generate alternative implementations for your targets using LLM-based generation, agent-based optimisation, or Artemis Intelligence. Explore multiple options, compare trade-offs, and select promising candidates.
### [Code Validation](code-validation/code-validation-overview.md)
Verify that optimised versions meet your standards for quality, correctness, and performance. Run builds, tests, benchmarks, and quality checks to confirm improvements before integration.
### [Code Optimization](code-optimization/overview.md)
Combine the strongest versions, validate them iteratively, and generate detailed reports. This stage ensures the final integrated changes deliver proven, validated improvements.
---
## Want to Skip the Manual Steps?
**[Discover](discover/overview.md)** lets you skip code targeting, version generation, and validation as separate steps. Describe a goal and Artemis runs the full cycle autonomously - building Experiments, generating multi-file Versions, and carrying the best results forward.
---
## Agent-based Generation
Agent-based generation uses specialized AI agents to analyze, optimize, and generate improved versions of your code. This approach leverages multiple agents working together to provide comprehensive code optimization and improvement.
**When to use:** If you need **more refined and context-aware** versions. Slower and more expensive than LLM, but higher quality.
### Steps
- In the configuration panel, select `Agent` as your method.
- Define your prompt (predefined or custom).
- Select the LLM(s) you want to use.
- click `generate versions`.

**Result:** The Agent coordinates refinement across models and produces polished versions.
### Next step:
- You can [validate](../code-validation/code-validation-overview.md) your generated targets.
---
## Generation with Artemis Intelligence
Artemis Intelligence is the built-in AI system that provides intelligent code analysis, optimization, and generation capabilities. This system combines multiple AI techniques to deliver comprehensive code optimization and improvement.
**When to use:** For **advanced optimization**. Allows combining multiple models, leveraging logs by enabling internal runs to refine each generation, and supporting deeper exploration. Recommended for complex cases.
### Steps
- Select `Artemis Intelligence` as a generation method.
- Configure advanced options.
- Choose model(s).
- click `generate versions`.

When you pick **Artemis Intelligence**, a **Configuration** button appears — click it to open the **Advanced Settings**.


**Result:** Artemis generates multiple sophisticated alternatives with deep insights.
### Next step:
- You can [validate](../code-validation/code-validation-overview.md) your generated targets.
---
## Generation Steps
Before diving into the methods, here’s the general workflow:
### Step 1: Access the targets section
Make sure you are in the `Targets` section of your selected code project.
### Step 2: Generate versions
* To generate for a **specific target**, click the `plus icon` in the `Versions` column for that target.
* To generate for **all targets**, click the plus icon next to the `Versions` column header.

### Step 3: Configure generation options
The **Generate new version** dialog opens. Configure it in three parts:
* **Select mode** — choose how versions are generated:
* **LLM** — generate new versions using LLMs of your choice. Cheapest, fastest.
* **Agent** — advanced context awareness, one refined result per LLM. Moderate cost, fast.
* **Artemis Intelligence** — evolves multiple generations of code using a genetic algorithm. Best for critical problems; highest cost, slowest.
* **Prompt** — keep the default optimisation prompt or write your own (use **Add to Context** to include extra files).
* **Select Models** — pick one or more models to run. Each model's estimated **cost** is shown next to it.

### Step 4: Generate versions
Click `Generate Versions` to begin.
Artemis will use your chosen method and settings to produce alternative versions.
### Step 5: View targets
While the process is running, you can monitor progress in logs.
Once finished, the generated versions will appear next to each target.
### Advanced Tools
Artemis also provides extra features to refine your workflow:
* Improving generated versions:

* Extra functionalities for generated targets:

### Next Steps
After learning about generation steps:
- [Learn about generating with LLMs](./llms)
- [Learn about generating with agent](./agents)
- [Learn about generating with Artemis Intelligence](./artemis-intelligence)
---
## LLM-based Generation
LLM-based generation leverages Large Language Models to understand, analyze, and generate optimized versions of your code. This approach uses advanced AI capabilities to provide intelligent code optimization and improvement.
**When to use:** Quick iterations, cheapest and fastest option. Produces one-shot results.
### Steps
- In the configuration panel, select `LLM` as your method.
- Choose a predefined or custom prompt.
- Select one or more LLMs.
- Click `Generate Versions`.

**Result:** Alternative versions appear under the `Versions` tab.
### Next step:
- You can [validate](../code-validation/code-validation-overview.md) your generated targets.
---
## Version Generation Overview
Artemis provides automated tools for creating **alternative implementations** of your optimization targets.
By generating multiple versions with different AI-powered approaches, you can explore trade-offs, compare results, and refine your codebase with minimal manual effort.
Version generation is the **foundation** for later steps such as validation, review, and integration.
---
## Version Generation Components
### 1.[Generation steps](./generation-steps.md)
### 2.Generation Methods
Artemis offers three complementary generation methods:
* **[LLM-based Generation](./llms.md)**: Fast, cost-effective, one-shot improvements. Ideal for baselines and quick wins.
* **[Agent-based Generation](./agents.md)**: Iterative, context-aware refinement. Best for medium-complexity optimization tasks.
* **[Artemis Intelligence](./artemis-intelligence.md)**: Advanced multi-model optimization with internal runs and log-driven improvements. Best for complex or critical scenarios.
By choosing the right method, you can balance **speed**, **cost**, and **quality**.
## Next Steps
- [Validate your versions](../code-validation/code-validation-overview.md)
- [Make an optimization](../code-optimization/overview.md)
---
## Git Integration
Manage your git integrations from **Platform Settings → Integrations → Git**.

---
## GitHub App
The GitHub App lets Artemis create pull requests and sync repositories automatically.
- **Linked account** — Shows your connected GitHub account. Click **Unlink** to disconnect.
- **Installations** — Click **Add installation** to grant Artemis access to a GitHub organisation or personal account. Each installation appears under **Accounts** with a **Manage** link to adjust its permissions on GitHub.
---
## Access Keys
Access keys let you connect repositories using a personal access token or SSH key. Your saved keys are listed with their name and type.
Click **+ Add key** to open the key creation dialog.

### Supported key types
| Key type | Use case |
|---|---|
| **GitHub Personal Access Token** | GitHub repositories |
| **GitLab Personal Access Token** | GitLab repositories |
| **Azure DevOps Personal Access Token** | Azure DevOps repositories |
| **Bitbucket API Token** | Bitbucket repositories |
| **Bitbucket App Password** | Bitbucket repositories |
| **SSH Key** | Any git host |
### Adding a key
1. Select a **Key type** from the dropdown
2. Enter a **Name** — include context like permission scopes or usage (e.g. "Work PAT")
3. Paste your token into the **Token** field
4. Check **Self-hosted instance** if you are connecting to an enterprise or on-premises deployment
5. Click **Test connection** to verify, then **Save**
For GitHub PATs, use the **Generate a new token on GitHub** link to open GitHub's token creation page directly.
---
## Import your codebase
This page covers how to bring a code repository into Artemis.
## Getting started
Go to the **Projects** tab in the left panel. From here you have two entry points:

- **Import Project** — connect an existing Git repository or upload a code archive.
- **Plan with AI** — describe a project idea and let the agent generate a plan and implementation steps. Use this when starting from scratch rather than importing existing code.
---
## Importing an existing project
Click **Import Project** to open the import page.

There are three ways to import:
### Option 1: Import Git Repository (recommended)
Select or add an access key from the dropdown, then browse and select a repository from the list.
**To add a new access key:**
1. Click **`Add access key`** in the dropdown.
2. Choose the key type that matches your Git hosting service:
- **GitHub PAT** — Personal Access Token for GitHub repositories
- **Bitbucket App Password** — for Bitbucket repositories
- **SSH Key** — works with any Git service (GitHub, Bitbucket, GitLab, etc.)
3. Enter a name for the key, paste the token or private key, and click **Save**.
:::tip Need help generating tokens?
See [Using private code repositories](project-setup/git-keys.md) for step-by-step instructions for each key type.
:::
Once an access key is selected, your available repositories will appear in the list. Select the one you want and click **Import**.
### Option 2: Upload zip
Click **Upload zip** and select a `.zip` archive of your project from your machine.
:::note
Only `.zip` format is supported. Make sure your code is compressed before uploading.
:::
### Option 3: Sample projects
Click **Sample projects** to import a pre-built example repository. This is useful for trying out Artemis features before connecting your own code.
---
## Starting a new project with Plan with AI
Click **Plan with AI** from the Projects page to open the planning interface.

This creates a new project and launches the **Planning Agent**. Describe what you want to build — the agent gathers requirements, asks clarifying questions (such as tech stack preferences), and generates a structured plan with implementation steps.
You can choose a model, use a starter prompt, or switch to importing an existing repo from the same screen.
For more details on working with plans, see [Plan overview](../build/Plan/plan-overview.md).
---
## Next steps
After importing your codebase:
* **Optimize your code**: Go to the [Optimise section](optimization/overview.md) to identify targets and optimize them.
---
## Project Overview
The **Overview** tab is your project's home page — a single place to see everything happening across Artemis and jump straight into any part of it.
## Getting started
When you first open a project, the **Getting Started** panel offers six things to explore. Each card takes you to the relevant part of the platform, so you can get moving in one click.

| Card | Takes you to |
|---|---|
| **Uncover bug hotspots** — scan for logic & correctness bugs | [Maintain](/scan/overview) |
| **Find performance issues** — scan for the Inefficient Code Patterns rule | [Maintain](/scan/overview) |
| **Look for security vulnerabilities** — flag common security weaknesses | [Maintain](/scan/overview) |
| **Solve a complex problem with Discovery** — give Artemis a goal and let it run experiments | [Discover](/optimization/discover) |
| **Plan a complex task** — break down a big initiative into sequential tasks | [Build](/build/overview) |
| **Give Artemis a coding task** — try out the coding agent | [Build](/build/overview) |
The **0/6 Explored** counter tracks how many you've tried, and you can dismiss the panel with the **✕** once you're set up.
## Everything in one place
As you use the platform, the Overview fills in with live summaries — so you can reach all of your work at once, without hopping between tabs. Each panel has a **Show all →** to open the full section.

- **Issues** — every issue found by your [Maintain](/scan/overview) scans, grouped by severity (High / Medium) with an open-count summary.
- **Discovery Runs** — your [Discover](/optimization/discover) experiments and their status (for example, *Awaiting input*), with version counts.
- **Recent Build Agents** — your latest [Build](/build/overview) agent runs (Code, Plan, Chat), newest first.
## Runner & Scripts
The Overview also surfaces your project's execution setup at a glance — the runner and the commands Artemis uses.

- **Runner** — the connected runner and whether its worker is online.
- **Runner hardware specs** — CPU / RAM / GPU (shown once a worker connects).
- **Build / Test / Benchmark** — the commands Artemis runs (e.g. `mingw32-make -j`, `mingw32-make check`, `sh artemis_bench.sh`).
Click **Configure** to edit these in [Runner and Scripts](./settings/runner-and-scripts.md).
## Ask Artemis about this project
The chat panel on the right lets you ask questions about the whole project. Use the quick prompts — **Project overview**, **Explain the architecture**, **Where should I start?**, **Find performance opportunities** — or type your own (`@` to mention a file).
---
## Benchmarks
Configure how Artemis measures your code's performance from the **Settings → Benchmarks** tab. Benchmark results are what Artemis uses to compare versions and decide which changes are genuine improvements.
Artemis **automatically records runtime, CPU, and memory** for every benchmark run — you don't need to configure anything for those. **Custom metrics** (throughput, accuracy, error rate, inference time, …) are optional and let you track what matters most to *your* project.
---
## Preparing a benchmark
To add custom metrics, open the **Benchmarks** tab and click **Prepare benchmark** to launch the guided wizard. It walks you through five steps: decide what to measure, write a results file, check it parses, run the benchmark, and view your metrics.

1. **Prepare benchmark** — from the Benchmarks tab, start the wizard.
2. **Decide what to measure** — pick the numbers worth tracking (throughput, accuracy, error rate, …) and tick *I know which metrics to track*. Runtime, CPU, and memory are already covered for you.
3. **Write a results file** — make your benchmark write an `artemis_results.json` (or `.csv`) file to the project root just before it exits. The wizard gives you a ready-made prompt you can copy (📋) and hand to a coding agent; once your benchmark writes the file, tick *My benchmark writes artemis_results.json…*.
4. **Check the file parses** — paste a sample of your results file. Artemis runs the same checks it uses on real benchmark output and shows exactly how it will read it (e.g. *"Valid JSON — 1 measurement across 4 metrics"*). When it's valid, tick *My file passed validation*.
5. **Run benchmark & view your metrics** — run the benchmark; your custom metrics are registered and appear on the Benchmarks tab. Their **values populate** as Artemis benchmarks code versions during **Optimise** and **Discover** runs.
---
## The results file
Artemis reads a file named exactly **`artemis_results.json`** or **`artemis_results.csv`** from the **project root** (the working directory — not a subfolder), written by your benchmark right before it exits.
Rules Artemis enforces:
- The file must be named exactly `artemis_results.json` or `artemis_results.csv` and live in the project root.
- Every metric value must be a finite number (integer or float) — no strings, booleans, `null`, or nested objects.
- Use clear, consistent metric names across runs (e.g. `throughput`, `accuracy`, `error_rate`, `inference_ms`).
- **One measurement** → a single JSON object:
```json
{ "throughput": 4500, "error_rate": 0.02 }
```
- **Multiple measurements** → a JSON array of objects, or a CSV with a header row and one numeric row per measurement.
- If both a `.json` and a `.csv` exist, Artemis uses the JSON.
:::tip
If your benchmark runs from a subfolder, copy the results file back to the project root before it exits. See [Custom Metrics](../../features/custom-metrics.md) for the full schema and more examples.
:::
---
## Example: wrapping a benchmark that prints to the console
If your benchmark tool prints its numbers to the terminal instead of writing a file, wrap it in a small script that parses the output and writes `artemis_results.json`. Commit the wrapper to your repo and set it as the **Benchmark** command in [Runner and Scripts](./runner-and-scripts.md).
For example, a wrapper that runs a throughput benchmark and captures the reported MB/s figures produces a single-object results file like:
```json
{
"XXH32_MBps": 8926.2,
"XXH64_MBps": 17770.1,
"XXH3_64b_MBps": 59029.4,
"XXH128_MBps": 57612.7
}
```
On the next run, Artemis reads the file, registers each key as a custom metric, and starts tracking it across versions alongside the built-in runtime, CPU, and memory.
---
## Next Steps
- [Runner and Scripts](./runner-and-scripts.md) — connect a runner and define your build and test commands
- [Validate your new code versions](../../optimization/code-validation/code-validation-overview.md)
---
## General
Manage your project's general settings from the **Settings → General** tab. This is where you name the project, review its Git connection, and control which branch and commit new Artemis work is based on.

---
## Project details
| Field | Description |
|---|---|
| **Repository Name** | The name used to identify your repository on Artemis. |
| **Repository Description** | An optional description of the project. |
| **Owner** | The user who owns the project. |
---
## Git connection
These fields control how Artemis connects to and authenticates with your repository.
| Field | Description |
|---|---|
| **Git Repository** | The URL of the connected Git repository. Follow the link to open it in your Git provider. |
| **Git Key** | The credential used to authenticate Artemis with the repository. Generate a new key or switch to an existing one directly from this field. See [Using private code repositories](../git-keys.md) for setup instructions. |
---
## Branch and commit
Control the starting point for every new version Artemis creates.
| Field | Description |
|---|---|
| **Default Branch** | The branch Artemis works from. New code changes are forked from the **HEAD** of this branch. |
| **Default Commit** | The commit new Artemis branches are based on. By default all new branches use the **HEAD** of your default branch, unless you override it here by pinning a specific commit. |
---
## Ask Artemis about this project
The right-hand panel is a project-aware chat agent you can ask anything about your setup — no need to leave the settings page. It has full context of your project and its configuration.
Use the quick actions to jump straight into a common task:
- **Setup build commands** — get help configuring your compilation, test, and benchmark commands
- **Project overview** — a summary of how your project is currently set up
- **Troubleshoot build** — diagnose and fix build failures
- **Suggest improvements** — recommendations based on your project and runner
:::tip
Type `@` in the chat to mention a specific file and give the agent focused context.
:::
---
## Staying in sync with your repository
Artemis tracks your default branch against the remote. When the repository moves ahead and your project falls **one or more commits behind**, a **behind** indicator appears next to the branch selector in the top bar. Click it to pull the latest commits and bring your project up to date with the newest state of the repo.

---
## Next Steps
- [Runner and Scripts](./runner-and-scripts.md) — connect a runner and define your build and test commands
- [Benchmarks](./benchmarks.md) — measure performance and generate custom metrics
---
## Runner and Scripts
Configure the execution environment and the scripts Artemis uses to compile and verify your code from the **Settings → Runner and Scripts** tab.
---
## Select a runner
A runner is the machine that executes your build, test, and benchmark scripts. Select one from the **Runner** dropdown — the selected runner picks up all execution tasks for this project.
If you haven't connected a runner yet, set up the [Artemis Runner](../../features/artemis-runner.md) first, then return here to select it.
---
## Scripts
Define a script for each execution stage. Every script runs on the selected runner against each new version Artemis produces.
- **Build** — compiles your project and ensures the code is free from syntax errors and ready to run. The build runs first, before every test, so only valid code moves forward.
- **Test** — verifies correctness after each change. Make sure these tests cover the code Artemis is optimising — not just that the project compiles.

Each script can be edited, run manually with **Run** (or **Run all** for every stage), and after a run shows its status, runtime, and resource usage.
If a script fails, open **Logs** — on an individual stage, or **Logs** at the top for the full run — to see the complete output and pinpoint the problem. You can also ask the built-in agent to investigate and fix failures (see [Agent Assistant](#agent-assistant) below).
---
## Agent Assistant
The right-hand panel contains a built-in chat agent to help you configure and troubleshoot your scripts. It is hardware-aware — it knows your connected runner's CPU, memory, and platform — and has full context of the commands you've already set up.

You can ask it to:
- Set up build and test commands from scratch based on your repo
- Review and fix issues in your existing scripts
- Suggest improvements based on your runner's hardware
- Troubleshoot failures in any execution stage
---
## Next Steps
- [Benchmarks](./benchmarks.md) — measure performance and generate custom metrics
- [Validate your new code versions](../../optimization/code-validation/code-validation-overview.md)
---
## Version 1.10.0
## Here are our Release Notes for Artemis v.1.10.0
*Release date: 26 February 2025*
### :rocket: New features and functionalities
#### We have added the capability to add and delete files in the Artemis Agent
The Artemis agent is now able to add/delete files, enabling users to create unit tests and benchmarking tests.
- During the planning phase of the agent, the user can specify add/delete operations which can prompt the agent to approach a problem in a specific way.
- Once the agent changes are saved, users can commit these file level changes to the remote git repository, the same way they would be able to with regular edits.
#### Artemis agent can now save history
Artemis platform now stores a history of all agent tasks, enabling users to view and run tasks from past agent runs. Click on the History tab under Pair Coder Agents to view the history of tasks.
See the image below:

#### Custom runner support for Windows
Artemis has a custom runner feature to enable code validation. We now provide support for the custom runner on Windows. See documentation on the custom runner here: [Custom runner](../features/artemis-runner.md)
#### Content tagging system
In the code snippets page, we provide tags for code snippets for better categorisation. We have improved our content tagging system to provide more meaningful tags.
### :chart_with_upwards_trend: Improvements
#### Improved Artemis Intelligence
Artemis Intelligence has been improved to generate more reliable output as well as draw better from project context. We have also made it easier to setup custom commands.
### :sauropod: Deprecated
#### The default runner functionality is now deprecated
Earlier we had a default runner on Artemis for code validation. We have deprecated the default runner. You are now required to set up a custom runner to validate your code, as detailed here: [Custom runner](features/artemis-runner.md)
### :beetle: Bug fixes and usability
We added support for the following languages
`.drl`, `.m` (Matlab), `.vba` (Visual Basic), `.jl` (Julia), `.R` (R)
#### We have added the following models
- Claude 3.7 + thinking
- Deepseek R1
- o1/o1-mini
- o3/o3-mini
- Gemini 2.0 Flash
#### We made several fixes across the platform
We've made several changes across the platform to improve stability and usability.
---
## Version 1.11.0
## Here are our Release Notes for Artemis v.1.11.0
*Release date: 9 May 2025*
### :rocket: New features and functionalities
#### File Upload Capabilities
Users can now upload individual files to an Artemis project.
#### Csv File Support
Csv files can be indexed, providing Artemis Intelligence with better abilities to infer useful information from data within the project.
#### New LLM Support
- GPT-4.1 Suite: Added support for the new GPT-4.1 family, including GPT-4.1, GPT-4.1 Mini, and GPT-4.1 Nano
- Gemini 2.5 Pro: Added support for Google's Gemini 2.5 Pro (upgraded from experimental to preview status)
### :chart_with_upwards_trend: Improvements
#### Better Project Flow
The project flow has been updated. Now Artemis steps you through project creation, and provides more support for connecting to private git repositories. Users can now test their git connection and add new credentials in the wizard.

#### Overhauled Comparison Scoring
Comparison scores are rescaled to be more explictly relative, such that positive scores indicate improvements, and negative scores indicate regressions.

#### Miscellaneous UI/UX Improvements
- New code analysis option to create code snippets via agent
- Ability to jump directly from a bad score to “create version to fix the score”
- Improved code comparison view, code diffs are now correctly aligned
- Projects filtered by user by default
- Ability to globally disable embedding models
- Users can have a default git key
- Better logging for the agent
- Improved settings dialog for LLM tasks
- Progress bar and spinner added to code snippets page while code analysis is running
- Improved side panel for file filtering
- Improved default view for optimisations
- Better dialog for creating code recommendations
### :sauropod: Deprecated
- Removed support for Gemini 2 Pro
### :beetle: Bug fixes and usability
- Resolved issue with certain extracted code ranges being inaccurate
- Resolved issues with code deletion for large batches
- Custom runner compatibility across MacOS, Windows and Linux
---
## Version 1.4.0
## Here are our Release Notes for Artemis v.1.4.0:
### :rocket: New features and functionalities
#### We've added new LLMs
Artemis includes a range of LLMs for code analysis and code optimisations tasks. We have added the following to our current list of LLMs:
- GPT-4o mini
- Neural Chat
- Mistral Large 2
- Llama 3.1
#### We've added reranker models
Reranker models can be used to create embeddings of codebases and supplementary material, so that relevant information can be easily retrieved when we ask questions about a codebase. We have added the following reranker models to our platform:
- Cohere
- MixedBread
- Jina-AI
### :chart_with_upwards_trend: Improvements
#### We enabled better document processing for RAG
We use RAG-based approaches to query code and documents. We have improved the splitting methods of our documents, so that you will have better results when you query code and documents on Artemis.
#### We made GPT-4o mini the default LLM of Artemis
We replaced GPT 3.5-turbo with GPT-4o mini as the Artemis default model. As a result you will experience better performance and reduced cost.
#### We improved our LLM token-tracking
Artemis provides metrics to users to track and manage their LLM usage. This is done via monitoring the amount of LLM tokens utilised during code analysis and optimisation tasks. Previously, we used an umbrella tokeniser for all LLMs to calculate the number of tokens. In this version of Artemis, we implemented LLM-specific tokenisers, so that you can have a more refined understanding of your LLM usage.
#### We implemented a code specific search functionality
Artemis includes an `ARTEMIS CHAT` feature, similar to the likes of ChatGPT, where you can ask questions and search your own codebase. We upgraded this feature to provide a more specific `CODE SEARCH` functionality. This functionality better retrieves information from codebases via more targeted search techniques.
#### We updated Artemis chat so that you can have your own knowledge repository within Artemis
`ARTEMIS CHAT` is available at two levels: (1) within each code project; and (2) at platform level. We updated the platform-level chat in such a way that when you use the chat, all codebases and projects attributed to your user profile will be used to provide you answers. This is similar to having your own knowledge repository embedded within Artemis!
#### We enhanced our file search filters
When you upload your code project to Artemis, you can choose which files of your codebase you want analysed. We improved this functionality to filter files better.
### :wrench: Bug fixes
#### We fixed an issue with running embeddings
Some of you told us how you had to run a code analysis before creating embeddings for a code project. We heard you – this won't be a problem anymore!
#### We made it easier for you to access validation logs
You told us that you could not see sufficient information about the status of your code version validations. We realised how that can make things difficult for you - now you can access individual validation logs for each code version and each type of validation.
#### We fixed a problem with selecting the language of your codebase
We heard from you that there were issues selecting the code languages from our drop-down list of languages - this is fixed now.
#### We've improved the stability of our embedding tasks
We use embeddings to power the Artemis chat feature. We improved our approaches to embeddings so that the embeddings tasks can be more stable and performant.
#### We made our LLM outputs better
Artemis uses LLM outputs across a range of its features and functionalities. We improved the way we parse LLM outputs, so that you receive better results from LLMs.
### :sauropod: Deprecated
#### We removed some LLMs
We removed Llama 3 70b and Mistral Large from the list of Artemis LLMs – only to replace them with more performant models! (The new LLMs we added are at the top of this page.)
### :rotating_light: Security updates
#### We've improved underlying libraries
We updated Artemis libraries and deployment bundles so that they are more compact and are up-to-date with latest industry standards.
---
## Version 1.6.1
## Here are our Release Notes for Artemis v.1.6.1:
### :rocket: New features and functionalities
#### We've added Artemis Intelligence
We've created Artemis Intelligence for genetic code optimisation at snippet-level. For those of you who know our work, we pioneer the use of genetic algorithms at codebase level to ensure that code optimisations are applied cohesively across an entire codebase. Now we have brought this to code snippets, where each code snippet can be generated using genetic algorithms.
#### Save your chat history
We have updated the Artemis chat, enabling you to view and revisit any of your previous conversations.
So the next time you ask Artemis which parts of your codebase are most inefficient, you can rest assured knowing you can find this information three months later!
##### Context-aware chat functionality at snippet level
Now, for each code version, you can chat with Artemis regarding the changes that were made on the snippet, where Artemis will make context-aware chat suggestions.
#### File explorer, now supplemented by a chat at code file level
We have introduced Artemis chat in the file explorer tab of the platform, so you can use the chat functionality to easily find out information about your code files.
#### A more detailed summary of your optimisations
On the Optimisations page, you will now see more details regarding each optimisation, including the best solution and its performance metrics. This enables you to have a more detailed overview of the progress of your optimisations.
#### You can create a code snippet from an entire file
If you want to run an entire code file through an LLM to generate versions, you can now do this easily as we have made it possible for you to create a code snippet on Artemis with an entire code file.
#### Select/deselect LLMs at platform level
Artemis gives you access to a range of LLMs. We have now made it possible for you to select/deselect LLMs at platform level. For instance, if you find that you are always only using three LLMs within Artemis, then you can enable only these three LLMs.
#### More information on users and usage
We've added new options across our platform to provide more information on owners of code projects, and usage metrics of LLMs. This includes additional information provided to system administrators on LLM usage across different users.
### :chart_with_upwards_trend: Improvements
#### We've increased the default population size and generation size for optimisations
Our code optimisations go through a mutation process, which considers two parameters, generation size (the number of total iterations) and population size (the number of candidate solutions per iteration). We have increased the size of these parameters, so that more code variants will be generated and evaluated during the optimisation process.
#### We introduced a new pagination system
You will notice significant performance improvements in the way code snippets are loaded on Artemis, especially if you have large codebases.
#### Replacing the top navigation bar with buttons
You might have noticed how the top navigation bar and the bottom left sidebar of the platform, containing options such as Projects, Optimisations, Settings are no longer available. This is not a bug! You can find the same options that were available on the navigation bar and sidebar, on the top right of the platform. We thought this would make your interactions with the platform smoother. But if you don't like these changes, let us know - we are keen to hear your thoughts!
#### Download reports as PDF or Markdown
We've enabled the ability to download reports on optimisations as PDF or Markdown (previously it was only PDFs). This enables you to easily extract information from a report and include in a README.md or other in-repo documentation
#### Logs across various features and functionalities
We now provide additional logs and warnings to users across various points of the platform, so that users can be more aware of the progress of their code optimisation projects.
### :beetle: Bug fixes
#### Implemented a fix for a bug where LLMs were removing comments from codebases
A few of you told us how sometimes the code versions you received had useful comments removed. We have implemented a fix for this, where you can now compare your code snippets and re-insert comments where you think they are useful.
#### Fixed an issue with validations and optimisations taking memory and time
We noticed how certain codes suggestions can take a long time to validate, due to the nature of the suggestions provided by LLMs. We have fixed this so that code snippets taking longer to validate will automatically terminate after a pre-determined threshold of RAM consumption.
#### Multiple fixes to improve platform stability and performance
We've implemented fixes across the platform so that you can experience better performance when using Artemis.
### :ship: Deployment
#### OpenShift compatibility
For those of you who would like on-premise deployments of Artemis, we have enabled OpenShift compatibility.
### :sauropod: Deprecated
#### Removed the Code Repair feature
Previous versions of Artemis included a Code Repair feature, where Artemis aimed to target and fix broken code in a reiterative process. We have deprecated this - but there's a more exciting replacement brewing on the horizon.
---
## Version 1.8.3
## Here are our Release Notes for Artemis v.1.8.3
_Release date: 16 December 2024_
### :rocket: New features and functionalities
#### We have added LLM-based filtering to Code Analysis
Code Analysis section of Artemis enables you to scan your codebase and extract targeted code snippets for further improvement. We have added an LLM-based filter here, where you can now use natural language queries to extract snippets easily. See additional documentation here: [Code Targeting](optimization/code-targeting/overview.md).
#### We added a status bar to give a quick overview of background tasks
We have added a status bar to the platform, so that you can have a quick overview of any tasks that are running in the background. Here is a quick overview:

#### Connecting with Bitbucket
We added support for Bitbucket integration, so Bitbucket users can now authenticate natively with App Passwords.
On Artemis, go to `Settings` :arrow_right: `Git Keys` :arrow_right: `New Key` to access the option to create a Bitbucket App password.
#### Added further functionality to Pair Coder
We added live logs and task cancellation to Pair Coder, while making it easier to navigate through the steps of the workflow.
#### We added the ability for users to push changes directly to a Git repo
For code versions and optimisations, you are able to push changes directly to a Git repo, to the same branch, where previously, Artemis made a new branch to push the changes.
#### We have added the Vertex V5 embedding model to Artemis
We added Vertex V5 to the list of embedding models. Vertex V5 provides improved performance compared to V4.
### :chart_with_upwards_trend: Improvements
#### We made it easier for you to integrate with Git
- Now you can provide any type of Git Key, regardless of the protocol of the Git URL.
- We included key deletion confirmation and commit pushing, which will make things smoother as you integrate Git to Artemis for private code repositories.
#### Improvements to make the platform more performant and responsive
We have made multiple changes to make the platform more performant and responsive. Generating project embeddings and retrieving files during code analysis have particularly improved as a result.
### :beetle: Bug fixes
#### We fixed an issue with enabling/disabling code versions affecting costs
There was an error in how LLM costs were calculated when enabling/disabling code versions. We fixed this so that cost estimates are more accurate.
#### Platform-wide stability improvements
We have made multiple minor fixes across the platform, especially with data encoding, which makes the platform much more stable.
### :rotating_light: Security
#### Various security improvements
We have made various security improvements across the platform. These improvements also make connecting to LLMs via Artemis much more secure.
---
## Version 1.9.2
## Here are our Release Notes for Artemis v.1.9.2
*Release date: 22 January 2025*
### :rocket: New features and functionalities
#### We made it easier to access Artemis chat
Artemis provides a chat functionality for you to chat with your codebases and other files. You can now access this chat functionality from anywhere on that platform, from the top navigation bar.
See the image below:

#### We added the option for you to extract code snippets from any file type
On Artemis, you can use code files uploaded to the platform to extract code snippets. Previously, this functionality was limited to specific file types. Now you are able to extract snippets from any file type.
#### We added capabilities to make Artemis faster and more scalable
We have integrated the [Ray framework](https://docs.ray.io/en/latest/index.html) into our architecture to further parallelise improved code snippet generation. This makes using Artemis faster and more scalable.
#### We added text wrapping in the code editor for better readability
Artemis provides code editors across the platform. We have enabled text-wrapping here for greater readability.
#### We added support for multiple AI models and embedding services
We have added support to the following LLMs and embedding models:
- Qwen-2.5-coder-32b
- OpenAI Ada embedding preset
- DeepSeek v3 model
- AWS Bedrock Titan embeddings
- Vertex AI Llama 3.2 90B model
### :chart_with_upwards_trend: Improvements
#### We have made report generation asynchronous
Artemis provides the option for users to generate a report based on their optimisation. Previously, this functionality required the user to stay on the report generation page, and the report was downloaded to the local device by default.
We have now improved the usability aspects of this functionality, where users are able to revisit the optimisations page to view or download a report when preferred.
#### We improved the process to validate your code on Artemis
With Artemis, you can compile the generated code snippets and run unit tests and benchmark tests to validate LLM output. We have improved this process of validating your code. See detailed documentation here: [Artemis runner documentation](../features/artemis-runner.md).
#### We refined the Artemis Intelligence feature
Artemis includes an Artemis Intelligence component which conducts genetic code optimisation at code snippet level. We have improved the customisation options available here, so that you are able to have further control on the type of optimisation you generate.
#### We have improved the optimisations page
We have made design changes to the optimisations page for a new look and feel. These changes also make the page easier to use. See an overview of the page below:

### :sauropod: Deprecated
#### We changed the way Artemis calculates the importance of a code snippet in a codebase
Once Artemis generates alternative code snippets, it applies different snippets to the entire code project to identify the most optimal changes at codebase level. Artemis provides metrics to evaluate the impact of each snippet on the entire codebase along three metrics, runtime, CPU, and memory. We use machine learning approaches to calculate these metrics, and previously used a combination of tree-based and linear approaches. We have removed the tree-based approaches to calculating the metrics, as they were less reliable in providing accurate metrics for a small number of code changes.
### :beetle: Bug fixes and usability
#### We made several fixes across the platform
We've made several changes across the platform to improve stability and user experience. This also includes refactoring to improve the performance of our on-premise deployments.
### :rotating_light: Security
#### We made Artemis further secure to use within corporate proxies
We added SSL certificate handling support for Git repositories. This furthers our attempts to make Artemis secure to use within corporate proxies.
---
## Version 2.0
## Here are our Release Notes for Artemis v.2.0
*Release date: October 2025*
### :rocket: New features and functionalities
#### Plans & Planning Agent
Brainstorm and plan with our new codebase-aware planning agent that will ask intelligent questions, extract unwritten requirements and recommend best technologies. The agent then creates a step-by-step plan with seamless integration with the Artemis Coding agent, or you can copy prompts into your coding agent of choice (Cursor, Claude Code, etc.).
- Changes go into changesets (branches) which flow into our AI-first code review interface
- Pull requests can be automatically opened and tracked
- The agent will also open tasks that require human intervention such as adding secrets and API keys
- Several out-of-the-box example plans that are proven to work well on most codebases
#### Scanning & Rules
Set coding rules and standards for agents to check for, and run these across your whole codebase (or a subset of files) to find issues.
- Issues are ranked by importance and ease of fix, utilizing our experience with scoring to make it much easier to use
- Group many issues and start a Plan to fix them
- Use our new multi-plan agent to inspect the entire list of issues and recommend multiple possible plans [experimental!]
#### Artemis GitHub App
New project creation is now streamlined - connect seamlessly to GitHub to select your repositories instead of difficult personal access token workflows.
- No more manually entering access tokens
- No token expiry issues
- No need to check you entered the right permissions or selected the right namespace
#### Artemis Navigator: Cursor & Visual Studio Code Extension
**COMING SOON**
### :chart_with_upwards_trend: Improvements
#### UX Overhaul
- Optimization pages are now grouped under the **Optimise** heading in the UI - this includes Targets, Changesets, Optimisations, Files and Tasks
- **Snippets** has been renamed to **Targets**
- **Code Analysis** is now called **Code Targeting** to reduce confusion
- Users now enter Artemis on the **Build** tab where they can quickly get value before diving deeper into the more complex Optimisation flow
- Chat/Agents/Plan are now consolidated into a single place - the Build tab
#### New Models
- Anthropic Sonnet 4.5
- GPT-5-Codex (imminent - likely tomorrow/Friday)
#### Miscellaneous Improvements
- **Continue from pull request**: You can now continue working on an existing changeset after you publish the pull request. Get feedback from your colleagues and have Artemis fix the issues!
- Changeset agent now supports "Ask" mode
- Expired git tokens are now clearly visible
- Many security fixes - API endpoints now with additional security checks
- Various agent and changeset fixes
---
## Version 2.1
## Here are our Release Notes for Artemis v2.1
*Release date: December 1, 2025*
### 🧭 Planning & Coding
- **Build Plan**: the coding agent now actions every task in a plan, one by one, through the entire plan automatically
- Plans now support a task hierarchy, with related tasks grouped into **Phases**
- Redesigned Plan UI
- Revamped task statuses
- **Automatic PR opening** — enable from Project Settings → Project → Auto Pull Request
- **Automatic validation on code changes** — enable from Project Settings → Build → Agent Validation
### 🤖 Model Selection Overhaul
- New **Auto** mode automatically selects the best model for the task
- Handpicked secondary and tertiary models, each with a description, to choose from
- Removed duplicate models across multiple providers for a cleaner selection list
### 🔗 New Git Connections
- Revamped GitHub App connection flow
- Redesigned Git settings page
- Added support for **Azure DevOps** via access token
- Added support for **GitLab** via access token
### 🧠 New Models
- Google Gemini 3
- OpenAI GPT-5.1, GPT-5.1 Codex
- Anthropic Claude 4.5 Opus, Sonnet, and Haiku
### 🚦 Waitlist & Preview Users
- New waitlist flow with approval codes and referral codes
- Optimisation functionality is now part of the Enterprise tier
### 🎯 Optimisation Integration
- Add optimisation targets directly from scanning issues
- **Ask** mode can now recommend targets, tasks, and quests
---
## Version 2.5.1
## Here are our Release Notes for Artemis v2.5.1
*Release date: March 26, 2026*
### 🤖 New Agents & Skills
- **Code Split Agent**: splits code across files, available from both the CLI and a new split version view in the UI
- **Auto-Target Generation Agent**: automatically generates optimisation targets using intent decomposition and multi-dimension coverage
- **Build Command Generation Skill**: integrated into the coding agent and project chat, with support for incremental build strategies for CMake and Rust projects
### 📊 Custom Metrics System
A full observability metrics system across the platform:
- Baseline and per-observation metrics with improvement percentages
- Bulk metric creation with real-time notifications
- Support for file-level and project-level metrics
- Paginated search and stats for optimisation and solution metrics
### 🔗 GitHub Integration
- **CI Fix Agent**: trigger fix-agent runs directly from failed CI check runs
### 🧠 Coding Agent Improvements
- Reworked spec coder with better code context and improved prompts
- Changeset coder now includes an automatic summarisation step
- PR descriptions now include richer context and skip unnecessary LLM calls where possible
### 🆕 New Models
- GPT-5.4 Mini and Nano
### 💬 Agent Sidebar & Chat
- Model picker, cancel button, and retry/continue controls in the agent sidebar
- Improved markdown rendering: tables, math expressions, code blocks with headers, and syntax highlighting
- Fixed duplicate message issues
### ⚙️ Settings
- New settings pages: Models, CLI, Waitlist, Discord verification, and Model preferences
- Improved runner quickstart guide
### 🧭 Project & Navigation
- Decluttered top menu and footer status bar
- New project metrics and project samples pages
- Breadcrumbs now truncate long titles and repo names
---
## Version 2.6.0
## Here are our Release Notes for Artemis v2.6.0
*Release date: April 27, 2026*
### 🔬 Discovery (New)
A new evolutionary optimisation engine that iterates on your code autonomously. Discovery proposes ideas, runs experiments, measures results against a baseline, and evolves the best versions — generation after generation.
- **Graph view** — visual DAG showing the full Objective → Idea → Experiment → Version lineage
- **Board view** — kanban-style columns for Ideas, Experiments, and Versions with inline filters, sorting, and detail modals
- **Manual & automatic modes** — let Discovery run hands-free or approve each step yourself
- **Metrics-driven fitness** — define goals (maximise / minimise) and importance per metric; scores displayed as "AI score" across the UI
- **Baseline scoring** — the original code is scored first so every version is measured as a delta
- **Chat-driven** — start a run with a freeform prompt; reply mid-run to steer direction
- **Starter prompts** — six research-loop templates covering performance, ML accuracy, agent cost, bug triage, CI time, and more
- **MCP tool support** — your custom MCP tools are available inside Discovery runs
- Feature-flagged — enable via Settings → Feature Flags (off by default)
### 🤖 New LLM Models
- **Claude Opus 4.7** — available on Anthropic, Vertex, Bedrock, and Azure with adaptive thinking
- **Claude Opus 4.6 / Sonnet 4.6** — context window bumped from 200K to 1M tokens
- **Anthropic structured output** — native JSON schema support for Anthropic models
- **GPT-5.5** — support added
- **GPT-5.4** — improved parameter handling (temperature, top_p)
### 🧠 Agent Improvements
- **Unified agent architecture** — the GA and Quest Coder agents now run on the same infrastructure with shared streaming, lifecycle management, and prompt engineering
- **Per-task connection pools** — each task creates and tears down its own database pool, eliminating stale-connection states that previously required worker restarts
- **MCP configuration** — encrypted per-user MCP server config stored in user settings, with SSL skip option
- Rule scanning now supports a configurable issue count
- Improved truncation and scoring for large files in both GA and snippet chat
### 💬 Agents Page (React)
- New full-page agents experience with chat list sidebar and nested chat view
- Filter by type: Chat, Snippet Chat, Target Creator, GA ("Artemis Intelligence")
- Start a new Chat, Plan, or Code session directly from the page
- Markdown rendering with tables, timestamps, and tool-call display
### 🎯 Targets & Construct Window
- **Board view** — card-based layout with file-tree sidebar, validation badges, scoring spinners, and an Actions menu; switch between Table and Board via the toolbar
- **Revamped construct window** — single top bar with Code / Details tabs, Unified / Split / Original view dropdown, version navigation (prev/next), and integrated Create PR / Create Changeset actions
- **Deprecated filter** — filter targets by deprecated status
- **Virtual diff viewer** — fast, scrollable diff with text wrapping and Firefox support
### 🏗️ Platform & Infrastructure
- Build tab can now be toggled per-tenant via feature flag (default on)
- Switching project tabs no longer resets the activity panel or chat state
- Unified header with route-aware breadcrumbs across the app
- Improved backend resource management with async Redis and connection limits
- New scheduled repository sync endpoint
- Changesets are now created in the background for better responsiveness
### 🔒 Security
- SSL verification and proxy support for backend service clients
- Discovery access control — users are verified before accessing runs, ideas, and experiments
- Webhook signature verification toggle for the GitHub Connector
### 🐛 Notable Bug Fixes
- **Discovery stability** — fixed infinite loops when the final generation produces zero versions or the agent offers unapproved actions; fixed zero-baseline metrics producing extreme fitness values; failed runs now show consistently across all views
- **Discovery chat** — fixed user messages being silently dropped on reply, streaming stopping after approval, and the generation counter overshooting
- **LLM compatibility** — orphaned tool calls from interrupted turns are now cleaned up before every request, preventing errors; softened prompt phrasing to avoid triggering content filters
- **LogViewer timestamps** — fixed minutes displaying as the month number
- **Targets** — fixed a stuck loading spinner and Firefox diff rendering
- **Construct window** — fixed LLM score display, branch switching, and diff call duplication
- **Changesets** — duplicate names are now auto-suffixed; orphaned branches are rolled back on failure
---
## Version 2.6.2
## Here are our Release Notes for Artemis v2.6.2
*Release date: May 25, 2026*
Following the initial launch of Discovery in v2.6.0, this release focuses on stability and usability improvements across manual and automatic modes, plus a round of Targets and platform polish.
### 🔬 Discovery — Hardening & UX Polish
- Fixed **"Generate More Versions"** dead-ending a completed run with 0 versions; resume actions (Generate More Versions, Continue, Retry) now behave consistently
- **Manual mode** now correctly respects rejected experiments — the agent no longer creates versions for an experiment you've explicitly rejected
- Fixed a changeset count mismatch — exactly N changesets are now created for N versions
- Fixed the generation counter so it no longer overshoots (e.g. showing "4/3")
- Versions now execute in parallel for faster runs
- Prompt caching wired up across the agent loop to reduce LLM costs
- Validation timeouts now properly cancel the underlying worker process
- Changeset names no longer include the generation number — version number only
### 🎨 Discovery UI
- Chat moved into a proper sidebar within the Discovery popup, with categories and worker logs
- Table headers now stick on scroll
- Ideas, Experiments, and Versions tables redesigned with more sorting options
- Trend graph now plots progression **over version** instead of over time, for a clearer view
- Graph layout is now preserved when navigating away and back
- Version, Idea, and Experiment detail views are now full pages instead of modals
- You can edit the runner and commands inline from the Run popup
- Metric values now update live as versions are scored
- Added a search bar for metric selection
- Cancel button now available for pending runs, not just running ones
- Activity sidebar shows clearer run states: pinned baseline run, grey dot for cancelled runs, and "Awaiting approval" when the agent is paused
### 🎯 Targets
- New onboarding flow shown when no targets exist yet
- Tree view introduced and enabled by default
- Switch between List and Table views, with the choice reflected in the URL so it can be shared
- Filters (including new tag and deprecated filters) can now be shared via URL
- Reduced header footprint for a more compact view
- Construct window now opens inline within Targets
- Validation Status filter is now functional on the new table
### 🏗️ Platform & Infrastructure
- Changeset creation moved to a background task for better responsiveness
- Project downloads now use sparse git clones for faster, lighter operations
- Version diffs now show additions/deletions counts and full original content
- Improved backend resource management (async Redis, connection pool limits)
- Duplicate changeset names are now auto-suffixed, and orphaned branches are rolled back on failure
### 🤖 LLM Models
- Fixed adaptive thinking support for Claude Opus 4.7
- Fixed OpenAI completions routing and cache-control handling
### 🗑️ vscode-gateway — Discontinued
The VS Code extension (vscode-gateway) has been removed from the platform due to minimal usage and will no longer be supported.
### 🐛 Notable Bug Fixes
- Discovery: "Generate More Versions" producing 0 versions on completed runs; rejected experiments being planned anyway; changeset orphan count mismatch; generation counter overshooting; empty-diff versions being scored incorrectly
- Discovery manual mode: chat going blank after replying mid-run; ideas getting stuck after being un-rejected; a first-load race condition
- Discovery metrics: zero-baseline metrics dominating fitness scores; worker metric names being unexpectedly renamed
- Targets: filter counter bug; status indicator race condition; layout fixes
- Construct window: cancel fix; branch switching; scroll issues
- Changesets: duplicate name auto-suffixing; orphaned branch rollback on failure
- LogViewer: timestamps showing month instead of minutes
---
## Version 3.0.0
*Release date: July 22nd, 2026*
Version 3.0.0 is a significant milestone for Artemis — introducing **Maintain** as a first-class module for automated codebase auditing and fixing, a ground-up rebuild of **Discovery**, and a wave of platform-wide improvements across agents, memory, models, and navigation.
---
## Maintain
Maintain gives you a structured workflow for keeping your codebase clean: define rules, scan for issues, triage findings, and fix them directly with an Artemis coding agent.
### Rules
Create, import, and manage the rules that govern your codebase:
- **Create a rule** with agent assistance, or write one directly in Markdown format
- **Import rules** from another project or from Artemis's built-in out-of-the-box library
- Newly created projects come pre-seeded with three rules: *Logic and Correctness Bugs*, *Inefficient Code Patterns*, and *Dead and Unreachable Code*
- Import existing rules from a `claude.md` configuration file
- Out-of-the-box rules now support tags for easier filtering
- Improved scanning flow with a clearer, easier-to-read rule summary

### Scan
Run targeted scans against your codebase using one or more rules:
- Select **up to 20 rules** per scan
- Provide additional context when scanning — specify where in the code to look or which data sources to depend on
- Set a **budget** for how many issues to find (0 = unlimited)
- Choose the main model for the scan; a cost-efficient sub-agent handles deeper analysis automatically
- View live **scan logs** that show which rules are being applied, the prompt used, files scanned, and a final summary of issues found
- Scans support **MCP tools** if you have integrations configured
- Mention rules and issues directly in chat by their ID using `#Rules` and `#Issues`

### Triage & Fix Issues
Review and act on scan results:
- **Fix** any issue directly from the issue board — no need to change status first; select a model and the agent handles the rest
- Start a chat pre-filled from "Explain issue" for deeper investigation
- Chat now shows the full scan pipeline via issue-summary cards, a scan-start card, and a final results card
- Complex issues can be handed off to **Discovery** or a **Build plan** — Discovery is suggested automatically when the issue warrants deeper exploration

---
## Discovery
Discovery has been rebuilt from the ground up.
### Agentic Improvements
- **Ideas and experiments unified** into a single workflow — less switching, more doing
- Experiments now have **lifecycle statuses** so you always know where each one stands
- **Generate multiple experiment versions simultaneously** for faster exploration
- **Multi-LLM review panel** — select multiple LLMs to review suggestions generated by another model, with confidence ratings and critique notes

- **Multi-metric tradeoff plot** — compare generated variants against the baseline across multiple metrics at once

- **Pin optimisation goals** and configure metric weights
- Specify optimisation focus (e.g. maximise throughput)
- Improved agent budget utilisation
- Cancel and resume are now much more reliable
### UI
- The **Discovery board is now the default view**
- Inline Queue/Dismiss actions
- Bulk select and combine experiments
- Experiment placeholders persist when navigating away
---
## Agents
- Proper **streaming directly from the LLM** — noticeably faster for long outputs
- **Global checkpoint resume** — if any agent fails, it recovers from the last good state automatically
- **Multi-tab chat window** with a tabbed composer and collapsible sidebar
- Clearer error handling — a dedicated alert for detected loops, and errors shown by type with an expandable details panel
- Prompt suggestions on empty chats, plus stop and retry controls in read-only chats
- If a run's model is no longer available, you're prompted to pick a replacement on retry
---
## Memory
- **Memories page** — browse your Discovery experiments across all projects, with search and built-in chat
- **Contexts page** — manage what agents remember, with availability controls and a token-budget bar
- Modify agent memories directly from platform settings
- Three availability modes per context item:
- **Always** — the agent always has access to this context
- **On Demand** — the agent decides when to read it
- **Off** — the agent ignores it entirely
- Affected agents: `changeset_coder`, `chat`, `discovery`, `maintain`, `planning`, `quest_coder`, `scan`
---
## Changesets & PRs
- Changeset and PR actions are disabled when nothing has changed, with a clearer empty state for same-version diffs
- New **auto-generate PR title and description** button
---
## Models & Profiles
- The model picker shows **cost per 1M tokens** and warns when a model needs cost configuration
- Pick models by **effort tier** (Low / Medium / High) instead of memorising model names
- **Per-run cost and budget caps**
- Shared model picker used consistently across the app
- Per-profile **SSL verification**, including a custom CA certificate option
- Support for managing AI providers: OpenAI, Anthropic, Vertex AI, Azure OpenAI, OpenRouter, and custom endpoints
- Import provider model catalogues and validate configured models

---
## Settings & Onboarding
- Redesigned **project settings**, reorganised into General and Scripts & Benchmarks tabs
- "Get Started" checklists and attention dots highlight essential setup steps
- Guided runner setup flow
- New admin-only **platform logs page** with live log tailing
---
## Navigation
- Unified **project breadcrumbs** with a project switcher
- Consistent page headers across the app
- Contextual pro tips throughout projects, changesets, and agents
---
## Under the Hood
Retired an old internal system in favour of a more standard Git + LLM setup, and moved project storage to a modern S3-style backend.
---
## Discontinued
- **Discord integration** removed
- Code extraction now runs exclusively through agents — non-agent extraction flows have been removed
- Removed the non-functional Auto Pull Request toggle
- Removed the split-version action and unused sort options (size of fix, version count)
---
## Artemis Sample Repository Guide
This guide introduces the sample repositories available for testing Artemis features.
Each entry includes the repository purpose, recommended prompts, and what to expect in the results.
---
## **1. Requests (Python)**
**Repository:**
[https://github.com/psf/requests](https://github.com/psf/requests)
**Description:**
Try this project to split large modules, extract reusable logic, and refactor safely without breaking behavior.
## **2. Pandas (Python)**
**Repository:**
[https://github.com/pandas-dev/pandas](https://github.com/pandas-dev/pandas)
**Description:**
Try this project to scan a real codebase, apply custom rules, and fix issues with guided planning.
## **3. Node.js API Tool**
**Repository:**
[https://github.com/vyancharuk/nodejs-api-boilerplate](https://github.com/vyancharuk/nodejs-api-boilerplate)
**Description:**
Try this project to update runtimes, migrate frameworks safely, and clean up outdated or duplicate dependencies.
## **4. DevOps Optimization**
**Repository:**
[https://github.com/nickjj/docker-rails-example](https://github.com/nickjj/docker-rails-example)
A production-ready Rails application using Docker and Docker Compose.
**Suggested Prompt (Plan & Build):**
> *“Analyze this Dockerfile and compose.yml and optimize them for smaller images and faster builds.”*
**What to Review:**
* Reduced image size
* Fewer or more efficient layers
* Improved caching strategies
* Faster build times
## **5. Fixing Critical Issues**
**Repository:**
[https://github.com/PaulleDemon/Django-SAAS-Boilerplate](https://github.com/PaulleDemon/Django-SAAS-Boilerplate)
A production-ready Django SaaS boilerplate.
**How to Use:**
1. Go to **Scan**.
2. Run **Analysis** for security vulnerabilities or performance issues.
3. Review issues from **Critical → Low**.
4. Choose **Fix Issues** or **Plan & Fix** based on your workflow.
**What to Review:**
* High-severity security vulnerabilities
* Performance bottlenecks
* Quality and correctness of proposed fixes
## **6. Application Templates for New Feature Development**
These repositories help you evaluate Artemis’s ability to understand a codebase and implement new features cleanly.
### **Getting Started**
Begin with:
> *“Explain the architecture of this codebase.”*
You can also use the Build a New Feature built-in prompt to decide what to add next:
> *“Help me decide the next feature to build for this project. Lets consider both really interesting / innovative new ideas that I might not have thought of, and also basic feature gaps and fundamentals that might be missing. I'm looking for some inspiration and/or I may have forgotten what the latest state of the codebase is.”*
Use the explanation to choose a feature to build (e.g., a login page, dashboard, or chat sidebar), or jump straight into feature development.
### **Repositories & Suggested Prompts**
### **Avaiga Demo Chatbot**
**Repo:** [https://github.com/Avaiga/demo-chatbot](https://github.com/Avaiga/demo-chatbot)
A template for creating LLM inference web applications in Python.
**Prompt (Plan & Build):**
> *“Improve the data processing and LLM interaction flow.”*
### **Next.js Boilerplate**
**Repo:** [https://github.com/ixartz/Next-js-Boilerplate](https://github.com/ixartz/Next-js-Boilerplate)
A Next.js 15 starter using App Router, Page Router, Tailwind CSS 4, and TypeScript.
**Prompt (Plan & Build):**
> *“Review the server-side rendering functions and optimize them for page speed.”*
### **BCG X AgentKit**
**Repo:** [https://github.com/BCG-X-Official/agentkit](https://github.com/BCG-X-Official/agentkit)
Starter kit for building constrained agents with Next.js, FastAPI, and LangChain.
**Prompt (Plan & Build):**
> *“Optimize the agent chain execution for performance and predictability.”*
### **HTML5 Boilerplate**
**Repo:** [https://github.com/h5bp/html5-boilerplate](https://github.com/h5bp/html5-boilerplate)
A professional HTML5 front-end template.
**Prompt (Plan & Build):**
> *“Refactor this HTML structure into a modern, component-based framework such as React or Svelte.”*
### **FullstackHero .NET Starter Kit**
**Repo:** [https://github.com/fullstackhero/dotnet-starter-kit](https://github.com/fullstackhero/dotnet-starter-kit)
A production-grade, cloud-ready .NET 9 starter kit.
**Prompt (Plan & Build):**
> *“Optimize any inefficient queries or heavy API endpoints.”*
### **Flask AppBuilder**
**Repo:** [https://github.com/dpgaspar/Flask-AppBuilder](https://github.com/dpgaspar/Flask-AppBuilder)
A rapid application development framework based on Flask.
**Prompt (Plan & Build):**
> *“Suggest improvements to structure, security, or performance.”*
### **Swift 6 Module Template**
**Repo:** [https://github.com/fulldecent/swift6-module-template](https://github.com/fulldecent/swift6-module-template)
Template for building reusable Swift 6 modules.
**Prompt (Plan & Build):**
> *“Refactor outdated patterns and migrate the module to async/await.”*
---
## Issues
**Issues** are the results generated by a Maintain run with one or more enabled rules.
Each issue represents a specific **violation**, **risk**, or **code quality concern** found in the codebase.
They help teams improve **correctness**, **reliability**, **security**, and **maintainability** across the project.
### Issue attributes
Each issue in **Artemis** includes the following details:
* **Rule**
The rule that triggered the issue (e.g., *Error and Exception Handling*).
* **Severity**
Indicates how serious the issue is if left unresolved:
* **Critical (9.0-10.0):** May cause crashes, severe security risks, or data loss.
* **High (7.0-8.9):** Major functional or security risks.
* **Medium (4.0-6.9):** Moderate impact; could affect maintainability or stability.
* **Low (0.1-3.9):** Minor or stylistic issues, non-blocking.
* **Difficulty to Fix**
Estimates the effort required to resolve the issue:
* **Easy (0.0-4.9)**
* **Medium (5.0-7.9)**
* **Hard (8.0-10.0)**
* **Location**
Displays the file path and line number where the issue was found.
* **Description**
Explains the cause of the issue and its potential impact.
* **Fix Button**
Provides an actionable recommendation or an automated fix powered by **Artemis**.
### Step 1: Detect issues
Enable one or more rules and run a scan from the **Rules** or **Issues** panel to detect issues.
If you have not defined or enabled any rules yet, refer to the [Rules](rules.md) section.

### Step 2: Review the issue list
Once the run is complete, the issue board shows the current state of every finding:

The board groups findings by condition so you can review them at a glance:
* **Untriaged** for newly detected issues
* **Triaged** for findings that have been reviewed
* **In Progress** for issues currently being worked on
* **Done** for completed or resolved issues
### Step 3: Review details and fix
Click on any issue to view detailed information and available fix options.

In the review flow, the user can mark a finding as a false positive or confirm it as a real issue. Confirming the finding approves the change so the workflow can continue.
### Step 4: Review the changeset and create a PR
After Artemis generates a fix, open the associated changeset from the issue detail view. Review the proposed code changes, confirm that the diff matches the issue, and then create a pull request when the changes are ready for team review.

### Benefits of issue detection
* **Prioritization** - Severity and difficulty scores help teams focus on high-risk, easy-to-fix issues first.
* **Visibility** - Developers can quickly locate and understand problems in the codebase.
* **Continuous improvement** - Regular maintenance runs help keep code quality and project stability consistent over time.
---
## Maintain Overview
The **Maintain** feature in Artemis provides automated code auditing and quality analysis. It allows developers to define custom or pre-built rules that check for patterns, best practices, and potential issues across the codebase. By running Maintain workflows, teams can enforce coding standards, detect vulnerabilities early, and improve overall software maintainability.
## Step 1: Start Maintain
From the **Maintain** tab, start by creating rules that define what Artemis should enforce in your codebase.

The guidance panel walks you through the Maintain workflow and shows the next action to take:
- Create or refine the rule set
- Run the scan against the selected scope
- Triage the detected issues
- Fix the selected issue
- Review the resulting changeset
## Step 2: Run a scan
After rules are available, run a scan to detect matching issues across the codebase.

The run dialog lets you:
- Select the rules to include
- Add optional focus guidance for the scanning agent
- Limit the issue count when you want a bounded run
- Choose the model that will drive the workflow
## Step 3: Work the issues
Artemis groups findings by issue status so you can move from untriaged items to active work and completed fixes without losing context.
## What this gives you
- A repeatable maintenance workflow for code quality review
- Clear instructions at each step of the process
- Structured issue handling from detection to validation
- A consistent way to track changes through the resulting changeset
## Next steps
- Define or select your [rules](./rules.md)
- Review the [issues](./issues.md) generated by a maintenance run
---
## Rules
Rules define the checks that guide a Maintain run. Each rule captures a focused quality standard, pattern, or constraint that Artemis can evaluate consistently across your codebase.
Every rule in Artemis includes the following attributes:
* **Rule Name**
A descriptive title (e.g., *Error and Exception Handling*, *Input Validation*).
* **Description**
Explains the purpose of the rule, what it enforces, and why it matters.
Example: *Ensures all user inputs are validated and sanitized to prevent vulnerabilities and maintain data integrity.*
* **Importance Level**
Defines how critical the rule is for your project:
* **Mandatory** -> Must always be followed.
* **Essential** -> Strongly recommended for correctness and stability.
* **Preferred** -> Encouraged for maintainability and best practices.
* **Advisory** -> Optional recommendation.
* **Enabled / Disabled**
You can toggle each rule on or off based on project needs.
## Creating a rule
### Step 1: Open the rule panel
Navigate to **Maintain > Rules**.
### Step 2: Choose or add a rule

Use the model prompt to describe the rule you want Artemis to create, or select one of the built-in rule templates below the chat bar. You can also continue from the sidebar by selecting an existing rule and following the same flow.

### Step 3: Review the generated rule
Artemis opens a rule draft based on the model output or the selected built-in template. Review the proposed rule before moving forward.

### Step 4: Apply the rule and continue
Artemis opens a rule draft, may ask clarifying questions you can answer, and then you can apply the rule to proceed.

### Step 5: Review the resulting status
If the rule produces no findings, it is marked as **Don't**. If Artemis finds issues, they appear as **Do** items that you can continue working through in the maintenance flow.

---
### Rule outcome behavior
Rules are evaluated as part of the Maintain workflow, and the result determines how the rule is surfaced:
* **Don't** indicates that the rule did not identify actionable issues.
* **Do** indicates that the rule found issues and can continue into the remediation flow.
* **Apply** lets the user approve the generated rule so the workflow can advance to the next stage.
### By defining rules, you can:
* Enforce consistent coding standards across teams
* Detect risky or non-compliant patterns early
* Provide actionable feedback to developers
* Improve reliability, security, and maintainability
---
### Next step
Proceed to review and resolve [issues](./issues.md).
---
## Admin Settings
Admin Settings are available to administrators only and provide controls for managing users, governing model access, setting agent limits, and monitoring the platform.
:::info
For settings available to all users, see [User Settings](./user-settings.md).
:::
---
## AI
### Agent Limits
Administrators can view and manage agent budget and step limits for every user on the platform.

- **Budget Limit** — Maximum cost ($) allowed per agent run, per user. Click the edit icon next to any user to adjust.
- **Steps Limit** — Maximum number of steps allowed per agent run, per user.
Use the search bar to find a specific user. These limits are enforced platform-wide — when an agent reaches its limit during a run, it stops and returns results up to that point.
### Models
Control which LLM models are available across the platform, set organisation-wide defaults, and configure custom LLM providers.

- **Enable or disable models** — Turn off models not approved for use in your organisation.
- **Lock models** — Prevent users from toggling specific models on or off.
- **Set default models** — Define which model is used for each task type (chat, coding, scoring, etc.) across all users.
- **Profiles** — Add custom LLM providers with their API credentials and endpoints, and configure per-model token costs for accurate cost tracking.
- **Presets** — Select which models are active and available to users across the platform.
For a full list of supported models and instructions on adding a custom LLM provider, see [LLMs in Artemis](../architecture/llm-usage.md).
---
## System
### Logs
View live platform logs for monitoring and troubleshooting. The Logs page is available to administrators only.

Logs are tailed in real time and can be used to trace agent runs, identify errors, and audit platform activity.
### Feature Flags
Enable or disable platform features for your organisation.

---
## Organisation
### Users
View and manage all registered users on the platform.

- See all user names, email addresses, and account status
- Manage user roles and access
---
## User Settings
User Settings let you configure agent limits, manage contexts, connect integrations, and monitor system health.
## Accessing Platform Settings
Click **Platform Settings** in the top navigation bar. The left sidebar organises all settings into three groups: **AI**, **Integrations**, and **System**.
---
## AI
### Agent Limits
Set the maximum cost and steps allowed per agent run to control resource usage and prevent runaway operations.

- **Budget Limit** — Maximum cost ($) allowed per agent run. Click the edit icon to adjust.
- **Steps Limit** — Maximum number of steps allowed per agent run. Click the edit icon to adjust.
### Contexts
Manage what agents remember across runs. Each context item has an availability mode that controls when the agent can access it.


- **Always** — The agent always has access to this context.
- **On Demand** — The agent decides when to read it.
- **Off** — The agent ignores it entirely.
A token-budget bar shows how much of the context budget is in use across all active items.
---
## Integrations
### Git
Connect Artemis to your repositories via GitHub App or personal access keys.
- **GitHub App** — Create pull requests and sync repositories automatically. Connect your GitHub account and manage installations per organisation or personal account.
- **Access Keys** — Add personal access tokens or git SSH keys for repository integration.
See [Git Keys](/project-setup/git-keys) for setup instructions.
### Runners
Validate generated code using your own hosted runners and customise the environment used to run project scripts.
See [Artemis Runner](/features/artemis-runner) for setup instructions.
### Artemis CLI
The command-line interface for managing projects, tasks, and optimisations directly from your terminal.
See [Artemis CLI](/features/artemis-cli) for installation and usage.
### API Keys
Generate and manage personal API keys for authenticating with the Artemis CLI and external integrations.

### MCP Servers
Configure Model Context Protocol (MCP) servers for your account. Configured servers are available across all agent runs — chat, planning, coding, and target generation. Only HTTP-based transports are supported (SSE and Streamable HTTP).
See [MCP Servers](/features/mcp-servers) for configuration details.
### Artemis Skills
Skills are Claude Code plugins that guide you through setting up and configuring Artemis directly from your terminal.
See [Artemis Agent Skills](/features/artemis-agent-skills) for available skills and installation.
---
## System
### Health
Monitor the real-time status of all Artemis platform microservices and their dependencies.

The Health dashboard shows each service's operational status, component count, and HTTP response codes. Click **Refresh** to get the latest status.
---
:::tip Admin Settings
If you are an organisation administrator, additional settings are available for cost tracking, model governance, and user management. See [Admin & Governance Settings](./admin-settings.md).
:::
---
## ALE Benchmark Optimization
## Project Overview
**Goal:** Optimize AI agents for competitive programming using the ALE Benchmark through evolutionary prompt engineering and advanced search strategies
**Before:** [Baseline zero-shot agent](https://github.com/turintech/ale-bench-optimisation) (66% acceptance rate)
**After:** [Optimized agent with CoT and evolutionary search](https://github.com/turintech/ale-bench-optimisation) (75% acceptance rate, +13.6%)
**Target Users:** AI researchers, competitive programming enthusiasts, teams building production-grade agents
**Use Cases:**
- Optimizing AI agents for algorithm design problems
- Evolutionary prompt refinement for competitive programming
- Cost-effective model selection (small models vs. large flagship models)
- Benchmarking agentic capabilities under real-world constraints
## Background
AI agents are transitioning from experiments to production systems. The challenge: should you use the most powerful (and expensive) models, or can smaller, optimized models achieve comparable performance through intelligent engineering?
This is an optimization problem. When you have a narrowly defined goal—like competitive programming—you don't need maximum generalist capability. Smaller models (under 10B parameters) can match larger ones on specific tasks while running 15× faster and costing 10-30× less [Belcak et al., 2024]. The key insight: most agentic tasks are repetitive, scoped, and non-conversational.
The ALE Benchmark [Imajuku et al., 2024] provides a rigorous testbed for this question: can smaller, tuned models be evolved into agents that deliver reliable, efficient solutions at scale? ALE focuses on heuristic optimization problems derived from real AtCoder contests, providing 40 challenging test cases that resist saturation and offer significant room for improvement.
## Implementation
We explored two optimization paths to evolve the baseline agent's performance.
### Phase 1: Prompt Optimization (CoT + Self-Correction)
Evolved prompts from simple chain-of-thought to sophisticated problem-solving with embedded self-correction. The baseline approach uses straightforward reasoning:
**Baseline Prompt Structure** — Simple chain-of-thought reasoning:
```python
# From agent_baseline/prompts/prompt.py
SOLUTION APPROACH:
STEP 1 - PROBLEM UNDERSTANDING:
• Identify problem type (graph, optimization, simulation, etc.)
• Determine complexity constraints
• Extract key patterns and requirements
STEP 2 - ALGORITHM SELECTION:
• Choose primary approach based on problem type
• Consider alternative methods
• Plan implementation strategy
STEP 3 - IMPLEMENTATION STRATEGY:
• Select data structures
• Plan solution flow
• Consider edge cases
STEP 4 - CODE GENERATION:
• Implement the algorithm
• Add necessary optimizations
• Ensure correctness before optimization
```
**Optimized Prompt Structure** — Enhanced with embedded self-correction:
```python
# From agent_optimized/prompts/prompt.py (383 lines)
STEP 5 - SELF-CORRECTION CHECKLIST:
Before writing the final code, mentally walk through your planned implementation:
• Empty inputs / smallest allowed input size
• Inputs at maximum constraint values
• Duplicates, sorted/reversed order, or special values if relevant
• Data types: Are all chosen types large enough? (e.g 64-bit for 10^18)
• Does the solution logic handle all branches and early-exit cases?
• Time complexity: Will it meet the problem's constraints?
• Account for all relevant boundary and off-by-one errors
• If floating-point: Will precision issues impact correctness?
• For graph problems: disconnected graphs, self-loops, multiple edges?
• Are all edge cases described in the problem statement addressed?
```
**Results**: Acceptance Rate +13.6% (75.0%), Performance +8.9% (546.0 ± 61.5 points), Cost maintained ~$25/eval.
### Phase 2: Search Optimization (Genetic Algorithm + Advanced Search)
Employed genetic algorithms with beam search and taboo memory for systematic solution space exploration. The optimized agent implements multiple complementary search strategies:
**A* Search with Heuristics** — Informed search for solution space exploration:
```python
# From agent_optimized/search/algorithms.py
class AStarSearch:
def __init__(self, heuristic_fn=None, timing_manager=None):
self.open_set: List[Tuple[float, SolutionCandidate]] = []
self.closed_set: Set[str] = set()
self.g_scores: Dict[str, float] = {} # Path cost from start
self.f_scores: Dict[str, float] = {} # g + heuristic (h)
def add_candidate(self, candidate: SolutionCandidate, g_score=None):
"""Add candidate with g_score (cost) and computed f_score (priority)"""
h_score = self.heuristic_fn(candidate) # Remaining work estimate
f_score = g_score + h_score # A* priority
heapq.heappush(self.open_set, (f_score, candidate))
def _default_heuristic(self, candidate: SolutionCandidate) -> float:
"""Heuristic: remaining distance to perfect solution"""
remaining_score = max(0, 1.0 - candidate.score)
if candidate.judge_result == "WRONG_ANSWER":
remaining_score += 0.3 # More work needed
elif candidate.judge_result == "TIME_LIMIT_EXCEEDED":
remaining_score += 0.2 # Optimization possible
return remaining_score * 0.8
```
**Genetic Algorithm** — Population-based evolutionary search:
```python
# From agent_optimized/search/algorithms.py
class GeneticAlgorithm:
def __init__(self, population_size=50, mutation_rate=0.1,
crossover_rate=0.7, elite_size=10):
self.population: List[SolutionCandidate] = []
self.generation = 0
def _crossover(self, parent1, parent2) -> SolutionCandidate:
"""Combine two solutions at random crossover point"""
code1_lines = parent1.code.split('\n')
code2_lines = parent2.code.split('\n')
point1 = random.randint(1, len(code1_lines) - 1)
point2 = random.randint(1, len(code2_lines) - 1)
# Inherit from both parents
offspring_code = '\n'.join(code1_lines[:point1] + code2_lines[point2:])
return SolutionCandidate(offspring_code, parent1.language,
score=(parent1.score + parent2.score) / 2)
def evolve_generation(self):
"""Evolve population: select elite, create offspring, mutate"""
self.population.sort(key=lambda x: x.score, reverse=True)
# Keep best solutions (elitism)
new_population = self.population[:self.elite_size]
# Generate offspring through crossover and mutation
while len(new_population) < self.population_size:
parent1 = self._tournament_selection()
parent2 = self._tournament_selection()
child = self._crossover(parent1, parent2)
if random.random() < self.mutation_rate:
child = self._mutate(child)
new_population.append(child)
self.population = new_population
self.generation += 1
```
**Taboo Search** — Memory-based search to avoid revisiting solutions:
```python
# From agent_optimized/search/algorithms.py
class TabooSearch:
def __init__(self, max_size=1000):
self.lru_cache: OrderedDict[str, SolutionCandidate] = OrderedDict()
self.access_count: Dict[str, int] = defaultdict(int)
def is_taboo(self, candidate: SolutionCandidate) -> bool:
"""Check if solution was recently explored"""
candidate_hash = candidate.get_hash()
if candidate_hash in self.lru_cache:
self.lru_cache.move_to_end(candidate_hash) # Update LRU
self.access_count[candidate_hash] += 1
return True
return False
def add_to_taboo(self, candidate: SolutionCandidate):
"""Mark solution as recently explored"""
candidate_hash = candidate.get_hash()
if len(self.lru_cache) > self.max_size:
# Evict least recently used
oldest_hash, _ = self.lru_cache.popitem(last=False)
self.access_count.pop(oldest_hash, None)
self.lru_cache[candidate_hash] = candidate
```
**Parallel Search Orchestration** — Coordinate multiple algorithms:
```python
# From agent_optimized/search/algorithms.py
class ParallelSearchOrchestrator:
def __init__(self, max_workers=None):
self.executor = ThreadPoolExecutor(max_workers=max_workers or 8)
self.timing_manager = TimingManager()
self.taboo_search = TabooSearch(max_size=2000)
self.work_stealing_queue = WorkStealingQueue()
def run_parallel_search(self, initial_candidates,
search_algorithms=None, max_iterations=10):
"""Execute multiple search strategies in parallel"""
# Launch A*, genetic algorithm, and beam search simultaneously
# Each algorithm explores independently
# Work stealing allows load balancing when some threads finish early
# Taboo search shared across all algorithms prevents duplicate work
```
**Results**: Acceptance Rate +9.3% (72.2%), Performance 530.9 ± 31.2 points with reduced variance, 29% runtime reduction, ~$24/eval.
## Results
**Key Improvements:**
- **Prompt Optimization**: +13.6% acceptance rate (66% → 75%), reduced errors through self-correction
- **Search Optimization**: +9.3% acceptance rate, 29% faster execution, more consistent performance
- **Cost Efficiency**: Maintained sub-$26 per evaluation while improving performance
- **Problem Recovery**: Critical problems improved dramatically (e.g., ahc007: -61 → 669 points)
## Repository
Complete source code available at [github.com/turintech/ale-bench-optimisation](https://github.com/turintech/ale-bench-optimisation)
**Quick start:**
```bash
git clone https://github.com/turintech/ale-bench-optimisation
cd ale-bench-optimisation
pip install -r requirements.txt
python3 main_optimized.py --problems ahc001
```
---
## References
* Belcak, P., Heinrich, G., Diao, S., Fu, Y., Dong, X., Muralidharan, S., Lin, Y. C., & Molchanov, P. (2024). "Small Language Models are the Future of Agentic AI." *arXiv preprint arXiv:2406.02153.*
* Imajuku, Y., Horie, K., Iwata, Y., Aoki, K., Takahashi, N., & Akiba, T. (2024). "ALE-Bench: A Benchmark for Long-Horizon Objective-Driven Algorithm Engineering." *arXiv preprint arXiv:2406.09050.*
---
## Building an Anomaly Detection Tool
Here we will demonstrate how to use the Artemis Planning Agent to build a command-line tool for anomaly detection in tabular data. The starting point is a simple Python template. Through an iterative process of question answering with our planner, we develop a specific and well-structured plan to build our desired tool with clear validation points and success criteria. The end result is a complete tool with data loading, algorithm implementation, and visualization, along with comprehensive documentation.
## Project Overview
**Goal:** Build a CLI tool that identifies outliers in CSV files using machine learning
**Before:** [Python template](https://github.com/turintech/project-python/tree/acc6e7a) (`acc6e7a`)
**After:** [Complete anomaly detection tool](https://github.com/turintech/project-python/tree/f8ad1ad) (`f8ad1ad`)
**Target Users:** Data scientists and analysts working with numeric datasets
**Use Cases:**
- Fraud detection in financial transactions
- Sensor error identification in IoT data
- Data quality assessment and validation
## Planning Process
We started with a simple statement: **"I want to build an anomaly detection tool."**
The Artemis Planning Agent helped us think through the requirements by asking clarifying questions:
**User Requirements:**
- What type of data? → General tabular data
- Primary use case? → General-purpose tool
- What to do with anomalies? → Visualize in dashboard/charts
- How to provide data? → Supply path to CSV file
- What form should it take? → Command-line tool (CLI)
**Technical Requirements:**
- Specific algorithms? → Machine learning (Isolation Forest, One-Class SVM)
- Expected data scale? → Large (hundreds of thousands of rows)
- Configurable parameters? → Yes - via command-line flags
- How to display charts? → Generate static image files
- Both algorithms or one? → Both - run both and compare results
From these answers, Artemis generated a 9-task plan with a clear strategy: **Build a working MVP first (tasks 1-6), then enhance it (tasks 7-9).** This approach meant we'd have a functional tool using Isolation Forest after 6 tasks, then add the second algorithm and comparison features.
Each task in the plan comes with clear structure: specific goals and deliverables, detailed technical specifications, files to modify, and measurable success criteria. This transforms a vague request into actionable development steps with concrete validation points.
## Implementation
We built the tool in two phases: first creating a working MVP, then enhancing it with comparison capabilities.
### Phase 1: MVP - Working Anomaly Detection Tool (Tasks 1-6)
These six tasks created a complete, functional tool using Isolation Forest:
**1. Set up project dependencies and structure** - Established foundation with pandas, scikit-learn, matplotlib, and numpy for data processing, ML algorithms, and visualization. ([`1f17c19`](https://github.com/turintech/project-python/commit/1f17c19))
**2. Implement CSV data loading and preprocessing** - Built robust data pipeline with validation, encoding, and scaling optimized for large datasets. ([`1777042`](https://github.com/turintech/project-python/commit/1777042))
**3. Implement Isolation Forest anomaly detection** - Added first ML algorithm with configurable parameters and optimized performance for hundreds of thousands of rows. ([`83dfad3`](https://github.com/turintech/project-python/commit/83dfad3))
**4. Implement visualization and chart generation** - Created comprehensive visualization suite with PCA/t-SNE dimensionality reduction and multi-panel dashboards. ([`49d49d7`](https://github.com/turintech/project-python/commit/49d49d7))
**5. Build CLI interface with argparse** - Implemented command-line interface with parameter configuration, validation, and progress feedback. ([`3c7e222`](https://github.com/turintech/project-python/commit/3c7e222))
**6. Integration and pipeline orchestration** - Wired all components together into `main.py` and integrated the complete pipeline with comprehensive error handling. ([`d078f4a`](https://github.com/turintech/project-python/commit/d078f4a))
**Result after Task 6:** A fully functional anomaly detection CLI tool that processes CSV files, detects outliers using Isolation Forest, and generates clear visualizations.
### Phase 2: Enhancement - Dual Algorithm Comparison (Tasks 7-9)
These three tasks added the second algorithm and comparison capabilities:
**7. Implement One-Class SVM anomaly detection** - Added second ML algorithm providing complementary detection approach with performance optimization for large-scale data. ([`acd5d8a`](https://github.com/turintech/project-python/commit/acd5d8a))
**8. Implement result comparison and aggregation** - Built comparison logic with algorithm agreement metrics, consensus detection, and statistical measures of inter-algorithm agreement. ([`5682b45`](https://github.com/turintech/project-python/commit/5682b45))
**9. Documentation and README** - Completed professional documentation with installation instructions, usage examples, algorithm guidance, and troubleshooting. ([`f8ad1ad`](https://github.com/turintech/project-python/commit/f8ad1ad))
**Final Result:** A sophisticated tool that runs both algorithms, compares results, identifies consensus anomalies, and provides agreement metrics showing multi-algorithm consensus.
The Artemis Planning Agent breaks down requirements into manageable tasks and guides you through building each component step by step, from initial template to complete, documented tool.
---
## Building a Clustering Tool
Here we will demonstrate how to use the Artemis Planning Agent to build a command-line tool for clustering analysis in tabular data. The starting point is a simple Python template. Through an iterative process of question answering with our planner, we develop a specific and well-structured plan to build our desired tool with clear validation points and success criteria. The end result is a complete tool with data loading, multiple clustering algorithms, evaluation metrics, and visualization, along with comprehensive documentation.
## Project Overview
**Goal:** Build a CLI tool that clusters observations in CSV files using machine learning
**Before:** [Python template](https://github.com/turintech/project-python/tree/acc6e7a) (`acc6e7a`)
**After:** [Complete clustering tool](https://github.com/turintech/project-python/tree/project-clustering) (`e946245`)
**Target Users:** Data scientists and analysts working with numeric datasets
**Use Cases:**
- Customer segmentation and behavioral analysis
- Gene expression clustering in bioinformatics
- Document clustering for text analysis and organization
## Planning Process
We started with a simple statement: **"I want to build a clustering tool."**
The Artemis Planning Agent helped us think through the requirements by asking clarifying questions:
**User Requirements:**
- What type of data? → Numerical/tabular data
- How will users interact? → Command-line interface (CLI)
- What file formats? → CSV only
- Intended use case? → General-purpose (any tabular data)
- What should it output? → Both CSV output and visualizations
**Technical Requirements:**
- Which algorithms? → Multiple algorithms (K-means, DBSCAN, hierarchical clustering)
- Include evaluation metrics? → Yes (silhouette score, inertia)
- Data preprocessing? → Yes (automatic scaling, normalization, missing value handling)
- Visualization library? → Seaborn (prettier static plots)
- Save format? → PNG files
- Configuration support? → Yes, support YAML/JSON config files
From these answers, Artemis generated a comprehensive plan with a clear strategy: **Build a working MVP first, then enhance it with multiple algorithms and advanced features.** This approach meant we'd have a functional tool using K-means after the core tasks, then add DBSCAN, hierarchical clustering, and comparison capabilities.
Each task in the plan comes with clear structure: specific goals and deliverables, detailed technical specifications, files to modify, and measurable success criteria. This transforms a vague request into actionable development steps with concrete validation points.
## Implementation
We built the tool in two phases: first creating a working MVP, then enhancing it with advanced features.
### Phase 1: MVP - Working Clustering Tool (Tasks 1-7)
These tasks created a complete, functional clustering tool:
**1. Project setup and dependencies** - Set up the foundation with pandas, scikit-learn, seaborn, and numpy for data processing, clustering algorithms, and visualization. ([`6400a9f`](https://github.com/turintech/project-python/commit/6400a9f))
**2. Data loading module** - Built a robust CSV data loader with comprehensive validation pipeline and error handling. ([`fb61df7`](https://github.com/turintech/project-python/commit/fb61df7))
**3. Clustering algorithms module** - Implemented K-means, DBSCAN, and hierarchical clustering with comprehensive validation and configurable parameters. ([`ee1cb38`](https://github.com/turintech/project-python/commit/ee1cb38))
**4. Cluster evaluation module** - Added algorithm-aware cluster evaluation with silhouette score, inertia, and Davies-Bouldin index metrics. ([`71a9419`](https://github.com/turintech/project-python/commit/71a9419))
**5. Output generation** - Implemented output generation and formatting module with CSV, metrics, and file management support. ([`35e6a03`](https://github.com/turintech/project-python/commit/35e6a03))
**6. Configuration file support** - Added configuration loading and validation module with YAML/JSON support, schema validation, and CLI overrides. ([`60d3ed5`](https://github.com/turintech/project-python/commit/60d3ed5))
**7. Data preprocessing module** - Implemented comprehensive preprocessing pipeline with scaling, imputation, and column handling. ([`e190888`](https://github.com/turintech/project-python/commit/e190888))
**Result after Task 7:** A fully functional clustering tool with data loading, multiple algorithms, evaluation metrics, output generation, and configuration support.
### Phase 2: Enhancement - Visualization, CLI, and Testing (Tasks 8-10)
These tasks completed the tool with visualization and user interface:
**8. Visualization module** - Added comprehensive clustering visualization with PCA support, colorblind-friendly palettes, and edge case handling. ([`c5fc05a`](https://github.com/turintech/project-python/commit/c5fc05a))
**9. CLI interface with click** - Built complete CLI frontend with algorithm execution pipeline, config file support, and comprehensive error handling. ([`7adb651`](https://github.com/turintech/project-python/commit/7adb651))
**10. Testing and documentation** - Added comprehensive testing suite with pytest framework, unit/integration tests, usage guide, and algorithm documentation. ([`ff52068`](https://github.com/turintech/project-python/commit/ff52068))
**Final Result:** A sophisticated clustering tool that supports K-means, DBSCAN, and hierarchical clustering with comprehensive evaluation metrics, visualization, configuration file support, CLI interface, and complete test coverage and documentation.
The Artemis Planning Agent breaks down requirements into manageable tasks and guides you through building each component step by step, from initial template to complete, documented clustering tool.
---
## Feature Generation with Artemis and evoML
## Project Overview
**Goal:** Generate domain-specific features for credit default risk classification using Artemis Intelligence's genetic algorithm
**Before:** [Baseline script with template function](https://github.com/turintech/credit-default-risk-optimisation/blob/f05c165/credit_script.py) (minimal feature engineering)
**After:** [Optimized script with domain-specific features](https://github.com/turintech/credit-default-risk-optimisation/blob/f05c165/credit_script_optimised.py) (20+ engineered features: LightGBM 0.867 ROC-AUC test, Logistic Regression 0.860 ROC-AUC test)
**Target Users:** Data scientists, machine learning engineers, credit risk analysts
**Use Cases:**
- Automated feature generation for financial risk models
- Domain-specific feature engineering with genetic algorithms
- Improving classifier performance through intelligent feature discovery
## Artemis as a Feature Generation Tool
The future of data science is merging with generative AI. Provided with the right tooling, agents can not only build models, but optimise their performance and use their domain knowledge to search for highly interpretable predictive features. Here we demonstrate how Artemis Intelligence’s genetic algorithm can intelligently drive this process, at the example of a crucial step in the ML workflow: **feature generation**.
Feature generation is the process of transforming raw data into meaningful input features to improve model performance. This process can be as straightforward as applying an appropriate encoding scheme to a categorical variable, or standardizing a numerical feature to a particular scale. But often what is required is much more complex dataset expansion, involving engineering new features as the product of an interaction between other features, or adding and creating completely new, domain-relevant data to aid the model in extracting meaningful contextual information, as we balance noise to prevent overfitting and are mindful of data leakage. Here we describe how a data scientist can use Artemis to generate such complex new features for their model(s), with the aim of boosting the performance of a linear model, as a post-hoc analysis method.
This project's initial objective is to build models that can classify whether a customer is likely to obtain the status of serious delinquency in two years, using their credit history data. The end-to-end baseline analysis of this project can be seen [here](https://docs.evoml.ai/evoml-client/examples/give-me-some-credit).
Here and throughout this use case, we utilize our [evoML python client package](https://docs.evoml.ai/evoml-client/introduction), which enables interaction with our AutoML platform, but the example can be reproduced with any script which triggers model building and evaluation.
## Prerequisites
### 1. Project environment
A minimal setup for this includes:
- A script that 1.) loads your dataset, 2.) **with a custom feature engineering template function**, 3.) applies modeling, printing the models' loss values. This step is crucial for tracking model performance during feature generation using our runner. This should represent your baseline. Here we have used three models, registered in the EvoML platform - an xgboost classifier, a lightgbm classifier and a linear regression classifier, with an ROC AUC objective.
*This function would just serve as template for Artemis and could be used to control the degree of complexity for your new features.
``` python
# From credit_script.py (baseline)
def engineer_features(df: pd.DataFrame) -> pd.DataFrame:
"""
Template function for feature engineering.
Args:
df (pd.DataFrame): Input dataframe
Returns:
pd.DataFrame: DataFrame with new features
"""
# Create a copy to avoid modifying the original dataframe
df_engineered = df.copy()
feature_2 = df_engineered.columns[1]
feature_3 = df_engineered.columns[2]
# Example of creating a new feature by multiplying two existing features
#df_engineered["feature_1"] = df_engineered[feature_3] + df_engineered[feature_2]
return df_engineered
df = engineer_features(df)
print(df.columns)
```
[Full baseline script available on GitHub](https://github.com/turintech/credit-default-risk-optimisation/blob/f05c165/credit_script.py)
- An .md file for presenting embeddable context to the data prior to preprocessing, describing feature types, and providing context to the target. Below is an outline of the dataset we have used for this example, which is readily downloadable [here](https://www.kaggle.com/datasets/camnugent/give-me-some-credit).

### 2. Project setup
- A running instance of your [Artemis Runner](../../features/artemis-runner.md) for real-time baseline and variant execution and validation.
- A benchmark command to execute your script which will print the model's objective result to the logs. This allows Artemis Intelligence to consume this output and adapt subsequent iterations to your stated goal (prompt).

## Step-by-Step Instructions
### 1. Validate your benchmark command on Artemis via executing it with the runner. This would serve as your seed program for the recommendation trial.

### For a clear reference, this is how our credit default risk use case output looked like:

### 2. Create a snippet from the baseline script you will be executing.

The optimized script demonstrates domain-specific feature engineering for credit risk. Key feature categories from the final optimized implementation:
```python
# From credit_script_optimised.py (optimized features excerpt)
# Payment history features
df_engineered["total_delinquencies"] = (
df_engineered["NumberOfTime30_59DaysPastDueNotWorse"]
+ df_engineered["NumberOfTime60_89DaysPastDueNotWorse"]
+ df_engineered["NumberOfTimes90DaysLate"]
)
df_engineered["delinquency_severity_score"] = (
df_engineered["NumberOfTime30_59DaysPastDueNotWorse"] * 1
+ df_engineered["NumberOfTime60_89DaysPastDueNotWorse"] * 3
+ df_engineered["NumberOfTimes90DaysLate"] * 5
)
# Utilization features
df_engineered["very_high_utilization"] = (
df_engineered["RevolvingUtilizationOfUnsecuredLines"] > 0.8
).astype(int)
# Income stability features
df_engineered["income_per_dependent"] = df_engineered["MonthlyIncome"] / (
df_engineered["NumberOfDependents"] + 1
)
```
[View complete optimized feature engineering](https://github.com/turintech/credit-default-risk-optimisation/blob/f05c165/credit_script_optimised.py#L47-L121) with all 20+ domain-specific features
### 3. Tell Artemis your objective and hit go!
You should provide a markdown file for reference to the algorithm, choose your LLMs, and allow your runner to execute the build command ('Configuration'). You also have control over the population count. When this is configured, you can start your recommendation task. Artemis derives fitness metrics from the logs produced by the task and uses them as the functional guidelines to score candidates, prune each generation and propagate the top-performing individuals to the next population. During this selection, Artemis not only ensures that your code is runnable but that it also successfully boosts (in our case) the value of your objective.
We were aiming at boosting our linear model's performance. Our prompt looked like this:

### 4. Our results
Artemis successfully boosted the performance of our logistic regression classifier, by insightfully engineering new features into our dataset, enabling us to derive even more meaningful insights for our trial. We visualise these with the help of EvoML:
### Baseline results:

### Results from final variant:

Artemis iteratively improved model discrimination (ROC AUC): +0.04 on validation and +0.50 on test, relative to the baseline.

In our Feature Importance tab for the respective model, we see that the age-bucket features generated by Artemis improve explanatory power; their average contribution to the positive (serious-delinquency) class is negative—consistent with age being protective—yet they enhance ranking performance (higher ROC AUC) by sharpening separation across risk strata.
### Artemis Chat
How many features did Artemis create? We can always ask:

Artemis created those 14 new features by applying domain knowledge about credit risk factors and using statistical transformations such as sums, ratios, thresholds, and interaction terms to extract meaningful signal from the original data. EvoML then encoded these features in a type‑aware, leakage‑safe manner (e.g., one‑hot/target encoding for categorical buckets, scaling for continuous variables, ordinal/monotonic encodings where appropriate), handled missingness, and ensured consistent transformations across train/validation/test splits.
The optimized implementation generates 20+ features across multiple categories:
```python
# From credit_script_optimised.py (additional feature categories)
# Debt management features
df_engineered["high_debt_burden"] = (df_engineered["DebtRatio"] > 0.43).astype(int)
# Credit mix features
df_engineered["real_estate_to_total_credit_ratio"] = df_engineered[
"NumberRealEstateLoansOrLines"
] / df_engineered["NumberOfOpenCreditLinesAndLoans"].replace(0, 1)
# Risk interaction features
df_engineered["high_debt_with_delinquency"] = (
(df_engineered["DebtRatio"] > 0.5) & (df_engineered["total_delinquencies"] > 0)
).astype(int)
```
Users who handle those types of data transformation themselves can always specify their preferences in a new recommendation trial, and can also handle further code transformations to their script in a zero-shot or agentic manner.

So there you have it! By giving your model building script to the Artemis Intelligence we can automatically leverage the domain knowledge of these models to generate new model strategies while at the same time using rigorous metrics to provide feedback and guide the optimiser to the best solution.
## Repository
Complete source code and data available at [github.com/turintech/credit-default-risk-optimisation](https://github.com/turintech/credit-default-risk-optimisation)
**Quick start:**
```bash
git clone https://github.com/turintech/credit-default-risk-optimisation
cd credit-default-risk-optimisation
pip install -e .
# Run baseline script
python credit_script.py --data data/credit_data.csv --env_path data/.env
# Run optimized script
python credit_script_optimised.py --train_data data/credit_data.csv --env_path data/.env
```
For complete documentation including feature descriptions, setup instructions, and configuration options, see the [project README](https://github.com/turintech/credit-default-risk-optimisation#readme).
---
## Livestock Health Monitoring System
## **Project Overview**
TThis use case demonstrates how the Artemis Planning Agent transformed a simple idea—
**“I want to build a cattle health monitoring system using a neck sensor.”**
—into a complete livestock health intelligence platform.
Starting from a raw concept, Artemis acted as a **technical architect**, **research assistant** and a **developer**, uncovering requirements, exploring scientific literature, and shaping a multi-layer intelligence system capable of detecting behavior, analyzing physiological patterns, and generating real-time health insights for farmers.
### **Goal**
Build a system that automatically interprets neck-mounted sensor data and produces meaningful health insights, alerts, and behavioral understanding in real time.
We just have a single sentence idea with raw sensor readings (accelerometer, gyroscope, temperature) and no defined pipeline.
## [**Planning Process**](../../build/Plan/plan-overview.md)
Artemis transformed the problem definition into a production-ready design.
### [**How Artemis Clarified the Requirements**](../../build/Plan/Make-plan.md#2-answer-the-planning-questions)
When provided with the initial statement, Artemis immediately began refining the problem.
It asked clarifying questions to understand:
* What sensors exist
* What types of insights matter
* Whether data should be processed live, in batch, or both
* What kind of output and interface is expected
* Whether we need explainability and personalized baselines
* Operational constraints such as sampling rate and storage
Through this clarification loop, Artemis gathered enough information to design the **three-layer intelligence architecture**:
1. **Physical Behavior**
2. **Physiological Analysis**
3. **Health Intelligence**
This structure emerged naturally from Artemis interpreting the collected requirements and shaping them into a clean, scalable design.
### **Artemis as a Research Assistant**
After defining the problem, Artemis automatically explored the scientific and technical space to determine the best approach.
- #### Artemis researched:
Artemis investigated how animal posture can be inferred from accelerometer angles, how walking patterns emerge through acceleration variance, the established temperature thresholds for fever and estrus, the influence of circadian rhythms on body temperature, and how combining temperature with movement data can reduce false positives. This allowed the system to be grounded in validated physiological and behavioral principles.
- #### Artemis discovered datasets:
Including publicly available cattle behavior datasets (e.g., Japanese Black Beef Cow Dataset), helping validate the chosen approaches.
- #### Artemis reviewed UI/UX patterns:
Recommending alert-first dashboards, historical trends, and simple CSV upload entry points.
- #### Artemis selected the right methodology:
A **hybrid model** — simple rules for posture, ML for complex motion, and rolling statistical models for physiology.
The result is a system grounded in real science, best practices, and industry patterns — all gathered autonomously by Artemis.
## **System Architecture**
Artemis synthesized all requirements and research into a three-layer intelligence pipeline:
```
Input (CSV or Real-time MQTT)
↓
Layer 1 — Behavior Classification
(lying, standing, walking, feeding, activity level)
↓
Layer 2 — Physiological Analysis
(temperature baseline, trends, circadian adjustments)
↓
Layer 3 — Health Intelligence
(alerts, scoring, events, estrus & fever detection)
↓
Output — Dashboard + SQLite DB
```
Each layer is modular and feeds into the next, allowing independent updates and easier debugging.
## **Dual Processing Modes**
Artemis identified the need for two complementary ways of processing data:
**Batch Processing (implemented first)**
This workflow supports CSV uploads, enabling Full 3-layer analysis, stored results in SQLite and dashboard-ready insights.
It provided a stable environment for testing and validating logic.
**Real-Time Streaming (added later)**
Once batch mode was complete, we used the **“build new feature”** buit-in prompt of Artemis planner to add real time analysis support.
Artemis added MQTT ingestion, Continuous event processing, Live alert generation and Real-time dashboard updates.
The live pipeline reused the same intelligence layers designed earlier, demonstrating Artemis’s ability to extend systems progressively without re-architecting.
## **Final Capabilities**
#### **Behavior Detection**
* Lying, standing, walking, feeding
* Movement intensity
* Rest duration
* Stress-related motion
#### **Temperature & Physiology**
* Rolling baselines
* Z-score anomalies
* Circadian adjustments
* Temperature–activity correlation
* Trend monitoring
#### **Health Intelligence**
* Fever, heat stress, estrus signals
* Prolonged inactivity alerts
* Sensor malfunction detection
* 0–100 health scoring
#### **Dashboard & Storage**
* Real-time status
* Historical trends
* Alerts timeline
* SQLite database backend
## **Demo**
### Dashboard page

### Alerts Page

### Health analysis page

---
## Productionising a Spam Email Classifier
This project demonstrates how to use Artemis' Planning agent to expand a basic ML pipeline into an informed, production-grade, deployable machine learning system. In this case, we showcase this capability at the example of a spam email detection binary classification project.
## 1. Primary setup
We build a baseline binary classification pipeline using logistic regression to predict if an email should be marked as spam based on word frequency features. The implementation is comprised of the following components:
a) *Dataset*: an open-source [Kaggle dataset](https://www.kaggle.com/datasets/balaka18/email-spam-classification-dataset-csv), containing 5172 emails, each represented by 3,000 numeric features corresponding to word occurence frequencies, along with a binary target variable (1 for spam, 0 for legitimate email)
b) *Data Preparation*: we perform a 80/20 stratified train-test split to preserve class distribution while allocating sufficient data for model evaluation.
c) *Model Training, Validation and Storage*: we train a logistic regresson classifier and assess performance using standard classification metrics: accuracy, recall, and F1-score.
d) *Pipeline orchestration*: we implement main.py as the entry point, incorporating an argument parser to accept the dataset file path as a command-line parameter.
e) *Test Coverage*: we develop unit tests to validate pipeline integrity at two critical stages:
- *Data Loading Module:* Verifies correct schema (feature types and column names), enforcemes of the specified train-test ratio,
stratificates to maintain class balance, and presence of the target variable.
- *Model Training Module:* Validates successful model instantiation and training using synthetic data, confirms that all evaluation metrics were computed and returned, verifies model serialization/deserialization functionality, and ensures prediction outputs conform to expected dimensions and data types.
f) *Project dependencies:* Managed via a pyproject.toml file (pandas >= 2.0.0, numpy>=1.24.0, scikit-learn>=1.3.0). We utilise uv as environment manager.
Below can be found:
### A) A display of the base File tree:
### B) Baseline verification demonstrating the initial project commit hash, build environment setup, and baseline execution workflow:
- **Environment setup**: Installation of the uv package manager and resolution of project dependencies via `uv sync`.
- **Test**: Validation of pipeline integrity through pytest-based unit tests.
- **Pipeline execution**: End-to-end orchestration of the training pipeline with local dataset path as CLI argument.
## 2. Planning
## 2.1. Planning - Requirements Gathering
Regardless of whether you're a junior data scientist or a seasoned ML engineer, our planning agent provides valuable guidance when given any objective, as an instance: "Expand this email classification project".
Once the initial goal is provided, the planning agent generates its own estimate of its scope and proceeds with asking questions to make the final plan more concrete - it starts gathering information with respect to potential user (*2.1.1*) and technical (*2.2.2*) requirements. It first analyses the baseline implementation and intuitively suggests enhancement directions that align with the user's development workflow. For this use case, you can expect these to relate to model experimentation, feature engineering, hyperparameter optimisation and deployment readiness. (see below):
#### *2.1.1. User requirements gathering questions*
Here are the questions the planner asked us in this phase, and the options we selected:
**Q: For the production-ready deployment, what's your target environment?** - Just a simple server to stream predictions real-time (*i.e.* FastAPI/Flask on a single VM)
**Q: For model improvements, what level of sophistication are you looking for?** - Experiment and compare (*i.e.* try multiple algorithms, pick the best one)
**Q: For enhanced text processing, what features would be most valuable?** - *for vectorisation strategy and feature extraction complexity, we prompted the planner to choose a feature preprocessing approach with the data types in mind - it suggested dimensionality reduction using scaling to normalise the feature distributions and satisfy statistical assumptions, as can be seen in the next phase.*
.
**For the streamling prediction API, what format should the input be?** - pre-processed features (*i.e.* API receives numeric feature vector (word counts already computed))
#### *2.2.2. Techncial requirements gathering questions*
After the agent finishes gathering general project implementation information, it moves on to asking techncial requirements questions, being mindful of previous context. For our project, it asked about the API framework we would like to use to return model predictions in the end. It further proceeded with asking about model comparison methods: we chose a winner-based approach (save best model), but were curious to explore its second recommendation, thereby also utilising it as an educational tool. As can be seen, the planner outlined the intended A/B testing approach and proceeded to clarifying scaling approaches for our data preprocessing stage - keeping us on track with a context-and-goal focussed implementation.
## Plan creation
After the question-answering stage finishes, the planning agent provides the task sequence in order - a list of steps to achieve the primary user goal, intelligently factoring in their dependency chain. It then provides a summary of the sequence - this is the plan we obtained:
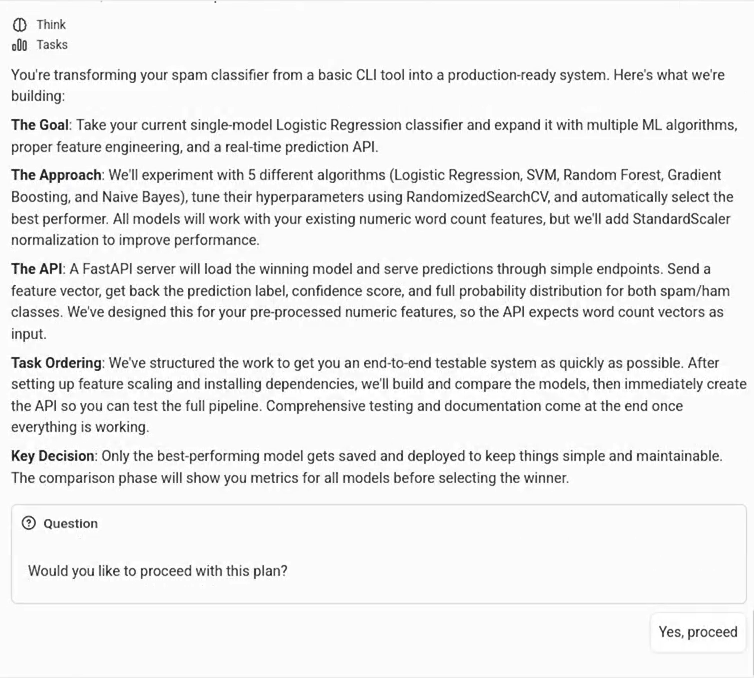
We approved the plan, as we were satisfied with the output. Once approved, the task tree is displayed as a set of tasks on the interface. Users can also choose to approve or modify the plan at any stage, even after task creation. That is, they can prompt the planning agent to add or remove tasks to be executed. The planning process can continue even after the plan has completed (replanning), at which stage the user could choose to completely or partially revisit the plan, which would prompt the agent to come up with a completely different and/or revised task tree.
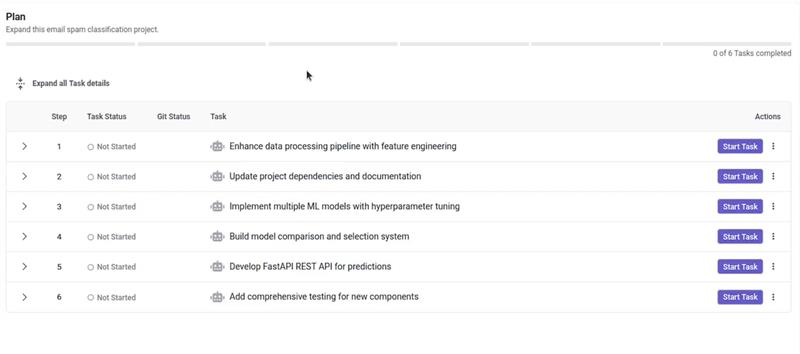
This task sequence represents a step-by-step ML project execution workflow, factoring in all the stages suggested for project expansion:
*1. Feature engineering* - implements feature standardization (ensuring consistent scale across all input variables).
*2. Updating project dependencies and documentation* - crucial for further modelling efforts.
*3. ML model implementation with hyperparameter tuning* - an update to our main script inclusive of our baseline linear model, combined with SVM classifier, a tree-based model (Random Forest), an ensemble model (Gradient Boosting), and a generative learning model (Naiive Bayes) - each with a suitably defined parameter configuration for tuning.
*4. Model comparison and validation* - post-training, model performance is assessed using the standard metrics we had applied in the beginning.
*5. REST API development* - for real-time inference on-demand.
*6. Unit tests* - the planning agent updates our unit test suite to ensure comprehensive coverage of the above-mentioned components.
## Task execution
Within a plan, each task body consists of the following items:
* ***Task Name*** - The name of the task, providing a clear identifier for the specific action or objective.
* ***Task Description*** - The action sequence of the task, as would appear on the PR body if raised.
* ***Prompt*** - A markdown-based instructive sequence to be consumed by a coder agent (in our case - the changeset coder).
* ***Technical Specifications*** - A concretely defined developer blueprint.
* ***Implementation Checklist*** - A list of sequential steps maintaining within-task execution order, as well as task scope clarity.
* ***Success Criteria*** - A set of validation points to essentially constrain the coder to follow best practices for your ML project implementation e.g. 'Test features are transformed using training data statistics (no separate fit)' - this constraint would prevent data leakage. Success criteria in this case also informs file modifications along the plan tree, and guides the creation of further unit tests.
* ***Dependencies*** - Informing environmental constraints, thereby preventing duplicate work.
* ***Files to Read*** - Guide the coder's tool usage, saving resources.
* ***Files to Modify*** - Constrain the coder's work horizon, saving resources and ensuring execution efficacy.
One can review and modify each. Then just click on 'Start Task' for the execution of the above to follow! Users can also add task via the three-dotted menu next to this button.
## Code review and PR creation
Once actioned, verified and finalised, each task becomes a changeset - a (cloud-hosted and platform-managed) versionable pull request. On Artemis, we use a staged changeset review system where users can approve the diff before creating a branch and raising a Pull Request.
Crucially, users can also apply comments on their code: here we chose to additionally enable default scaling, and not leave it optional.
## Final Project display
We successfully completed all implementation tasks and merged changes. The production pipeline (main.py) script trained, tuned, validated and tested every model on our dataset and saved the best by F1 score (GradientBoosting Classifier, *F1=0.9632, Accuracy=0.9787, Precision=0.9664, Recall=0.9632, ROC-AUC=0.9975*) in joblib format. A full trace of the final commit hash, the test log and model performance could be found below:
Artemis' planning multi-agent system successfully expanded our baseline classification pipeline into a deployable, production-grade ML system through informed task orchestration, adhering to best practices at every stage: explicit data leakage prevention via train-only scaler fitting, systematic hyperparameter tuning with grid search (not manual trial-and-error), F1-based model selection accounting for class imbalance and inference-aware REST API design, and more.
## Repository
Complete source code available at [github.com/turintech/spam-classification](https://github.com/turintech/spam-classification)
**Commits:**
- [Baseline](https://github.com/turintech/spam-classification/tree/5af4c9a5ff28d028f74127be7104054ce8d0a78f): Initial logistic regression pipeline
- [Final](https://github.com/turintech/spam-classification/tree/4f020c1f8e1e1c9c434425ab736a6bbcf5697a23): Production system with multi-model comparison and FastAPI
**Quick start:**
```bash
git clone https://github.com/turintech/spam-classification
cd spam-classification
uv sync
pytest
python main.py --data-path data.csv
```
---
## Building a Regression Tool
This guide demonstrates how to leverage the Artemis Planning Agent to create a command-line regression tool for tabular data. Beginning with a basic Python template, we work through an interactive planning session where the agent asks targeted questions to understand our requirements. This collaborative process produces a detailed, actionable plan with well-defined tasks, each including specific deliverables and success criteria. The final product is a fully-featured regression tool that handles data loading, preprocesses the data including imputation, scaling, and encoding to handle both numeric and categorical features, generates predictions, evaluates model performance using multiple metrics, and produces a report with both metrics and visualizations. It also includes complete documentation and tests.
## Project Overview
**Goal:** Create a command-line tool for linear regression on tabular CSV data
**Before:** [Python template](https://github.com/turintech/project-python/tree/acc6e7a) (`acc6e7a`)
**After:** [Complete regression tool](https://github.com/turintech/project-python/tree/ad00452) (`ad00452`)
**Target Users:** Data scientists, analysts, and engineers working with predictive modeling
**Use Cases:**
- Sales and revenue prediction
- Price estimation
- Resource demand prediction
## Planning Process
We began by providing our initial request expressed in a simple prompt: **"I want to build a regression tool."** Through a series of targeted questions, the Artemis Planning Agent guided us to clarify and refine our requirements, exploring both user needs and technical specifications.
**User Requirements:**
- Type of regression? → Linear regression
- Primary interface? → Command-line tool (CLI)
- Data format? → CSV files
- What should the tool produce? → Predictions and a report with visualizations and metrics
- Train model or use pretrained? → Train model and save for predictions
**Technical Requirements:**
- Build from scratch or use library? → Use scikit-learn
- How should CLI commands work? → Separate commands for train and predict
- Report format? → HTML
- Autodetect features/target or user specifies? → User specifies the target column
From these answers, Artemis generated a plan for building a command-line linear regression tool with two main workflows: training a model and using it for predictions. The plan is structured to deliver a fully functional train flow with report generation as quickly as possible.
**The approach:** Start by setting up dependencies (scikit-learn, pandas, matplotlib, jinja2), then build out the core components: create the CLI structure with separate `train` and `predict` subcommands, implement data loading from CSV files, add model training logic, enable model persistence, and generate visualizations and an HTML report.
**After that:** We shift focus to the prediction functionality and complete the `predict` command, which loads the saved model and generates predictions on new data. Finally, we add tests, sample data, and documentation.
The Planning Agent then asked us to confirm if we wanted to proceed with this plan. At this point, we requested adjustments to add basic preprocessing—specifically imputing missing values and scaling numerical features—to handle real-world datasets more robustly. The agent incorporated our feedback and refined the plan.
## Implementation
The Artemis Planning Agent generated a 12-task plan that builds the regression tool incrementally, first completing the train flow and then the prediction flow.
Throughout the implementation, Artemis offers validation after each task. Running these validations helps us verify that everything works as expected. If we identify any issues or areas for improvement, we can provide comments to the agent, which then adjusts the implementation accordingly. This iterative validation process ensures each component functions correctly before moving to the next task.
**1. Add project dependencies to pyproject.toml** - Set up the foundation by adding dependencies (scikit-learn, pandas, matplotlib, jinja2, click) for data loading, model training, and HTML report generation. ([`8957515`](https://github.com/turintech/project-python/commit/8957515))
**2. Create CLI structure with train and predict subcommands** - Built the command-line interface with separate `train` and `predict` commands using Click, defining the core structure for user interaction. ([`b3ff20c`](https://github.com/turintech/project-python/commit/b3ff20c))
**3. Implement data loading and validation** - Created robust CSV data loading with validation to ensure data quality and proper format before processing. ([`1c948f2`](https://github.com/turintech/project-python/commit/1c948f2))
**4. Implement preprocessing pipeline** - Built a preprocessing pipeline handling missing values and scaling features, making the tool robust to real-world data with imputation and standardization. ([`0b6b566`](https://github.com/turintech/project-python/commit/0b6b566))
**5. Implement model training functionality** - Added the core ML pipeline using scikit-learn's LinearRegression, training the model on preprocessed data and computing evaluation metrics. ([`d65b52a`](https://github.com/turintech/project-python/commit/d65b52a))
**6. Implement model persistence (save/load)** - Enabled saving the trained model and preprocessing pipeline to disk for reuse, allowing the predict command to load the pre-trained model. ([`4718e85`](https://github.com/turintech/project-python/commit/4718e85))
**7. Create visualization generation module** - Built visualization capabilities for generating charts. ([`f466ac8`](https://github.com/turintech/project-python/commit/f466ac8))
**8. Implement HTML report generation** - Created HTML report generation using Jinja2 templates, producing a self-contained report with embedded visualizations. ([`9c17354`](https://github.com/turintech/project-python/commit/9c17354))
### First Milestone
After building visualizations and an HTML report, we have a fully functional `train` command that loads CSV data, trains a linear regression model, evaluates performance, generates a scatter plot, residuals plot, and feature importance chart, and produces an HTML report with metrics (R², MSE, RMSE, MAE).
**9. Wire up train subcommand** - Integrated all training components (data loading, preprocessing, model training, evaluation, visualization, reporting) into the train command workflow. ([`a2316b1`](https://github.com/turintech/project-python/commit/a2316b1))
### Second Milestone
Next comes the `predict` command, which loads the trained model, applies it to new data, and generates prediction outputs in CSV. Finally, we'll add tests, sample data, and documentation.
**10. Implement prediction functionality** - Built the prediction logic that loads the saved model and preprocessing pipeline, applies transformations to new data, and generates predictions to CSV. ([`a54baba`](https://github.com/turintech/project-python/commit/a54baba))
**11. Wire up predict subcommand** - Connected the prediction functionality to the CLI, making it straightforward to use. Everything is integrated: `uv run python main.py train --input sample_data.csv --target price --output-model model.joblib --report report.html` and `uv run python main.py predict --model model.joblib --input new_data.csv --output predictions.csv`. ([`1a9da27`](https://github.com/turintech/project-python/commit/1a9da27))
**12. Add basic tests and documentation** - Added tests and documentation to verify functionality and provide user guidance. ([`d95e5e6`](https://github.com/turintech/project-python/commit/d95e5e6))
---
### Final Result
A complete regression tool with training, prediction, and evaluation capabilities. The tool handles data loading, preprocessing, model training with scikit-learn, generates an HTML report with visualizations and metrics, and includes complete documentation and tests.
---
## Building Optimisation Agents with Artemis
How can we build an agent to optimise the performance of software with Artemis? Performance optimisation presents a unique challenge in the landscape of AI-assisted programming. Unlike adding features or fixing bugs, optimisation requires deep understanding of algorithmic complexity, data structures, and system bottlenecks. An agent must not only identify where performance problems exist but also devise creative solutions that maintain correctness while achieving measurable speedups.
The challenge becomes even more complex when we consider the vast search space of possible optimisations. Should the agent focus on algorithmic improvements? Memory efficiency? Parallelisation? Cache optimisation? Each codebase has its own unique characteristics and bottlenecks. What works brilliantly for one project might be irrelevant for another.
This is where intelligent optimisation strategies become crucial. Rather than relying on brute-force approaches or generic heuristics, we need agents that can systematically explore the problem space and evolve their strategies based on what works. An agent's approach to optimisation matters as much as its raw capabilities.
In this post we'll use the SWE-Perf benchmark to show how genetic algorithms can evolve effective optimisation strategies, demonstrating that systematic prompt engineering through Artemis Intelligence can unlock significant performance gains even with a single language model.
## What is SWE-Perf?
SWE-Perf [He et al., 2024] is a benchmark that evaluates AI agents on 140 performance optimisation instances across 9 major open-source Python projects (including astropy, requests, scikit-learn, and others). Each instance presents a specific performance bottleneck with pre-defined test cases, challenging agents to generate git patches that improve runtime efficiency while maintaining correctness.
## Our Approach
### Agent Framework
We implemented mini-SWE-agent, a lightweight agent framework designed for autonomous coding tasks. Mini-SWE-agent is a small agent framework that uses an LLM to generate and execute shell actions to autonomously do coding tasks. It solves problems by asking the model what to do next, running that instruction (for example, reading/editing files, running tests), looking at what happened, and repeating steps. We selected this framework because it offers:
- Straightforward integration with SWE-Perf benchmark workflow
- Uses only one base LLM, avoiding expensive optimisation costs for large real-world projects
- Standardised APIs to be used with the available LLM modules implemented in our company
### Base LLM
We used Claude 3.5 Sonnet as our single language model, chosen for its strong reasoning capabilities and code understanding.
### Agent Optimisation Strategy
We employed zero-shot optimisation with Artemis Intelligence, where Artemis uses genetic algorithms to iteratively explore and refine agent prompt configurations. This approach allows us to:
- Automatically discover effective prompt patterns without manual tuning
- Evolve optimisation strategies through iterative improvement
- Balance cost vs performance in agent optimisation
## Optimised vs Original Agent
The optimised agent incorporates several strategic improvements over the original agent:
1. **Enhanced Performance Focus**: The optimised agent emphasises bold, high-impact algorithmic optimisations rather than incremental tweaks, with explicit instructions to target the "single most critical performance bottleneck" and implement "substantial code changes within one function or loop."
2. **Improved Optimisation Strategy**: The optimised agent provides detailed guidance on algorithmic improvements (reducing time complexity, eliminating unnecessary loops), data structure upgrades (using hash tables, sets), and computation consolidation (caching, hoisting).
3. **Better Constraint Handling**: The optimised agent includes more sophisticated anti-gaming rules and clearer boundaries between what constitutes "surgical" file editing versus "bold" conceptual changes.
4. **Streamlined Workflow**: The optimised agent simplifies the submission process and provides clearer step-by-step optimisation methodology with specific performance analysis checklists.
## Results
Our optimised agent delivered substantial project-level performance improvements, even when the overall benchmark averages appeared modest.
### Notable Project-Level Successes
**psf/requests (2 instances)**: Our most successful optimisation target
- Original: 36.1% performance speedup
- Optimised: 43.3% performance speedup
- Artemis Intelligence Gain: +20% relative improvement
**scikit-learn/scikit-learn (32 instances)**: Consistent improvements
- Original: 3.5% performance speedup
- Optimised: 4.5% performance speedup
- Artemis Intelligence Gain: +29% relative improvement
**astropy/astropy (12 instances)**: Steady performance gains
- Original: 2.9% performance speedup
- Optimised: 4.7% performance speedup
- Artemis Intelligence Gain: +62% relative improvement
These results highlight that the optimised agent isn’t just nudging averages — it’s unlocking meaningful speedups in major, widely used projects, where even a few percentage points can have real-world impact.
### Full-Scale Benchmark Results (140 Instances)
Across the entire SWE-Perf benchmark:
- **Original Agent**: 5.0% average performance speedup (92.1% apply rate, 87.9% correctness)
- **Optimised Agent**: 5.5% average performance speedup (92.1% apply rate, 87.9% correctness)
- **Artemis Intelligence Gain**: 10% relative improvement over the original agent
## Case Study: astropy/astropy Optimisation
The astropy/astropy instance demonstrates how our optimised agent achieved substantial performance gains through comprehensive algorithmic improvements. The agent identified and optimised the `report_diff_values()` function in `astropy/utils/diff.py`, which is critical for efficient array and string comparison operations.
### Original Code

### Optimised Code

### Key Optimisations
- **Early identity check**: Added `if a is b: return True` to skip processing for identical objects
- **Cached string operations**: Replaced `fixed_width_indent()` calls with cached `_get_indent()` function
- **Optimized array dtypes**: Pre-convert arrays to float64/int64 for faster NumPy operations
- **Batch processing**: Process large arrays (>1M elements) in chunks to prevent memory overflow
- **Vectorized comparisons**: Use specialized `_fast_array_compare()` for different data types
- **Memory efficiency**: Use `np.ascontiguousarray()` for better cache performance
## Conclusion
The agent optimisation case study demonstrates how targeted, systematic approaches often outperform brute-force optimisation, especially when combined with evolutionary prompt engineering and domain-specific knowledge. By using Artemis Intelligence to evolve our agent's prompting strategy, we achieved substantial project-level gains in libraries like scikit-learn, requests, and astropy, where improvements of 20–60% relative speedup matter to real-world users.
These standout results show that smaller, focused models with optimised instructions can compete effectively with larger, more expensive alternatives in production environments [Belcak et al., 2024]. Even when overall averages appear incremental, the project-level impact reveals the true value of agentic optimisation with Artemis.
## References
Belcak, P., Heinrich, G., Diao, S., Fu, Y., Dong, X., Muralidharan, S., Lin, Y. C., & Molchanov, P. (2024). "Small Language Models are the Future of Agentic AI." arXiv preprint arXiv:2406.02153.
He, X., Liu, Q., Du, M., Yan, L., Fan, Z., Huang, Y., Yuan, Z., & Ma, Z. (2024). "SWE-Perf: Can Language Models Optimize Code Performance on Real-World Repositories?" arXiv preprint arXiv:2407.12415.
---
## Evolutionary Dashboard Development
Here we demonstrate how a data scientist or a business analyst can use Artemis Intelligence to rapidly generate dashboard apps and enhance either a pre-existing ML project or a pipeline, to create a dashboard on-the-go. The utility of using our genetic algorithm for quick dashboard creation is manyfold:
- Artemis directly considers your project environment, making it ideal for dashboards considering multiple architectural components of a repository.
- A goal-based optimisation of each variant for KPIs and hypotheses via its fitness function.
- The opportunity to tweak various components of your dashboard post-generation.
We chose [Streamlit](https://docs.streamlit.io/) as our foundation for rapid dashboard generation. Its lightweight, Python‑native design and clear execution model make it easy to build and iterate on interactive components. However, Artemis is framework‑agnostic - if you prefer React or another UI stack, do not hesitate to use Artemis with your own setup!
## 1. Dashboard generation for your finished ML project.
Data scientists and business analysts frequently need to create dashboards to effectively communicate their analysis results with various audiences. To demonstrate this workflow, we have set up a typical data science repository with a clear separation of concerns, including:
- A data directory for storing datasets.
- Notebooks for data processing and analysis.
- A python script for model execution and evaluation.
- Project configuration files for dependency management and reproducibility.
To prepare the Artemis environment for our setup, we just added the following files:
- an empty streamlit_app.py file (this is the file we will evolve with Artemis)
- a python script which loads our data and prints the output to be consumed by our runner (see below)

## 2. Project Setup
### 2.1 Indexing
Before generating the dashboard, index your project to enable Artemis to build a semantic understanding of your project's code (see [Indexing](../../features/code-indexing.md)).
### 2.2 Project Build
Set up and activate an instance of your [Artemis runner](../../features/artemis-runner.md).
- We run the script we created for our data summary within our compilation command. This command is only ran once and ensures our runner receives context to our dataset features - their types and properties. Tailor the data summary to the logs in whichever way you wish Artemis to understand it for the dashboard you will be working with.
- We provide the path to our streamlit interpreter and run our streamlit instance as a benchmark command. That way we ensure that our runner validates each instance created for our app. You can experiment with the control you have over your dashboard [generation config](https://docs.streamlit.io/develop/api-reference/configuration/config.toml), if you are also using Streamlit.

## 3. Creating Your Dashboard
Once everything is set up, you can start creating your dashboard with Artemis!
### 3.1 Create a Code Snippet From Your Empty File

### 3.2 Provide Artemis Intelligence With Your Goal
When you supply your prompt to the genetic algorithm for dashboard creation, it effectively serves as a global validation objective, defining the KPI by which candidate dashboard variants are evaluated, scored and selected.
For our project, we built models to forecast the year-over-year quarterly change in the labour cost index, as we supplied our model with other macroeconomic variables. There, we wanted to further understand and visualise the relationship between the harmonised index of consumer prices and the labour cost index, and how it varies across countries. Here we also provided our python script as context to the Artemis.

After writing up your task, enable the execution commands we specified above within your configuration settings (right). From there, you can also control the number of dashboard versions Artemis would generate for you. Once you're done, click 'generate'!

## 4. Output
Once your recommendation trial has finished, you can download the top-ranked dashboard code variant by downloading the project entirely:

Then serve it locally via Streamlit:

This is how the initial interface of our LCI forecast dashboard looked like - Artemis Intelligence translated our high-level prompt into quantifiable metrics and optimization objectives that guided its genetic algorithm. By leveraging our repository context through indexing and the provided script, Artemis gained deep understanding of our data preprocessing approach (we generated lags and had generated a lead on our target), and this analysis it integrated into the cross-correlation plot! Through evolving a single empty file, it generated dashboard variants that progressively improved on these metrics - evaluating components like visualization clarity, data relationship exploration capabilities, and cross-country comparison features - ready to display!

## 5. Dashboard Generation with the EvoML Pipeline
If you have your ML project's pipeline on hand or if you, like us, are using EvoML to automate your data science workflow, you can also generate insightful dashboards with Artemis intelligence directly from your chosen model's pipeline, to aid model governance control, for instance. This is an example of how we have produced one such dashboard to demonstrate whether our model is compliant with both the EU AI Act and SR 11-7/OCC 2011-12 model risk management mandate. Reproducing this is easy:
### 5.1 Download Your Chosen Model's Pipeline
Download your chosen model's pipeline by clicking the 'Model usage' tab on EvoML. From there, click on **Download code**.

### 5.2 Extract and Configure Pipeline Environment
Extract the pipeline source code to your local development environment.
- Create a new empty Streamlit file (.py) which will serve as the template for Artemis's evolutionary dashboard generation process.
- Generate a comprehensive pipeline architecture documentation (Artemis.md) that defines the [functional purpose of each component](https://docs.evoml.ai/deploy-models/pipeline/structure). Tailor this document to your own purposes, you could describe the following:
- Detailed component topology and interactions
- Infrastructure deployment targets (e.g. AWS, GCP, on-prem)
- Data flow specifications
- Migration requirements and timelines
- Integration touchpoints with external systems
- Security and compliance considerations
- Update the pipeline's dependency configuration in pyproject.toml to include Streamlit and any additional visualization or data processing libraries required for your dashboard implementation. Then compress again.
### 5.3 Upload Your Project File
Upload your .zip file within Artemis. Our project looked like this:

### 5.4 Index Your Project
Index your project. This will help Artemis form a high-dimensional representation of your codebase.
### 5.5 Start Prompting
This is the prompt we supplied Artemis with when generating our compliance dashboard. We generated 15 versions with Artemis intelligence, and did not use a runner to compile our code during the process, but you can do so to obtain more control over version generations:

### 5.6 View Final Dashboard
This is the landing page of the best version generated by Artemis:

This dashboard essentially represented a compliance-readiness snapshot of our ML pipeline, aggregating pipeline structure evidence into eight pillars and an overview of all, aligned to EU AI Act obligations.
Since model governance requirements vary across organizations, you can continue refining Artemis's generated versions to better match your specific compliance needs, by clicking on the **+** button on the right handside of the version template you like.
## 6. Dynamic Dashboard Evolution
Artemis is not only a tool that can be used to build and customise dashboards, but can also be used to further optimise their components, to meet specific KPIs. As a final example, we describe a real-world use case that demonstrates this capability. Here, our evolutionary algorithm acts as a classifier, assigning instant novel categories to an auto-email tagging system, and will aim at increasing a fitness score, representative of the overall alignment between emails and the tags generated by Artemis (see score calculation below).
### 6.1 Prerequisites
Your OPENAI API KEY.
### 6.2 Project Setup
For this project, we uploaded a Streamlit dashboarding template, with the following crucial components for reproducibility:
- app.py – the entry point of our Streamlit app.
- ./pages – a directory containing Python scripts that Streamlit automatically renders as separate pages in the multi-page application. **We placed the script we will be evolving within this directory**
- emails.csv – a simulated customer support e-mail dataset, consisting of 200 samples, each represented by features such as subject line, the email body content, the tag, the customer tier, etc.
- data_structure.py – a script to print a summary of our dataframe’s column characteristics to Artemis for context (see first example above).
- embeddings.py – contains a wrapper around the OpenAI model and initializes a vector database storage (ChromaDB).
- llm.py – a wrapper to access the OpenAI Software development kit and thereby enable API calls. We used OpenaAI’s [text embedding-3-small](https://openai.com/index/new-embedding-models-and-api-updates/) to generate embeddings for our clustering/unsupervised classification task.
Standard project config files.

### 6.3 Project Build
To compile and validate the solution variants generated by Artemis, we set up our project build in the following way:

This set-up is similar to the one utilised for first dashboard generation demo. We run this script to aid Artemis in obtaining context for our dataframe. We invoke the Streamlit runtime, which executes our script and serves the application in a browser each time we run a validation of the code, as we also provide the path to our environment file, containing our OPENAI credentials locally.

This snapshot represents the initial state of the page to be evolved by Artemis, as generated by the script we would be evolving. Here, we initialized a baseline set of candidate input tags. These are the tags Artemis would be asked to dynamically assign, when we run our recommendation trial. When the user triggers the Generate Taxonomy process, these tags are embedded and matched by similarity to the tag list within the email dataset, enabling automated assignment within a dataframe.
The assignment threshold τ ∈ [0,1] is a similarity cutoff parameter that determines when an e-mail should be assigned to a candidate tag versus being classified or unassigned as 'other'. We set τ to 0.35 to ensure semantic flexibility and high recall for tag assignment.
### 6.4 Script Evolution
The script behind this Streamlit interface is the subject of evolution. It implements a sequential data-processing pipeline: it first loads the dataset, then performs feature engineering by concatenating the e-mail subject and body into a unified text column. The concatenated text is subsequently vectorised via our embeddings wrapper module, which interfaces with OpenAI's embedding model. In parallel, the script generates embeddings for the candidate tags. We then compute cosine similarity as the dot product of the resulting (normalised) vectors. This similarity score constitutes the basis for the fitness function that Artemis optimises:
$Fitness = avg\\_max\\_similarity - 0.3 \\times redundancy - 0.3 \\times unassigned\\_rate$
Where:
- avg_max_similarity - the average across all 200 e-mails' individual maximum similarity score across all tags.
- redundancy - the average pairwise similarity between tags.
- unassigned_rate - Fraction of e-mails where max_similarity < τ (threshold), penalising tag sets that leave many e-mails unclassified.
The key mechanism in this setup is that, during each validation, the metric values for this function are printed to the logs. Our genetic algorithm's objective was therefore to increase this fitness score by dynamically assigning novel e-mail tags — and this is exactly what we asked it to do:

To initiate the evolutionary process, we simply triggered the taxonomy evaluation function through the dashboard interface, each time a variant was validated by Artemis, which calculated the fitness scores and drove the tag assignment optimisation.
### 6.5 Results
Artemis successfully optimized the email classification system, improving the fitness score from -0.055 to 0.400, by creating meaningful, granular tags while ensuring comprehensive email coverage, and provided a highly efficient solution for automated email categorization.

---
## Agentic Chat
Use this guide to explore your codebase using Artemis Agentic Chat, powered by RAG (Retrieval-Augmented Generation) and the on-device Qwen 3 4B model. Ask questions about your project and receive answers with references to the specific files used in the response.
## Prerequisites
- Artemis is installed on a high-performance Intel® laptop with local GPUs (see [Deployment Options](../../deployment/deployment-options.md)).
- All large language models run locally (this example uses the Qwen 3 4B model).
- Internet access is optional; all processing runs directly on your local hardware.
## Outline
This guide covers the following steps:
- **Step 1:** [Import a Local Project](#step-1-import-a-local-project): Set up your project in Artemis
- **Step 2:** [Index the Project](#step-2-index-the-project): Enable codebase indexing for RAG-powered search
- **Step 3:** [Open Agentic Chat](#step-3-open-agentic-chat): Access the chat interface to explore your codebase
- **Step 4:** [Explore Your Codebase](#step-4-explore-your-codebase): Ask questions, search for similar code patterns, and receive answers with file references
## Workflow
### Step 1: Import a Local Project
Select one of the following options to import your code into Artemis:
1. **Import a sample project**:
- Go to `Projects` and click `Import Project` to use a pre-existing sample (see Figure 1).
- Choose a sample project (for example, Sample Python Project) and click `Import` (see Figure 2). If the import isn't working, disable `Use Git Credentials` or [set up git credentials](../../project-setup/git-keys.md).
- The project appears in your Projects list. Open it to proceed (see Figure 3).
2. **Upload a project zip file**:
- Go to `Projects` and click `New Project`.
- Click `Upload a zip file with your code` and select your zip file.
- Once uploaded, open the project (see Figure 3).
3. **Import an existing project from GitHub**:
- Go to `Projects` and click `New Project`.
- Select an existing project from your GitHub repository. For details on setting up git credentials, see the [project setup guide](../../project-setup/import-codebase.md).
- Once imported, open the project (see Figure 3).
4. **Create a new project with planning**:
- Go to `Projects` and click `Plan New Repo` to start a new project using the Planning Agent (BETA). For more details, see the [planning guide](./planning.md).
- Once the project is created, open it (see Figure 3).
Figure 1: Select a sample project to import
Figure 2: Sample project ready to import
Figure 3: Imported project ready for scanning
### Step 2: Index the Project
1. Navigate to `Optimise > Tasks` and click `Index` to start indexing your project (see Figure 2).
2. Select the files or directories you want to index (see Figure 3). You can choose specific files or index the entire repository.
3. The indexing process begins and analyzes your codebase (see Figure 4). During indexing, Artemis:
- Analyzes your codebase structure
- Extracts code patterns, functions, classes, and documentation
- Creates embeddings for code and documents using semantic analysis
- Creates a searchable semantic index that enables RAG-powered chat responses
4. Wait for the indexing process to complete. Progress is displayed in the interface. Larger projects may take several minutes to index fully.
5. Once indexing is complete, the chat can:
- Search across all indexed files using RAG-based approaches
- Find similar code patterns using semantic embeddings
- Provide accurate answers with references to specific files
- Query both code and documentation with improved precision
**Note:** The index is stored locally on your machine and remains available for future chat sessions.
Figure 2: Click Index to start indexing
Figure 3: Select files to index
Figure 4: Repository indexing in progress
### Step 3: Open Agentic Chat
1. Once indexing is complete, open the chat interface (see Figure 5). You can access the chat from the `Optimise > Tasks` view or from the main navigation.
2. Select `Artemis Search` from the chat options to enable RAG-powered search across your indexed codebase (see Figure 6).
3. Click the project context icon to select which projects to include in your chat session (see Figure 7).
4. In the popup dialog that opens, select one or more projects to include in the chat context (see Figure 8). This allows you to search across multiple indexed projects simultaneously.
5. The chat interface is now ready to use. The RAG system uses your local language model (for example, Qwen 3 4B) to process your questions and search the indexed codebase. All chat interactions remain on your local machine; no code or questions are sent to external servers.
Figure 5: Open agentic chat interface
Figure 6: Select Artemis Search option
Figure 7: Project context icon for selecting projects
Figure 8: Select multiple projects popup
### Step 4: Explore Your Codebase
1. Ask questions about your codebase. Example questions:
- "How does authentication work in this project?"
- "Where is the database connection configured?"
- "What are the main components of this application?"
- "Explain the error handling mechanism"
- "Show me all the API endpoints"
- "How is logging implemented?"
2. Review the answer and file references. Each response includes references to the specific files used. Click on any file reference to navigate directly to the relevant code section in your project (see Figure 9).
3. Ask follow-up questions to explore specific areas in more detail. The chat maintains context from previous questions within the same conversation, allowing for natural, multi-turn discussions.
Figure 9: Chat response with file references
## Next Steps
- Learn more about [Code Indexing](../../features/code-indexing.md) and how it enhances AI capabilities.
- Use [Code Audit](./audit.md) to identify and fix code quality issues.
- Explore [Standalone Optimisation](./optimisation.md) to improve code performance.
- Use the [Planning Agent](./planning.md) for strategic feature development.
---
## Code Audit
Follow this workflow to run comprehensive code audits on a locally deployed Artemis instance that uses the on-device Qwen 3 4B model for AI assistance.
## Prerequisites
Artemis is installed on a high-performance Intel® laptop with local GPU acceleration (see [Deployment Options](../../deployment/deployment-options.md)). All large language models are running locally (this example uses Qwen 3 4B model). Internet access is optional; audit scans run entirely offline.
## Outline
This guide covers the following steps:
**Step 1:** [Import and Open the Project](#step-1-import-and-open-the-project): Set up your project for scanning.
**Step 2:** [Register the Local Runner](#step-2-register-the-local-runner): Configure the runner for validations and benchmarks.
**Step 3:** [Review and Configure Rules](#step-3-review-and-configure-rules): Adjust rule importance levels and enable/disable rules.
**Step 4:** [Add Custom Rules with Local AI Assistance](#step-4-add-custom-rules-with-local-ai-assistance): Create custom rules using the local Qwen 3 4B model.
**Step 5:** [Run the Analysis](#step-5-run-the-analysis): Trigger scan and select files to analyze.
**Step 6:** [Review Findings](#step-6-review-findings): Examine identified issues by category and severity.
**Step 7:** [Prioritise with AI (BETA)](#step-7-prioritise-with-ai-beta): Use AI to rank issues by impact and effort.
**Step 8:** [Code Audit Findings](#step-8-code-audit-findings): Choose remediation path for identified issues.
**Step 9:** [Fix as Background Task](#step-9-fix-as-background-task): Queue automated fixes using background tasks.
**Step 10:** [Fix as Planning Task](#step-10-fix-as-planning-task): Use Planning Agent to design resolution strategies.
**Step 11:** [Fix as Target](#step-11-fix-as-target): Send issues to Standalone Optimisation workflow using Artemis Intelligence.
**Step 12:** [Integrate Optimisations](#step-12-integrate-optimisations): Export, download, or create a pull request for your optimisations.
## Workflow
### Step 1: Import and Open the Project
Select one of the following options to add code to Artemis:
1. **Import a sample project**:
- Click `Import Project` to use a pre-existing sample (see Figure 1).
- Select a project and click `Import` (see Figure 2). If the import isn't working, [set up git credentials](../../project-setup/git-keys.md) or disable `Use Git Credentials`.
- Open the imported project (see Figure 3).
2. **Upload a project zip file**:
- Click `New Project`.
- Click `Upload a zip file with your code`.
- Open the uploaded project (see Figure 3).
3. **Import an existing project from GitHub**:
- Click `New Project`.
- Select an existing project from your GitHub repository. For details on setting up git credentials, see the [project setup guide](../../project-setup/import-codebase.md).
- Open the imported project (see Figure 3).
4. **Create a new project with planning**:
- Click `Plan New Repo` to start a completely new project using the planner (BETA). For more details, see the [planning guide](./planning.md).
- Once the project is created, open it (see Figure 3).
Figure 1: Select a sample project to import
Figure 2: Sample project ready to import
Figure 3: Imported project ready for scanning
### Step 2: Register the Local Runner
**Note:** This step involves registering the Artemis Runner on the same machine to execute validations and benchmarks.
Artemis uses this runner to execute tests, benchmarks, and Artemis Intelligence workflows.
1. Open `Settings > Build` (see Figure 4).
2. Select the operating system that matches your host environment (Windows in this use case).
3. Copy the installation command displayed on the page and paste it into Windows PowerShell (see Figures 5 and 6). This command downloads and installs the runner on your local machine.
4. Start the runner using the command shown in Figure 7. When prompted in PowerShell, provide:
- A runner name (any free text identifier)
- Your Artemis credentials (username and password) to authenticate the runner
A successfully running runner appears as shown in Figure 8.
5. Once the runner is running, return to the `Settings > Build` page in Artemis. Select the runner name from the available runners list to link it to your project.
Figure 4: Copy the runner install command
Figure 5: Runner installation command in PowerShell
Figure 6: Runner installing
Figure 7: Start runner
Figure 8: Runner is online and ready
### Step 3: Review and Configure Rules
1. The rules table displays built-in rules grouped by category (e.g., Security, Best Practices, Performance, and more). If necessary:
- Adjust importance levels to match your local policies by clicking on a rule and selecting the importance level (see Figure 9).
- Enable or disable rules depending on the target project's needs.
- Add a new custom rule (see Step 4).
Figure 9: Select and weight scan rules
### Step 4: Add Custom Rules with Local AI Assistance
1. Click `Add Rule`.
2. Provide the rule name and a description of the rule. Optionally, click `Generate with AI` to help you write the description using the local Qwen 3 4B model (see Figure 10).
3. Update the importance level and decide whether you want to enable the rule by default.
4. Click `Create Rule`.
Figure 10: Create a new scan rule with AI assistance
### Step 5: Run the Analysis
1. Start scan by clicking `Run Analysis` (see Figure 11).
2. When prompted (see Figure 12), confirm the list of files or directories to include. Artemis processes the scan locally and streams progress in the Scan tab.
Figure 11: Click Run Analysis
Figure 12: Select files for analysis
### Step 6: Review Findings
1. Issues are grouped by category and severity (Critical, High, Medium, Low) (see Figure 13).
2. Each issue includes:
- A description of the issue
- The file path and line number where the issue was found
- Remediation guidance and suggested fixes
3. Use filters to focus on specific severities or categories. You can also sort by severity, file, or rule type to help prioritize your review.
4. Click on an issue to view detailed information and available remediation options.
Figure 13: Run code audit analysis
### Step 7: Prioritise with AI (BETA)
1. Click `AI Prioritisation` to activate AI-powered issue ranking.
2. Artemis leverages the local LLM to analyze each issue and rank them based on:
- **Impact**: How critical the issue is to your application's security, performance, or functionality
- **Estimated effort**: How much time and complexity is required to fix the issue
3. Review the prioritised list. Issues are reordered with the most impactful and easiest-to-fix issues at the top.
4. Use this prioritised list to decide which issues to tackle first, maximizing your remediation efficiency.
### Step 8: Code Audit Findings
Choose the remediation path that fits your workflow:
1. **Fix as Background Task**: See Step 9.
2. **Fix as Planning Task**: See Step 10.
3. **Fix as Target**: See Step 11.
### Step 9: Fix as Background Task
1. Select an issue and click `Fix` to queue an automated fix (see Figure 14). Artemis runs the fix as a background task.
2. Once the background task is complete, a draft fix will be available (see Figure 15).
3. Select the generated draft and review the changes. **Note:** You can interact with the chat to edit the draft or to understand what changes were made and why.
4. Click `Create Pull Request` to integrate the fix into your repository.
Figure 14: Fix issue as background task
Figure 15: Fix draft ready
### Step 10: Fix as Planning Task
1. Select the `Planning` option to open the issue in the planning workspace (see Figure 16).
2. Collaborate with the Planning Agent (human-in-the-loop) to design a resolution strategy (see Figure 17). The Planning Agent will ask questions and generate a structured plan to address the issue.
3. Review the generated plan and approve or request revisions. Once the plan is executed, the fix will be complete (see Figure 18).
4. The fix is automatically published to your Git repository.
Figure 16: Select fix using planning agent
Figure 17: Planning agent running
Figure 18: Fix complete
### Step 11: Fix as Target
1. Click `Target` to send the issue directly into the Standalone Optimisation workflow (see Figure 19). This opens the `Generate new version` dialog.
2. Select the mode `Artemis Intelligence` (see Figure 20). **Note:** You can also select `LLM` for a one-shot fix.
3. Configure the version settings in the dialog (see Figure 20):
- Update the `Prompt`. We provide a default prompt, but incorporating domain knowledge will help guide the optimisation.
- Select `Models`. Multiple models can be applied for a single optimisation using `Artemis Intelligence`.
4. Click `Configuration` (located in the top left corner within the Artemis Intelligence option; see Figure 21). Configure the following options:
- Select **Executable Code** and **Runner**. These can be updated in project Settings.
- Specify **Score criteria**. Multiple criteria can be selected, and the optimisation will be treated as a multi-objective optimisation.
- **Note:**
- You can update the Score Prompt Name and Prompt Text by clicking **View**.
- You can also add custom score criteria by clicking **Define New**.
5. Click the back arrow (top left corner of Figure 21) to return to the version generation screen. Once you are satisfied with the Artemis Intelligence settings, click `Generate Versions` to start the Artemis Intelligence engine.
6. Optimisation versions will start being generated and populated (see Figure 22). Each row represents one optimisation version. Click a version to view code differences. Options are available on the right, including an agentic chat.
7. Each optimised code version displays the following information and options (see Figure 23):
- **Version ID**: For example, `A-gen1pop0-f72ee` identifies the code version.
- **Change indicators**: Green `+17` and red `-1` show that 17 lines were added and 1 line was removed.
- **Three vertical dots**: Click to access further actions (see Step 12).
- **`+` icon**: Generate new optimisations using LLMs or Artemis Intelligence, starting from this code version.
- **Scale icon**: Perform scoring. Click it to see a relative score comparing the version to the original code.
- **Play icon**: Validate the snippet.
- **Score Values**: These are relative scores. The first value is an average of all scores, and the subsequent values are scores for individual objectives (for example, Compatibility, Equivalence, and Performance).
8. Click `Validate` to run tests or compile steps through the registered runner (see Figure 25).
9. Choose integration options (see Step 12).
Figure 19: Add target from scan issue
Figure 20: Use Artemis Intelligence to optimise target
Figure 21: Specify configuration for Artemis Intelligence
Figure 22: Artemis Intelligence generating versions
Figure 23: Review generated optimisation versions
Figure 24: One Code Version
Figure 25: Run validations on optimised code
### Step 12: Integrate Optimisations
1. Click the options icon (three vertical dots) to choose your next steps (see Figure 26):
- Download the specific optimised file
- Download the project with the optimised file in place
- Create a changeset (which allows you to create a pull request on Git)
- Delete the file
2. If you choose to create a changeset (pull request), follow the prompts to generate a pull request that integrates your optimisations into your Git repository.
Figure 26: Version options menu
## Next Steps
- Learn more about [Scan rules](../../scan/rules.md) and best practices for structuring policies
- Explore [Issue management](../../scan/issues.md) to triage and track remediation work
- Review the [Scan overview](../../scan/overview.md) for additional auditing capabilities
- After fixing issues, continue with [Standalone Optimisation](./optimisation.md) to further improve code quality
- Use the [Planning Agent](./planning.md) for strategic feature development
- Explore your codebase with [Agentic Chat](./agentic-chat.md) to understand project structure and find related code
---
## Standalone Optimisation
Use this guide to run the Standalone Optimisation workflow on a locally deployed instance of Artemis that is powered by an on-device Qwen 3 4B model.
## Prerequisites
Artemis is installed on a high-performance Intel® laptop with local GPUs (see [Deployment Options](../../deployment/deployment-options.md)). All large language models are running locally (this example uses Qwen 3 4B model). Internet access is optional; optimisation runs directly on your hardware.
## Outline
This guide covers the following steps:
**Step 1:** [Import a Local Project](#step-1-import-a-local-project): Set up your project in Artemis.
**Step 2:** [Register the Local Runner](#step-2-register-the-local-runner): Configure the runner for validations and benchmarks.
**Step 3:** [Enter Standalone Optimisation](#step-3-enter-standalone-optimisation): Navigate to the optimisation workspace.
**Step 4:** [Select Files and Create Targets](#step-4-select-files-and-create-targets): Choose code to optimise.
**Step 5:** [Review Targets](#step-5-review-targets): Review generated targets and choose optimisation approach.
**Step 6:** [Score Code Blocks](#step-6-score-code-blocks): Evaluate code quality metrics.
**Step 7:** [Explore with Contextual Chat](#step-7-explore-with-contextual-chat): Interact with your code using AI.
**Step 8:** [Generate One-Shot Code Updates](#step-8-generate-one-shot-code-updates): Create quick code improvements.
**Step 9:** [Produce Multi-Version Optimisations with Artemis Intelligence](#step-9-produce-multi-version-optimisations-with-artemis-intelligence): Generate and compare multiple optimisation candidates.
**Step 10:** [Integrate Optimisations](#step-10-integrate-optimisations): Export, download, or create a pull request for your optimisations.
## Workflow
### Step 1: Import a Local Project
**Note:** This step involves importing a sample project (for example, Sample Python Project) or your own repository into Artemis.
Select one of the following options to add code to Artemis:
1. **Import a sample project**:
- Click `Import Project` to use a pre-existing sample (see Figure 1).
- Select a project and click `Import` (see Figure 2). If the import isn't working, [set up git credentials](../../project-setup/git-keys.md) or disable `Use Git Credentials`.
- Open the imported project (see Figure 3).
2. **Upload a project zip file**:
- Click `New Project`.
- Click `Upload a zip file with your code`.
- Open the uploaded project (see Figure 3).
3. **Import an existing project from GitHub**:
- Click `New Project`.
- Select an existing project from your GitHub repository. For details on setting up git credentials, see the [project setup guide](../../project-setup/import-codebase.md).
- Open the imported project (see Figure 3).
4. **Create a new project with planning**:
- Click `Plan New Repo` to start a completely new project using the planner (BETA). For more details, see the [planning guide](./planning.md).
- Once the project is created, open it (see Figure 3).
Figure 1: Select a sample project to import
Figure 2: Sample project ready to import
Figure 3: Imported project ready for optimisation
### Step 2: Register the Local Runner
**Note:** This step involves registering the Artemis Runner on the same machine to execute validations and benchmarks.
Artemis uses this runner to execute tests, benchmarks, and Artemis Intelligence workflows.
1. Open `Settings > Build` (see Figure 4).
2. Select the operating system that matches your host environment (Windows in this use case).
3. Copy the installation command displayed on the page and paste it into Windows PowerShell (see Figures 5 and 6). This command downloads and installs the runner on your local machine.
4. Start the runner using the command shown in Figure 7. When prompted in PowerShell, provide:
- A runner name (any free text identifier)
- Your Artemis credentials (username and password) to authenticate the runner
A successfully running runner appears as shown in Figure 8.
5. Once the runner is running, return to the `Settings > Build` page in Artemis. Select the runner name from the available runners list to link it to your project.
Figure 4: Copy the runner install command
Figure 5: Runner installation command in PowerShell
Figure 6: Runner installing
Figure 7: Start runner
Figure 8: Runner is online and ready
### Step 3: Enter Standalone Optimisation
1. From `Projects`, click the imported project.
2. Select `Optimise > Files` (see Figure 9). This view lists targets, issues surfaced from scans, and existing standalone tasks.
Figure 9: Open Optimise to work on local targets
### Step 4: Select Files and Create Targets
1. In `File Selection`, highlight the files you want to optimise and click `Continue` (see Figure 10).
2. Use filters (for example, File Type) to narrow the focus (see Figure 11), then click `Add Target`.
3. Artemis displays the targets ready for optimisation (see Figure 12).
Figure 10: Choose files for optimisation
Figure 11: Filter files before adding as targets
Figure 12: Targets ready for optimisation
### Step 5: Review Targets
1. Review the generated targets in the list. Each target represents a file, function, or code block that can be optimised.
2. Decide which targets to prioritise. Use the following methods to identify which targets need optimisation:
- **Scoring** (see Step 6): Evaluate code quality metrics to identify targets that need improvement. **Note:** You need to run scoring from Step 6 before you can use scoring results to filter targets.
- **Contextual chat** (see Step 7): Ask questions about the code to understand its purpose and identify optimisation opportunities.
3. Choose your optimisation approach:
- **One-shot LLM** (see Step 8): Use for quick, direct code improvements on individual snippets.
- **Artemis Intelligence** (see Step 9): Use for complex optimisations requiring multiple candidate versions and validation.
### Step 6: Score Code Blocks
Scores help you identify code target candidates for optimisation. You can score individual targets or all targets at once.
1. Choose which targets to score (see Figure 13):
- **Individual target**: Click the `Score` icon below the specific target you want to score.
- **All targets**: Click the score medal icon next to the "Score" column header.
2. Choose from predefined metrics and select a model for scoring (see Figure 14).
3. Alternatively, select `Define New` to create a custom metric. If creating a custom metric, define the prompt name and prompt text (see Figure 15).
4. Click the `Score` button to start scoring. The results appear as shown in Figure 16. You can hover over the scores or click on them to view more details. Each metric (for example, Bugs, Evolvability, Optimisation, Quality, and Score) is displayed along with an average score.
Figure 13: Open the scoring panel for a snippet
Figure 14: Choose scoring metrics
Figure 15: Custom Score
Figure 16: Review snippet scoring results
### Step 7: Explore with Contextual Chat
Use the chat insights to better understand your code before making optimisation decisions.
1. Select a target (identified by the file path in the location column) to open the context-aware chat panel (see Figure 17).
2. Ask Artemis chat questions. Example questions:
- "What does this function do?"
- "How can I improve the performance of this code?"
- "Explain the logic in this section"
- "What are potential issues with this implementation?"
Figure 17: Chat with Artemis about the current file
### Step 8: Generate One-Shot Code Updates
1. Click the Create (plus) icon for a target to open the version generation dialog (see Figure 18).
2. Select the mode `LLM`.
3. Update the prompt, select the model (for example, Qwen 3 4B), and click the `Generate Versions` button.
4. Review the optimised code snippet, checking the differences. This score reflects the difference between the original score and the optimised score.
5. Click `Validate` to run tests or compile steps through the registered runner (see Figure 20). The runner executes the validation commands locally and reports results.
6. If validation passes, you can proceed to integrate the optimisation. If validation fails, review the errors and consider regenerating the code with an updated prompt.
7. Integrate the optimisation into your code through a pull request (see Step 10).
**Note:** To perform one-shot code optimisation for all targets at once, click the versions icon next to the "Version" column header in the targets table. This opens the same version generation dialog for bulk optimisation.
Figure 18: Click the Create icon to generate a new version
Figure 19: Configure a one-shot update with Qwen 3 4B
Figure 20: Validation result from the local runner
### Step 9: Produce Multi-Version Optimisations with Artemis Intelligence
1. Click the `Create` icon (see Figure 21) in the row for the target code. This opens the version generation dialog.
2. Select the mode `Artemis Intelligence` (see Figure 22).
3. Configure the version settings in the dialog (see Figure 22):
- Update the `Prompt`. We provide a default prompt, but incorporating domain knowledge will help guide the optimisation.
- Select `Models`. Multiple models can be applied for a single optimisation using `Artemis Intelligence`.
4. Click `Configuration` (located in the top left corner within the Artemis Intelligence option; see Figure 23). Configure the following options:
- Select **Executable Code** and **Runner**. These can be updated in project Settings (see Step 2).
- Specify **Score criteria**. Multiple criteria can be selected, and the optimisation will be treated as a multi-objective optimisation.
- **Note:**
- You can update the Score Prompt Name and Prompt Text by clicking **View**.
- You can also add custom score criteria by clicking **Define New**.
5. Click the back arrow (top left corner of Figure 23) to return to the version generation dialog. Once you are satisfied with the Artemis Intelligence settings, click `Generate Versions` to start the Artemis Intelligence engine.
6. Optimisation versions will start being generated and populated (see Figure 24). Each row represents one optimisation version. Click a version to view code differences. Options are available on the right, including an agentic chat.
7. Each optimised code version displays the following information and options (see Figure 25):
- **Version ID**: A unique identifier for the code version (for example, `A-gen1pop0-f72ee`).
- **Change indicators**: Green indicators (for example, `+17`) show lines added, and red indicators (for example, `-1`) show lines removed compared to the original code.
- **Three vertical dots menu**: Click to access integration options, including creating changesets or pull requests (see Step 10).
- **`+` icon**: Click to generate additional optimisations using LLMs or Artemis Intelligence, starting from this code version as the base.
- **Scale icon**: Click to perform scoring and view a relative score comparing this version to the original code.
- **Play icon**: Click to validate the code snippet by running tests or compile steps through the registered runner.
- **Score Values**: Relative scores comparing the optimised version to the original. The first value is the average of all scores, followed by individual objective scores (for example, Compatibility, Equivalence, and Performance).
8. Click `Validate` to run tests or compile steps through the registered runner (see Step 2 for runner setup).
9. Integrate the optimisation into your code through a pull request (see Step 10).
Figure 21: Open the Create menu to start version generation
Figure 22: Launch Artemis Intelligence for the target
Figure 23: Configure runner actions and scoring
Figure 24: Compare generated optimisation versions
Figure 25: One Code Version
### Step 10: Integrate Optimisations
1. Click the options icon (three vertical dots) next to the optimised version to access integration options (see Figure 26). Available options include:
- **Download the optimised file**: Download only the specific optimised file.
- **Download the project**: Download the entire project with the optimised file integrated.
- **Create a changeset**: Create a changeset that you can use to generate a pull request in your Git repository. This is the recommended method for integrating optimisations into your codebase.
- **Delete the version**: Remove this optimisation version.
2. If you choose to create a changeset, follow the prompts to configure and generate a pull request that integrates your optimisations into your Git repository. For more details on changesets, see [Changesets](../../features/changeset.md).
Figure 26: Version options menu
## Next Steps
- Learn more about [changesets](../../features/changeset.md) to integrate optimisations into your Git repository
- Learn how to [validate code](../../optimization/code-validation/code-validation-overview.md) using custom benchmarks
- Explore [Artemis Intelligence](../../features/artemis-intelligence.md) for advanced multi-version optimisation
- Use [Code Audit](./audit.md) to identify and fix code quality issues
- Explore the [Planning Agent](./planning.md) for strategic feature development
- Use [Agentic Chat](./agentic-chat.md) to explore your codebase with RAG-powered search
---
## Agentic Planning (BETA)
Use this workflow to build strategic delivery plans with Artemis Planning Mode. All interactions run on your locally deployed instance using the Qwen 3 4B model, ensuring your project ideas remain private.
## Prerequisites
- Artemis is installed on a high-performance Intel® laptop with local GPUs (see [Deployment Options](../../deployment/deployment-options.md)).
- All large language models run locally (this example uses the Qwen 3 4B model).
- Internet access is optional; all processing runs directly on your local hardware.
## Outline
This guide covers the following steps:
- **Step 1:** [Launch the Planning Agent](#step-1-launch-the-planning-agent): Access the planning agent through existing repositories, scan mode, or new projects
- **Step 2:** [Create Plan](#step-2-create-plan): Enter prompts and answer questions to generate structured development plans
- **Step 3:** [Track Progress](#step-3-track-progress): Inspect, validate, and publish plan items to Git
- **Step 4:** [Project Ready](#step-4-project-ready): Download and verify your completed project from GitHub
- **Step 5:** [Continue Development](#step-5-continue-development): Use Artemis Intelligence, planner, and code audit to extend functionality
## Workflow
### Step 1: Launch the Planning Agent
You can access the Planning Agent through different methods:
1. **For an existing repository**:
- Go to `Build > Plans` to extend the functionality of an existing project using the Planning Agent.
- This allows you to add new features or improvements to your existing codebase.
2. **From Scan mode**:
- When reviewing scan results, select an issue and choose the planning option to fix bugs using planning mode.
- The Planning Agent creates a structured plan to address the identified issue.
3. **Create a new project**:
- Go to `Projects` and click `Plan New Repo` to create a new project using the Planning Agent.
- Choose `New Plan` to start planning from scratch.
- Enter a description of what you want to build, and the agent guides you through the planning process.
### Step 2: Create Plan
1. Enter an initial prompt describing what the project should include, including the main purpose, key features, technology stack, and any specific requirements or constraints. The Planning Agent asks detailed questions about the task to help define the scope (see Figure 1).
2. Answer the questions to provide project details. The agent processes all prompts locally through your language model (for example, Qwen 3 4B), ensuring your project ideas remain private.
3. The agent generates a structured plan consisting of:
- **Parent tasks**: High-level features or components
- **Sub-plans**: Detailed implementation steps for each parent task
- **Dependencies**: Relationships between tasks
4. Each sub-plan includes:
- **Ownership**: Whether the task is for the user or can be automated by the agent
- **Success criteria**: How to determine if the task is complete
- **Recommended sequencing**: The order in which tasks should be executed
Figure 1: Planning agent in action
### Step 3: Track Progress
1. Review the generated plan items. Inspect each sub-plan to ensure it meets your requirements.
2. For each sub-plan, you can:
- **Validate**: Mark the plan as reviewed and approved
- **Publish to Git**: Push the plan and generated code to your Git repository
- **Request revisions**: Ask the Planning Agent to modify or refine the plan
3. Use the plan dashboard to track and update statuses:
- **Draft**: Plan is being developed or reviewed
- **In Progress**: Plan is being executed
- **Published**: Plan has been completed and pushed to Git
4. Convert completed sub-plans into standalone tasks or optimisation targets for historical tracking and future reference.
### Step 4: Project Ready
1. Once the plan is complete and published, your project is available on GitHub in the repository you specified during planning.
2. Download the project and run it locally to verify everything works as expected.
3. Verify that all features from the plan have been implemented correctly.
4. Test the application to ensure it meets the success criteria defined in your plan.
5. If issues are found, return to the planning interface to create additional plans for fixes or improvements.
### Step 5: Continue Development
After your initial project is complete, you can continue development using various Artemis workflows:
1. **Optimise existing code**: Use [Artemis Intelligence](./optimisation.md#step-9-produce-multi-version-optimisations-with-artemis-intelligence) or [One-Shot LLM](./optimisation.md#step-8-generate-one-shot-code-updates) to generate code versions aligned with the plan and improve performance.
2. **Add new features**: Use the Planning Agent to add new features to your project. Create a new plan describing the feature, and the agent generates a structured implementation plan.
3. **Ensure code quality**: Use [Code Audit](./audit.md) to review code quality and identify potential issues. Fix any issues found before deploying to production.
4. **Explore your codebase**: Use [Agentic Chat](./agentic-chat.md) to ask questions about your project and understand how different components work together.
## Next Steps
- Explore the [Plans overview](../../build/plans.md) for advanced plan management features.
- Learn how to convert planning outcomes into [Standalone tasks](../../build/standalone.md).
- Review the [Build overview](../../build/overview.md) to understand how planning connects with other build workflows.
- Use [Standalone Optimisation](./optimisation.md) to implement and optimise your code.
- Run [Code Audit](./audit.md) to ensure code quality and identify issues.
---
## Migrating a Credit Risk Model from SAS to Python
:::tip Videos: See the Complete Migration Workflow
- **[Original SAS Credit Risk Model](https://youtu.be/lUqYflIKCJk)** - See the baseline SAS implementation
- **[Import and Create Migration Plan](https://youtu.be/T8tyY_ashvQ)** - Import your SAS project into Artemis
- **[Generate Migration Plan](https://youtu.be/Y9qv3RikS5E)** - Create a structured migration plan
- **[Execute Migration Tasks](https://youtu.be/dAo2EQMtSEw)** - Translate SAS to Python step by step
- **[Validation and Verification](https://youtu.be/3P_8K-rr41A)** - Verify Python matches SAS output
:::
## Project Overview
**Project Name:** SAS Credit Risk Model Migration
**Languages:** SAS → Python
**Description:** This guide demonstrates how to use Artemis Planning Agent to migrate a credit risk model from SAS to modern Python. The model uses real-world credit data and logistic regression for credit default prediction. This tutorial shows how to maintain model accuracy while improving code maintainability. Finally, we use the Artemis Intelligence Optimiser to generate new features and boost model performance.
**Repository:** [turintech/sas-migration](https://github.com/turintech/sas-migration)
**Branches:**
- [Initial (SAS)](https://github.com/turintech/sas-migration/tree/initial) - Original SAS credit risk model
- [Final (Python)](https://github.com/turintech/sas-migration/tree/final) - Migrated Python implementation
## Outline
This guide covers the following steps:
- **[Migration Workflow](#migration-workflow)** - Understand the systematic migration process
- **[Where is SAS Used?](#where-is-sas-used)** - Understand the context and industries relying on SAS
- **[Starting Point: The SAS Model](#starting-point-the-sas-model)** - Review the baseline credit risk model
- **[Step 1: Import and Create Migration Plan](#step-1-import-and-create-migration-plan)** - Import your SAS repository and generate a migration plan
- **[Step 2: Execute Data Migration Tasks](#step-2-execute-data-migration-tasks)** - Translate SAS DATA steps to pandas operations
- **[Step 3: Migrate Model Training](#step-3-migrate-model-training)** - Convert PROC LOGISTIC to statsmodels
- **[Step 4: Validation and Verification](#step-4-validation-and-verification)** - Verify Python matches SAS output
- **[Results and Benefits](#results-and-benefits)** - Review technical and business outcomes
## Migration Workflow
```mermaid
flowchart LR
subgraph Input
A[SAS Codebase]
end
subgraph Artemis["Artemis Planning Agent"]
B[Import & Analyze] --> C[Generate Plan]
C --> D[Execute Tasks]
D --> E[Validate Results]
end
subgraph Output
F[Python Codebase]
end
A --> B
E --> F
style A fill:#ffcdd2
style F fill:#c8e6c9
style Artemis fill:#e3f2fd
```
The migration follows Artemis's systematic workflow:
1. **Import & Analyze** - Import your SAS repository and let Artemis analyze the codebase
2. **Generate Plan** - Answer clarifying questions to generate a structured migration plan
3. **Execute Tasks** - Translate SAS code to Python step by step
4. **Validate Results** - Verify Python output matches SAS within tolerance
## Where is SAS Used?
SAS has been an enterprise standard for analytics for over 40 years, powering business-critical systems across industries, but faces increasing competition from newer and more open tooling such as Python and R.
```mermaid
graph LR
SAS[SAS Analytics]
SAS --> FS[Financial Services Credit Risk • Fraud Detection Regulatory Reporting]
SAS --> HC[Healthcare Clinical Trials Patient Analytics]
SAS --> GOV[Government Census Data Policy Analysis]
SAS --> RET[Retail Customer Analytics Demand Forecasting]
style FS fill:#bbdefb
```
This tutorial focuses on financial services credit risk modeling, demonstrating how Artemis Planning Agent enables systematic, verifiable migration while maintaining model accuracy.
## Starting Point: The SAS Model
The baseline SAS model is a production-ready credit risk scoring system for evaluating credit applicants.
### Prediction Target
The model predicts the probability that a credit applicant will experience **serious delinquency** (90+ days past due or worse) within the next 2 years. This is a binary classification problem: default vs. no default.
### Capabilities
- Complete pipeline: data loading, feature engineering, training, validation, scoring
- Risk scoring system: 300-850 FICO-like scale with risk grades (A-F)
- Lending recommendations: Approve/Review/Decline based on risk grade
- Comprehensive metrics: ROC curves, confusion matrices, decile analysis, calibration plots
- Production-ready outputs: Model coefficients, validation reports, Kaggle submission files
### Model Architecture
- **Algorithm:** Logistic regression with stepwise variable selection (PROC LOGISTIC)
- **Selection criteria:** p-value thresholds of 0.05 for entry and stay
### Data
- **Source:** [Kaggle "Give Me Some Credit" competition](https://www.kaggle.com/c/GiveMeSomeCredit) dataset
- **Size:** 150,000 credit applicant records
- **Split:** 70% training (105,000) / 30% validation (45,000)
- **Features:** 10 original features + 40+ engineered features
- Core: Age, income, credit utilization, debt ratio
- Late payments: 30-59, 60-89, and 90+ day delinquencies
- Risk flags: High utilization, high debt, low income
- Engineered: Financial health score, log transformations, interaction features
### Baseline Performance
- **Validation AUC-ROC:** 0.8564 (excellent discrimination)
- **Validation Accuracy:** 93.62%
- **Validation Precision:** 56.90%
- **Validation Recall:** 20.08%
- **Validation F1-Score:** 0.2968
- **Gini Coefficient:** 0.7128
- **Population Stability Index (PSI):** 0.0013 (excellent stability)
**Example SAS Code:**
```sas
/* Model Training with Stepwise Selection */
proc logistic data=work.model_features_train descending;
model default_flag =
credit_utilization_capped debt_ratio_capped
num_late_30_59 num_late_60_89 num_late_90_plus
age monthly_income log_monthly_income
flag_high_utilization flag_serious_delinquency
financial_health total_risk_flags
age_income_interaction
/ selection=stepwise slentry=0.05 slstay=0.05;
output out=work.scored predicted=probability;
store work.logit_model;
run;
/* Generate Risk Scores */
data work.risk_scores;
set work.scored;
credit_risk_score = round(600 + 250 * (1 - probability));
if credit_risk_score >= 750 then risk_grade = 'A';
else if credit_risk_score >= 700 then risk_grade = 'B';
/* ... additional risk grades ... */
run;
```
## Step 1: Import and Create Migration Plan
Import your SAS repository into Artemis as a new project, then activate the Planning Agent.
The Planning Agent analyzes your SAS code and asks clarifying questions:
- Which Python libraries do you prefer? (pandas, scikit-learn, etc.)
- Should we match SAS output exactly or allow optimizations?
- What validation approach do you want?
- Are there specific business constraints?
After your input, the agent generates a structured migration plan with hierarchical tasks, success criteria, and dependencies.
## Step 2: Execute Data Migration Tasks
The plan breaks migration into manageable tasks. First, translate SAS DATA steps to pandas operations.
**Before (SAS):**
```sas
data work.features;
set work.raw_data;
debt_ratio_category =
case
when debt_ratio < 0.3 then 'Low'
when debt_ratio < 0.6 then 'Medium'
else 'High'
end;
run;
```
**After (Python):**
```python
import pandas as pd
def engineer_features(df):
"""Translate SAS feature engineering to pandas"""
df = df.copy()
# Debt ratio categorization
df['debt_ratio_category'] = pd.cut(
df['debt_ratio'],
bins=[0, 0.3, 0.6, float('inf')],
labels=['Low', 'Medium', 'High']
)
return df
features_df = engineer_features(raw_data)
```
## Step 3: Migrate Model Training
Convert SAS PROC LOGISTIC to statsmodels Logit while maintaining identical model specifications.
**Before (SAS):**
```sas
proc logistic data=work.features;
model default_flag = debt_ratio income age;
output out=predictions p=predicted_prob;
run;
```
**After (Python):**
```python
import statsmodels.api as sm
# Prepare features
X = features_df[['debt_ratio', 'income', 'age']]
X = sm.add_constant(X) # Add intercept
y = features_df['default_flag']
# Train model
model = sm.Logit(y, X)
results = model.fit()
# Generate predictions
predictions = results.predict(X)
```
## Step 4: Validation and Verification
Artemis validates that the Python model produces equivalent results to the SAS original.
**Validation checks include:**
- Prediction equivalence (Python predictions match SAS within tolerance)
- Performance metrics match (ROC-AUC, accuracy, F1 score)
- Feature importance comparison
- Model coefficients alignment
**Model Performance Comparison:**
The migration achieves functional equivalence, with all metrics closely matching:
| Metric | SAS Baseline | Python Migration | Difference |
|--------|--------------|------------------|------------|
| AUC-ROC | 0.8564 | 0.8634 | ~ 0.006 |
| Accuracy | 0.9362 | 0.9350 | ~ 0.001 |
| Precision | 0.5690 | 0.5705 | < 0.001 |
| Recall | 0.2008 | 0.1938 | ~ 0.006 |
| F1-Score | 0.2968 | 0.2893 | ~ 0.006 |
| Gini Coefficient | 0.7128 | 0.7269 | ~ 0.01 |
This validates that the Python implementation produces equivalent results to the SAS original, maintaining model accuracy while improving code maintainability.
## Results and Benefits
This migration delivers:
**Technical Success:**
- Functionally equivalent Python implementation
- Performance maintained or improved
- Clean, maintainable code following Python best practices
**Business Impact:**
- Improved maintainability with modern Python
- Integration-ready for ML infrastructure
- Team productivity gains (Python skills more widely available)
**Key Capabilities Demonstrated:**
- **Verifiability**: Automated validation at each step ensures correctness
- **Observability**: Real-time progress tracking and metrics throughout migration
- **Optimization**: Improvements beyond simple translation using Artemis Intelligence
## Conclusion
Artemis Planning Agent transforms complex SAS-to-Python migrations into a systematic, verifiable process. By combining intelligent planning with automated validation and optimization, Artemis allows fast verifiable migration while ensuring model accuracy and improving code quality. Whether migrating individual models or entire model suites, Artemis makes legacy modernization efficient and reliable.
## Related Documentation
- [Planning Agent Overview](../../build/plans.md)
- [Code Optimization](../../optimization/overview.md)
- [Artemis Intelligence](../../features/artemis-intelligence.md)
- [Runner setup](../../features/artemis-runner.md)
---
## Makefile Optimization
## Project Overview
**Project Name:** Wavelet Transform
**Language:** C/C++ (Makefile Build System)
**Repository:** [github.com/Dianababaei/wavelet-transform](https://github.com/Dianababaei/wavelet-transform)
**Description:**
The *Wavelet Transform* project leverages a Makefile-based build system to compile C/C++ source files for performing signal processing operations such as wavelet decomposition and reconstruction.
This optimization effort focuses on improving the Makefile itself — reducing build time, enhancing dependency management, and improving maintainability for long-term scalability.
## What Does a Makefile Do?
A **Makefile** is used by the `make` build automation tool to define how a project is compiled and linked.
It specifies:
* **Dependencies** between source and output files
* **Build rules** describing how to generate targets efficiently
A well-structured Makefile minimizes redundant compilations and accelerates rebuild times — key goals of this optimization.
## Optimization Results
After 10 evaluation cycles, the optimized Makefile achieved noticeable improvements in build efficiency and structure:

## Modified Files
The optimization primarily focused on refactoring and improving the `Makefile`:

## Artemis Optimization Workflow

The Makefile optimization followed the **Artemis Intelligence** workflow, consisting of five systematic phases:
### 1. Import your codebase
The original Makefile from the [Wavelet Transform repository](https://github.com/Dianababaei/wavelet-transform) was uploaded to Artemis.
Learn more: [Code Targeting](../../../project-setup/import-codebase.md)
### 2. Code Targeting
Since the optimization target was the Makefile itself, the file was extracted using Artemis’s *file-by-file* inspection mode.
Learn more: [Code Targeting](../../../optimization/code-targeting/overview.md)
### 3. Version Generation
A custom prompt was provided to the Artemis agent to generate optimized versions of the Makefile.
**Prompt:**
> “Analyze and optimize this Makefile. Focus on reducing build time, improving dependency tracking, eliminating redundant compilation, and increasing maintainability. Suggest specific refactorings using variables, pattern rules, phony targets, and proper build structure.”
Learn more: [Version Generation](../../../optimization/version-generation/overview.md)
### 4. Evaluate new versions
Each generated version was validated using a [runner](../../../features/artemis-runner.md) and see real value of performance metrics to ensure correctness and measurable improvement.
Learn more: [Code Validation](../../../optimization/code-validation/code-validation-overview.md)
### 5. Code Optimization
A final optimization step compared all generated variants to determine the **best-performing combination** in terms of speed.
Learn more: [Code Optimisation](../../../optimization/code-optimization/overview.md)
## Conclusion
Through the **Artemis intelligent optimization workflow**, the Makefile of the *Wavelet Transform* project was successfully refined for both **performance** and **maintainability**.
This case demonstrates how even foundational components like build systems can benefit from **AI-driven refactoring**, enabling faster development cycles and more efficient engineering workflows.
---
## Math Odyssey Optimization
## Project Overview
**Goal:** Optimize CrewAI agents for 37% cost reduction on mathematical problem-solving through prompt and parameter optimization
**Before:** [Baseline CrewAI agent configuration](https://github.com/turintech/math-odyssey-optimisation/blob/main/gen_formalizer/src/gen_formalizer/crew.py) (100,000 token limits, verbose prompts)
**After:** [Optimized agent configuration](https://github.com/turintech/math-odyssey-optimisation/blob/main/gen_formalizer/src/gen_formalizer/crewOptimized.py) (14,000/4,000 token limits, refined prompts)
**Target Users:** AI teams deploying agentic systems at scale, enterprises optimizing AI costs
**Use Cases:**
- Cost optimization for production AI agents
- Multi-agent framework configuration and tuning
- Mathematical reasoning optimization
- Enterprise-scale AI deployment with cost controls
## Background
Math Odyssey is a comprehensive benchmark with 387 mathematics problems spanning algebra, calculus, geometry, and number theory [Fang et al., 2024]. These problems serve as proxies for real-world business tasks requiring complex text comprehension, logical reasoning, and precise calculations.
The optimization challenge: CrewAI has 12+ specialized prompts and 20+ configurable parameters, creating >10^20 possible configurations. Manual tuning is impractical. Artemis automates intelligent configuration discovery, transforming general-purpose frameworks into task-specific optimized systems.
**Framework:** CrewAI (used by 60% of Fortune 500 companies) [CrewAI Inc., 2025]
**Base Model:** Gemini 2.5 Flash (efficient, cost-effective)
**Optimization Method:** Artemis with 3 cycles, 5 instances per cycle using genetic algorithms
## Implementation
### Phase 1: Prompt Optimization (Agent Configuration)
Artemis evolved baseline prompts from verbose, exploratory instructions to action-focused, precise definitions. The agent configuration controls role definition, goal framing, and operational parameters.
**Baseline agents.yaml:**
```yaml
researcher:
role: >
Math solver.
goal: >
Try to research this problem {topic}.
backstory: >
You are pretty good at math
reporting_analyst:
role: >
You are an Automated Grading System designed to evaluate mathematical solutions with precision.
goal: >
Evaluate the response with precision, comparing it to the correct answer. Determine if the solution is correct.
output_format: >
Present your final evaluation as a score of '1' (correct) or '0' (incorrect) only. Do not include any explanatory text or justification.
backstory: >
You are a specialized verification algorithm optimized for mathematical equivalence detection across various forms and notations.
```
**Optimized agentsOptimized.yaml:**
```yaml
researcher:
role: >
Math solver.
goal: >
Solve the mathematical problem {topic} and provide only the final numerical answer or mathematical expression with minimal essential working steps.
Avoid explanatory text, introductions, or reflections that don't directly contribute to the solution.
backstory: >
You are a mathematics expert capable of solving various math problems.
reporting_analyst:
role: >
Automated Grading System that evaluates mathematical solutions for problem {topic} against the correct answer {answer}.
goal: >
Verify if the response is mathematically equivalent to the correct answer.
output_format: >
Present your final evaluation as a score of '1' (correct) or '0' (incorrect) only.
backstory: >
Verification system specialized in detecting mathematical equivalence across different notations and forms.
```
**Key changes:** From exploratory ("try to research") to direct action ("Solve... with minimal essential working steps"). Prompts are refined for clarity and efficiency.
### Phase 2: Task Optimization
Task definitions control what agents actually do and what outputs are expected. Optimization refines these from exploratory to direct problem-solving.
**Baseline tasks.yaml:**
```yaml
research_task:
description: >
look up the topic {topic} and learn about it.
expected_output: >
Please give us information about the topic and an answer to the {topic}.
agent: researcher
```
**Optimized tasksOptimized.yaml:**
```yaml
research_task:
description: >
Directly solve the mathematical problem: {topic}
expected_output: >
Provide the solution to the mathematical problem with minimal explanation.
Include all necessary calculations and the final answer.
agent: researcher
```
**Key changes:** From learning and research to direct problem-solving. Minimal explanation requirement reduces token overhead.
### Phase 3: Parameter Optimization (Token Limits and Configuration)
CrewAI's configurable parameters enable fine-tuning of model behavior. The largest efficiency gain comes from intelligent token limits that prevent runaway costs.
**Baseline crew.py:**
```python
@agent
def researcher(self) -> Agent:
return Agent(
config=self.agents_config['researcher'],
verbose=True,
temperature=0.0,
llm=LLM(model='gemini/gemini-2.5-flash', max_tokens=100000)
)
@agent
def reporting_analyst(self) -> Agent:
return Agent(
config=self.agents_config['reporting_analyst'],
verbose=True,
temperature=0.0,
llm=LLM(model='gemini/gemini-2.5-flash', max_tokens=100000)
)
```
**Optimized crewOptimized.py:**
```python
@agent
def researcher(self) -> Agent:
return Agent(
config=self.agents_config['researcher'],
verbose=True,
temperature=0.0,
llm=LLM(model='gemini/gemini-2.5-flash', max_tokens=14000)
)
@agent
def reporting_analyst(self) -> Agent:
return Agent(
config=self.agents_config['reporting_analyst'],
verbose=True,
temperature=0.0,
llm=LLM(model='gemini/gemini-2.5-flash', max_tokens=4000)
)
```
**Key changes:** Token limits reduced from 100,000 → 14,000 (researcher) and 100,000 → 4,000 (reporting_analyst). These hard cost limits prevent token runaway while maintaining solution quality through refined prompts.
## Results
**Cost Reduction:**

- **37% average cost reduction** - Significant efficiency gains across evaluation costs

- **36% median cost reduction** - Consistent improvements across entire problem set, not isolated outliers
**Performance Maintained:**

- **~6% accuracy reduction** - Minimal and not statistically significant
- Demonstrates optimal cost-performance balance through intelligent configuration
**Key Achievements:**
- 37% cost reduction (average tokens per problem)
- 36% median cost reduction (consistent across problems)
- ~6% accuracy reduction (not statistically significant)
- Maintained strong problem-solving capability while drastically reducing token usage
## Repository
Complete source code available at: [github.com/turintech/math-odyssey-optimisation](https://github.com/turintech/math-odyssey-optimisation)
**Key configuration files:**
- Baseline: `gen_formalizer/src/gen_formalizer/config/agents.yaml`
- Optimized: `gen_formalizer/src/gen_formalizer/config/agentsOptimized.yaml`
- Baseline: `gen_formalizer/src/gen_formalizer/crew.py`
- Optimized: `gen_formalizer/src/gen_formalizer/crewOptimized.py`
---
## References
* Fang, M., Wan, X., Lu, F., Xing, F., & Zou, K. (2024). "MathOdyssey: Benchmarking Mathematical Problem-Solving Skills in Large Language Models Using Odyssey Math Data." *arXiv preprint arXiv:2406.18321.*
* CrewAI Inc. (2025). CrewAI (Version 0.177.0) [Computer software]. Retrieved from https://github.com/crewAIInc/crewAI
---
## NanoChat Optimization
## Project Description
NanoChat is a lightweight, educational LLM framework created by Andrej Karpathy that provides a minimal, end-to-end pipeline for building language models. This case study demonstrates how Artemis Intelligence was used to systematically optimize NanoChat's performance across training and inference workflows.
**Project Repository:** [github.com/karpathy/nanochat](https://github.com/karpathy/nanochat)
## Goals
The purpose of this project is to apply Artemis Intelligence to NanoChat in order to:
* **Optimize performance**
Improve training speed, inference latency, memory usage, and KV-cache efficiency.
* **Benchmark and validate improvements**
Measure *before vs after* using automated profiling.
* **Support feature experimentation**
Use the Planner to propose and integrate new features (sampling, profiling hooks, training configs).
## Optimization Workflows
### 1. Identify and fix bottlenecks
[Optimise](../../optimization/overview.md) → [Add Target](../../optimization/code-targeting/overview.md) → [Agent Targeting](../../optimization/code-targeting/agent-targeting.md) → Detect Bottlenecks → [Plan to Fix](../../build/Plan/plan-overview.md)
### 2. Discover new feature opportunities
Using the [Planner's **"add new feature"**](../../build/Plan/plan-overview.md) instruction.
### 3. Scan for critical issues
[Scan](../../scan/overview.md) → [Plan to Fix](../../build/Plan/plan-overview.md)
## Optimizations Implemented
| Optimization | Problem Addressed | Solution Applied |
|--------------|-------------------|------------------|
| Auto Batch Size Discovery | Low GPU utilization (~35%) | Exponential search + binary refinement with safety margins |
| KV-Cache for Inference | O(T²) attention recomputation | Prefill once, cache key-value pairs for autoregressive decoding |
| torch.compile Integration | Python overhead, unoptimized kernels | Static shape compilation with operator fusion |
| Token Broadcasting Fix | Duplicate tokens across sequences | Independent sampling per sequence |
## Performance Results
### Training Optimizations
| Optimization | Training Speedup | Training Time Saved | Notes |
|--------------|------------------|---------------------|-------|
| Auto Batch | 1.90× (SFT), 1.04× (Base/Mid) | 47% / 4% | Maximizes GPU utilization |
| torch.compile | 1.67× | 40% | Operator fusion + static shapes |
| **Combined** | **3.17× (SFT), 1.74× (Base/Mid)** | **68% / 43%** | **Compound effect** |
### Inference Optimizations
| Configuration | Wall-Clock Time | Throughput | Speedup | Time Saved |
|--------------|-----------------|------------|---------|------------|
| Baseline (batch=1, no KV-cache) | 21.41s | 81.4 tok/s | 1.0× | - |
| Optimized (batch=93, with KV-cache) | 2.04s | 855.7 tok/s | **10.5×** | **91%** |
**Note:** Throughput-based calculations suggest 88× theoretical speedup (99% time saved), but we benchmarked **10.5× speedup (91% time saved)** in real wall-clock time. The difference is due to system-level overhead (memory management, kernel launches, synchronization).
### Combined Results Summary
* SFT Training → 68% time reduction (3.17× faster)
* Base/Mid Training → 43% time reduction (1.74× faster)
* Inference → 91% time reduction (10.5× faster)
## Detailed Optimizations
### 1. Auto Batch Size Discovery
**Artemis Detection:** Agent analysis revealed GPU utilization at only ~35% during SFT training, indicating severe under-batching.
**Overview**
Automated batch discovery using:
* Exponential growth
* Binary search
* 15% safety margin
* Batch caching
Discovery time: **~20 seconds**
**Why It Matters**
* Removes manual tuning (10–30 minutes)
* Prevents underutilization (batch=4 → ~35% GPU usage)
* Adapts to GPU, model, and sequence length
* SFT benefits dramatically (severely under-batched)
**SFT Training**
| Metric | Hardcoded | Auto Batch | Improvement |
|--------|-----------|------------|-------------|
| Throughput | 50,164 tok/s | 95,337 tok/s | **1.90×** |
| Time Saved | — | — | **47%** |
| Batch Size | 4 | **93** | **23× larger** |
| GPU Util | ~35% | ~92% | **+2.6×** |
**Base/Mid Training**
| Metric | Hardcoded | Auto Batch | Improvement |
|--------|-----------|------------|-------------|
| Throughput | baseline | baseline +4% | 1.04× |
| Time Saved | — | — | 4% |
:::note
The same auto-batching technique resulted in a 1.90× speedup for SFT but only 1.04× for base training, mainly because their initial configurations were different. Base/Mid training was already near optimal (batch size 32 → 64), while SFT began heavily under-batched (batch size 4 → 93), giving it much more room to improve.
:::
### 2. KV-Cache for Inference
**Artemis Detection:** Planner's feature discovery identified missing KV-cache implementation—a standard optimization in modern LLM inference pipelines.
**Problem**
Autoregressive decoding recomputes attention every step (O(T²)).
For 200 generated tokens → ~29,900 operations.
**Solution**
Cache keys/values:
* Prefill once
* Recompute only for new tokens
Complexity becomes **O(T)** (≈250 ops).
**Measured Real-World Performance**
Testing on NVIDIA A100-SXM4-80GB with 178.5M parameter model:
| Configuration | Wall-Clock Time | Throughput | Speedup |
|--------------|-----------------|------------|---------|
| Baseline (batch=1, no cache) | 21.41s | 81.4 tok/s | 1.0× |
| Optimized (batch=93, with cache) | 2.04s | 855.7 tok/s | **10.5×** |
**Benchmarked Time Saved: 91%**
**Why KV-cache Is Not Used in Training**
Training uses full-sequence teacher forcing, not autoregressive decoding.
### 3. torch.compile Integration
**Artemis Detection:** Agent analysis identified Python overhead and unoptimized kernel execution in training loops.
**Overview**
PyTorch 2.x graph compilation:
* Operator fusion
* Kernel specialization
* Removal of Python overhead
Using:
```python
model = torch.compile(model, dynamic=False)
```
**Measured Results (100-step benchmark)**
| Metric | No Compile | Compile | Improvement |
|--------|------------|---------|-------------|
| Total Time | 64.4s | 38.6s | **40% faster** |
| Throughput | 101,654 tok/s | 169,919 tok/s | **1.67×** |
**Why It Works**
* 3–4 kernels fused into 1
* Static shapes allow optimized kernels
* Removes slow Python loops
**Compilation requires discipline:** Static shapes enable dramatic speedups (1.67×) but require careful tensor management.
### 4. Token Broadcasting Bug Fix
**Artemis Detection:** Scan caught an edge case where the first sampled token was incorrectly duplicated across all sequences.
**Problem**
The first sampled token was duplicated across all sequences.
Effects:
* No gradient diversity
* Reduced effective batch size
* Poor generation quality
**Fix**
```python
tokens = torch.tensor([tokens] * micro_batch_size, device=device)
```
**Impact**
* 23× more unique samples
* Correct gradient accumulation
* Improved generation diversity
## Combined Performance Impact
### Training Pipeline
**SFT Training Results:**
| Configuration | Throughput | Speedup | Time Saved |
|--------------|------------|---------|------------|
| Baseline | 50,164 tok/s | 1.0× | - |
| + Auto Batch | 95,337 tok/s | 1.90× | 47% |
| + torch.compile | 159,213 tok/s | **3.17×** | **68%** |
**Base/Mid Training Results:**
| Configuration | Throughput | Speedup | Time Saved |
|--------------|------------|---------|------------|
| Baseline | baseline | 1.0× | - |
| + Auto Batch | +4% | 1.04× | 4% |
| + torch.compile | +77% | **1.74×** | **43%** |
### Inference Pipeline
| Configuration | Wall-Clock Time | Throughput | Speedup | Time Saved |
|--------------|-----------------|------------|---------|------------|
| Baseline (batch=1, no KV-cache) | 21.41s | 81.4 tok/s | 1.0× | - |
| Optimized (batch=93, with KV-cache) | 2.04s | 855.7 tok/s | **10.5×** | **91%** |
## Technical Environment
- **Hardware:** NVIDIA A100-SXM4-80GB
- **Model Size:** 178.5M parameters
- **Framework:** PyTorch 2.x with torch.compile
- **Precision:** BFloat16
- **Discovery Time:** ~20 seconds for batch size optimization
- **Benchmark Scripts:** `test_combined_optimizations.py`, `measure_torch_compile_realistic.py`
## Conclusion
Through systematic application of Artemis Intelligence workflows, NanoChat achieved:
- **3.17× faster SFT training** (68% time reduction)
- **1.74× faster base/Mid training** (43% time reduction)
- **10.5× faster inference** (91% time reduction)
- **Automated batch optimization** eliminating 10-30 minutes of manual tuning per configuration
The training pipeline optimizations proved most impactful, with auto-batching addressing severe GPU underutilization (35% → 92%) and torch.compile providing consistent 1.67× speedups. Inference optimizations delivered substantial improvements, with benchmarked 91% time reduction in production use.
These improvements make NanoChat more practical for real experimentation and research, while maintaining its transparent, hackable codebase designed for educational purposes.
---
## Optimizing Uber's Zap Logging Library
{/* :::tip Video: See the Complete Workflow
**[Watch the Zap Optimization Workflow](https://youtu.be/SR2LeMj_Zz0)**
See the complete optimization process from start to finish
::: */}
## Project Overview
**Project Name:** Uber Zap
**Language:** Golang
**Description:** Zap is a high-performance, structured logging library for Golang, developed by Uber. Designed for speed and efficiency, it is optimized for applications that require fast, low-latency logging with minimal overhead.
**Repository:** https://github.com/uber-go/zap
## Hardware Specifications

## Optimization Results
After 10 evaluation cycles, we achieved significant performance improvements:

## Modified Files
The optimization process identified and improved the following files:

## Optimization Workflow

The Zap optimization followed Artemis's systematic optimization workflow:
### 1. Code Targeting
Identified performance-critical sections of the Zap logging library for optimization using the Agent Analysis code extraction method.
Learn more: [Code Targeting](../../optimization/code-targeting/overview.md) and [Agent Targeting](../../optimization/code-targeting/agent-targeting.md)
### 2. Version Generation
Generated multiple optimized versions using AI-powered code transformation and Artemis Intelligence genetic algorithms.
Learn more: [Version Generation](../../optimization/version-generation/overview.md)
### 3. Evaluate new version
ach generated version was validated using a [runner](../../features/artemis-runner.md) and see real value of performance metrics to ensure correctness and measurable improvement.
Learn more: [Code Validation](../../optimization/code-validation/code-validation-overview.md)
### 4. Review and Compare
Analyzed the code changes across all generated versions to identify the best-performing variant.
Learn more: [Review and Compare](../../optimization/code-validation/review-and-compare-new-versions.md)
### 5. Code Optimisation
Applied the selected optimizations to create the final optimized version of the codebase.
Learn more: [Code Optimisation](../../optimization/code-optimization/overview.md)
## Conclusion
Through Artemis's systematic optimization approach, we successfully enhanced the performance of Uber's Zap logging library, demonstrating the platform's capability to optimize production-grade, performance-critical codebases written in Golang.